
Exploratory Data Analysis (EDA)
Part of the AI Engineer Roadmap
In short
Most failed models fail because of data nobody looked at closely: a column full of zeros, a leaked label, duplicates. EDA is the habit of looking before you train.
The systematic process of understanding a dataset's shape, distributions, missingness and relationships before modeling — the step that most determines whether your model will actually work.
Think of it like this
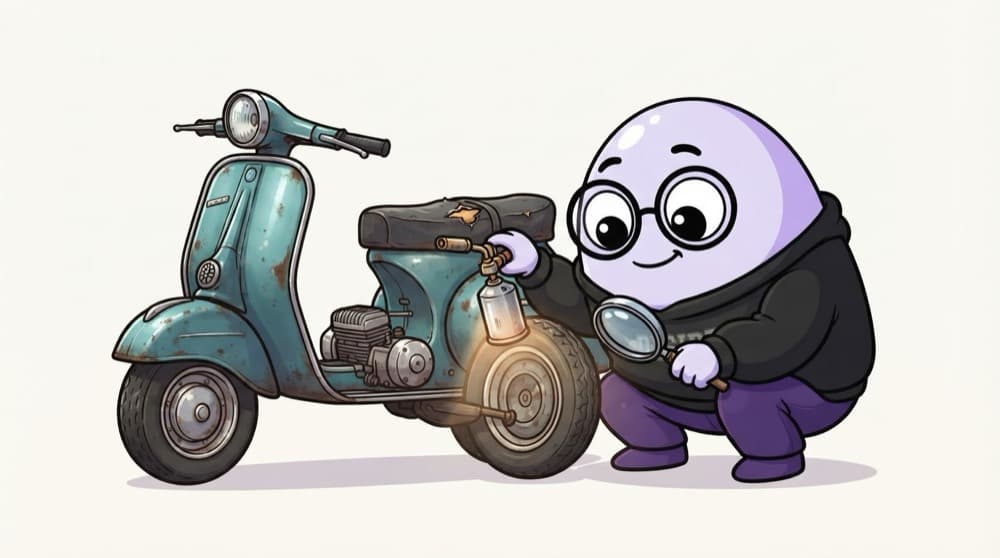
Checking a second-hand scooter
Before buying a used scooter, you check the tyres, look under the seat, kick-start it and ask for papers. You don't pay first and inspect later. EDA is that inspection for data: shape, gaps, odd values and patterns, before you trust it with a model.
Watch it happen
A first pass over any dataset
1/5Rows, columns, types. Is age stored as text? Is the date a real date?
The big ideas
What you need to know
Same checklist every time
shape, info, describe, missing share, duplicates, value counts. A routine catches things your eyes skip.
Start from the target
Check how the label is distributed. If 98% are 'no', accuracy will lie to you.
Hunt for leakage
A feature that predicts the target perfectly is usually information from the future. Find it before the model does.
Write findings as you go
A short list of observations is worth more than 40 unexplained charts.
See it in code
Walk through the code
1import seaborn as sns2 3df = sns.load_dataset("titanic")4 5print(df.shape)6df.info()7print(df.describe())8print(df.isna().mean().sort_values(ascending=False).head()) # share missing9print(df.duplicated().sum()) # duplicate rows10 11print(df["survived"].value_counts(normalize=True)) # target balance12print(df.groupby("sex")["survived"].mean()) # feature vs target13print(df.groupby("pclass")["survived"].mean())14df["age"].hist(bins=30)1/4Size, column types and summary numbers for every numeric column.
Ten lines that answer: how big is it, what's missing, are there duplicates, how balanced is the target, and which features matter.
Save yourself the pain
Common mistakes
Oops
Jumping straight to model.fit on a freshly loaded CSV.
Do this instead
Spend the first hour on EDA. It usually saves days of confused model debugging.
Oops
Making dozens of charts with no question in mind.
Do this instead
Ask one question per chart, like 'does fare affect survival?', and write the answer under it.
Your mission
EDA in 30 minutes
Quick check
A feature predicts the target with 99.9% accuracy on its own. What should you suspect first?
Go deeper
- 1Build a repeatable EDA checklist: shape, dtypes, missingness, distributions, correlations, outliers.
- 2Practice summarizing findings in plain language for a non-technical audience.
- 3Run a full EDA pass on a new dataset before ever training a model on it.
More topics at this stop
 NumPy Arrays & Vectorization
 Pandas DataFrames & Series
 Data Cleaning & Wrangling
 Handling Missing Data
 Merging & Joining Datasets
 GroupBy & Aggregation
 Matplotlib
 Seaborn
 Plotly (Interactive Charts)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
