Transformer Architecture
Part of the AI Engineer Roadmap
In short
GPT, BERT, Claude, Gemini, Whisper: all transformers. Once you see that a transformer is attention plus a small feed-forward network, stacked many times, the big names stop feeling mysterious.
The architecture built entirely around self-attention (no recurrence) that underlies GPT, BERT, Claude and virtually every modern LLM.
Think of it like this
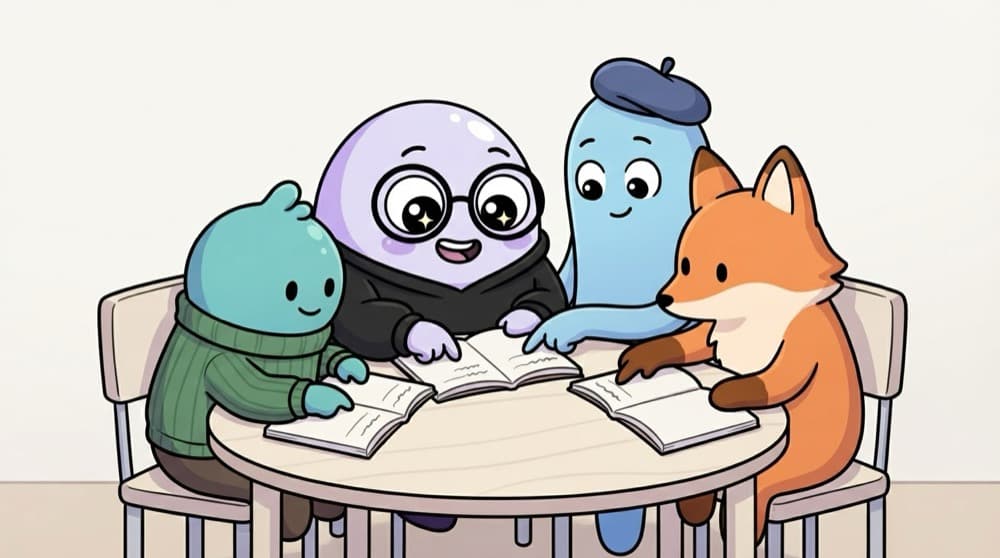
The group study table
In a relay, each person hears the message only from the one before. At a group study table, everyone reads everyone's notes at the same time, then goes off to think alone. Transformers work like the table: all tokens look at each other at once, then each is processed on its own.
Watch it happen
One trip through a transformer block
1/6Text is split into tokens, each mapped to an id from a vocabulary.
The big ideas
What you need to know
Parallel, not step by step
Unlike RNNs, all tokens are processed at once. That suits GPUs and lets models train on huge datasets.
Residuals keep it trainable
Each sub-layer's output is added to its input. Gradients get a shortcut, so very deep stacks still train.
Three family branches
Encoder-only (BERT) for understanding, decoder-only (GPT style) for generating, encoder-decoder (T5) for translation and summarising.
Causal masks for generation
Decoder models hide future tokens, so each position only attends to earlier ones. That's how they learn next-token prediction.
See it in code
Walk through the code
1import torch2import torch.nn as nn3 4layer = nn.TransformerEncoderLayer(d_model=64, nhead=4, dim_feedforward=256,5 batch_first=True)6encoder = nn.TransformerEncoder(layer, num_layers=2)7 8x = torch.randn(8, 20, 64) # 8 sentences, 20 tokens, 64 numbers each9out = encoder(x) # every token looks at every other token, in parallel10print(out.shape) # (8, 20, 64): same shape, richer meaning11 12causal = nn.Transformer.generate_square_subsequent_mask(20)13out_gpt_style = encoder(x, mask=causal) # each token sees only earlier tokens1/3One block: 4 attention heads over 64-wide vectors, a 256-wide feed-forward layer, stacked twice.
PyTorch ships the transformer block ready to use. The output keeps the input's shape, so blocks stack cleanly.
Save yourself the pain
Common mistakes
Oops
Thinking transformers understand word order on their own.
Do this instead
Attention ignores order. Positional encodings or embeddings must be added, or 'dog bites man' equals 'man bites dog'.
Oops
Assuming longer context is free.
Do this instead
Self-attention compares every token with every other, so compute and memory grow with the square of sequence length.
Your mission
Count the parts
Quick check
Why do transformers train faster than RNNs on GPUs?
Go deeper
- 1Study the Transformer diagram piece by piece: embeddings, attention, feed-forward, layer norm.
- 2Implement a minimal Transformer block from scratch (or follow a guided walkthrough like 'nanoGPT').
- 3Learn the difference between encoder-only (BERT), decoder-only (GPT) and encoder-decoder (T5) Transformers.
More topics at this stop
 Convolutional Neural Networks (CNNs)
 Pooling Layers
 Recurrent Neural Networks (RNNs)
 LSTMs & GRUs
 Sequence-to-Sequence Models
 Attention Mechanism
 Positional Encoding
 Transfer Learning
 Autoencoders
 Generative Adversarial Networks (GANs, Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
