In short
Sometimes you don't need Redis at all. A plain map inside your Node process is the fastest cache there is, with no network hop. The trick is knowing when that's enough.
Caching data directly in your application process's memory (e.g. a JS `Map`) — the fastest option, but limited to a single server instance and lost on restart.
Think of it like this
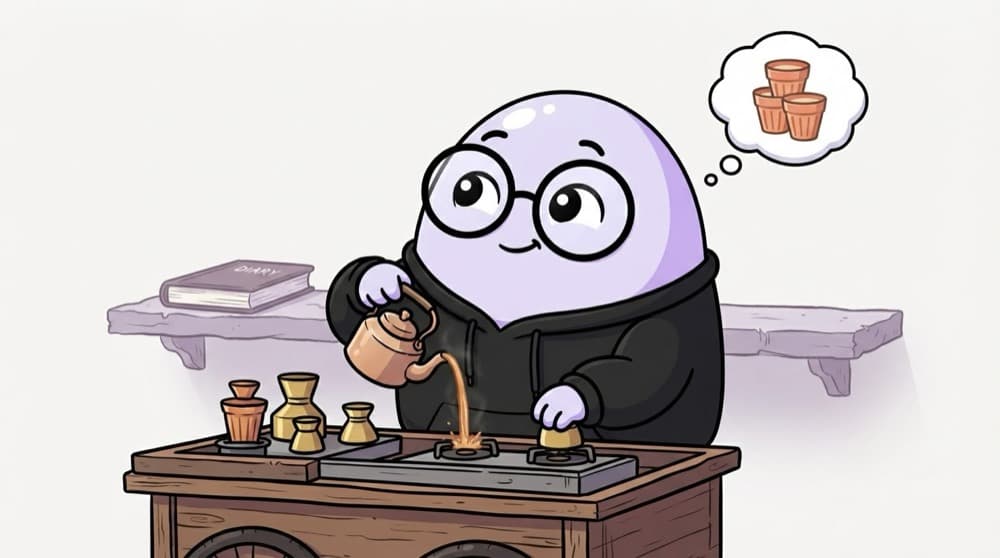
The chai wala's memory
The chai wala remembers that the regular at the corner wants less sugar and extra adrak. No notebook needed; it's instant. But when he takes leave, the stand-in knows nothing. In-memory caching is that memory: lightning fast, but inside one process only, and gone on restart.
Watch it happen
Where should this cache live?
In-process map
- No network call, just a lookup
- Each server keeps its own copy
- Lost when the process restarts
Redis
- One shared copy for all servers
- Survives app restarts and deploys
- A small network hop on each read
Use in-memory for small, rarely changing data like config or feature flags. Use Redis when servers must agree or the data is big.
The big ideas
What you need to know
Fastest possible read
A map lookup happens inside your process, with no network trip and no JSON parsing.
Always bound the size
An unbounded Map grows until the process runs out of memory. Use an LRU cache with a max size.
Copies can disagree
With four servers, each has its own cache. One may show old data while another shows the new.
A great first layer
For very hot keys, many apps check memory first, then Redis, then the database.
See it in code
Walk through the code
1import { LRUCache } from "lru-cache";2 3const settingsCache = new LRUCache<string, object>({4 max: 500,5 ttl: 60_000,6});7 8export async function getSettings(orgId: string) {9 const cached = settingsCache.get(orgId);10 if (cached) return cached;11 12 const settings = await db.settings.findByOrg(orgId);13 settingsCache.set(orgId, settings);14 return settings;15}1/3At most 500 entries, each valid for 60 seconds. When full, the least recently used entry goes.
This cache lives per process. With several instances or a clustered setup, each one keeps its own separate copy.
Save yourself the pain
Common mistakes
Oops
Using a plain object or Map with no size limit as a cache.
Do this instead
Memory grows forever and the process eventually crashes. Use lru-cache with max and ttl set.
Oops
Caching data in memory behind a load balancer and expecting every server to match.
Do this instead
The next request may land on a server with different data. Use Redis for anything that must match everywhere.
Your mission
Build a bounded cache
Quick check
Your app runs on 3 servers, each with its own in-memory cache. An admin updates a setting through server A. What happens?
Go deeper
- 1Build a simple in-memory cache with a Map and manual TTL expiry logic.
- 2Understand why in-memory caching breaks down once you run multiple server instances.
- 3Compare it to Redis: faster, but not shared or persistent.
More topics at this stop
 Caching Fundamentals
 Redis for Caching
 CDN Caching
 Cache Invalidation Strategies
 Cache-Aside Pattern
 Write-Through vs Write-Behind
 HTTP Caching Headers

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
