In short
If your monitoring runs on the same server as your app, it dies with the app and warns nobody. Uptime monitoring checks from outside, exactly like a real user would.
External services that periodically ping your API from outside your infrastructure and alert you the moment it becomes unreachable — your last line of defense for knowing about outages immediately.
Think of it like this
The friend who calls your shop
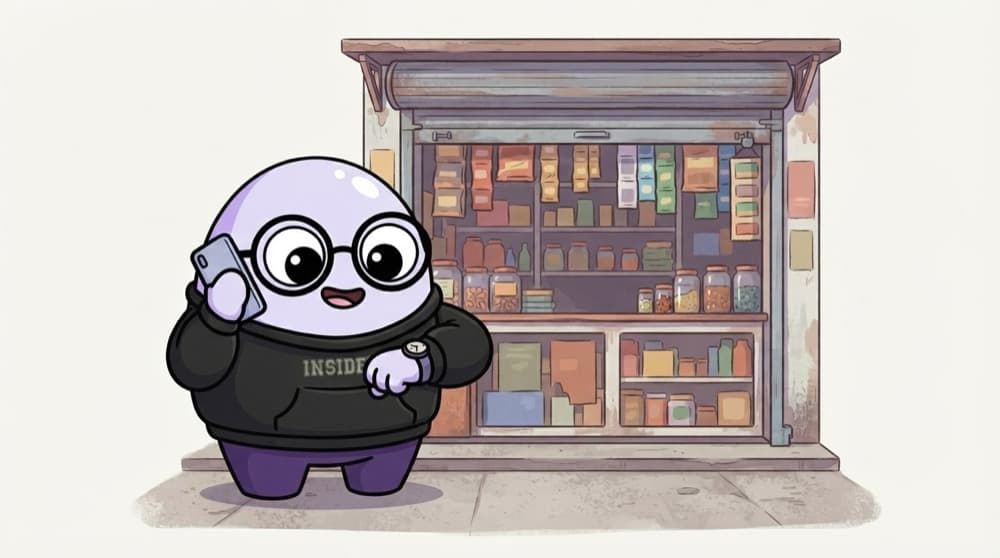
You ask a friend in another city to call your shop every few minutes. If nobody picks up twice in a row, he calls your mobile. He doesn't care why, he just knows customers can't get through. That's uptime monitoring.
Watch it happen
Two regions agree it's down
GET /health/ready
1/5Every minute, a checker in one region requests your health URL and expects 200 within 5 seconds.
The big ideas
What you need to know
Check from outside
Monitors run from other networks and regions, so they see what users see, including DNS and TLS problems.
Confirm before alerting
Require two failed checks or two regions before paging. Fewer false alarms means people keep trusting alerts.
Watch certificates too
Many tools also warn days before your TLS certificate or domain expires.
Uptime adds up
99.9 percent uptime still allows about 43 minutes of downtime in a 30-day month.
See it in code
Walk through the code
1// check.ts: run every minute from another machine2const URL = "https://api.shop.in/health/ready";3 4async function check() {5 try {6 const res = await fetch(URL, { signal: AbortSignal.timeout(5000) });7 if (!res.ok) throw new Error(`status ${res.status}`);8 } catch (err) {9 await fetch(process.env.ALERT_WEBHOOK!, {10 method: "POST",11 headers: { "Content-Type": "application/json" },12 body: JSON.stringify({ text: `API DOWN: ${(err as Error).message}` }),13 });14 }15}16check();1/3Call the health URL and give up after 5 seconds.
In real life use a hosted monitor or self-host Uptime Kuma. This shows what they do under the hood.
Save yourself the pain
Common mistakes
Oops
Running the uptime monitor on the same server as the app.
Do this instead
When that server dies, both go silent together. Monitor from a different provider or region.
Oops
Only checking that the homepage returns 200.
Do this instead
A cached homepage can load while the API and database are down. Check a readiness endpoint that touches real dependencies.
Your mission
Get paged by your own bot
Quick check
Why require failures from two regions before sending an alert?
Go deeper
- 1Set up a free uptime monitor, e.g. UptimeRobot, pinging your deployed API.
- 2Configure alerts via email or Slack when a check fails.
- 3Understand why this must run from outside your own infrastructure to be meaningful.
More topics at this stop
 Logging Best Practices
 Winston
 Pino
 Centralized Logging
 Health Check Endpoints
 Application Performance Monitoring
 Sentry for Error Tracking
 Prometheus & Grafana (Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
