Migration Risk Management
Part of the Cloud Computing Roadmap
In short
A migration that goes wrong at 2 a.m. with no rollback plan is how careers get interesting. Risk management is just deciding, calmly and in advance, what you'll do when things break.
Identifying what could go wrong during a migration (data loss, extended downtime, cost overruns) and having mitigation plans — a rollback plan and a staged, incremental approach reduce the blast radius of problems.
Think of it like this
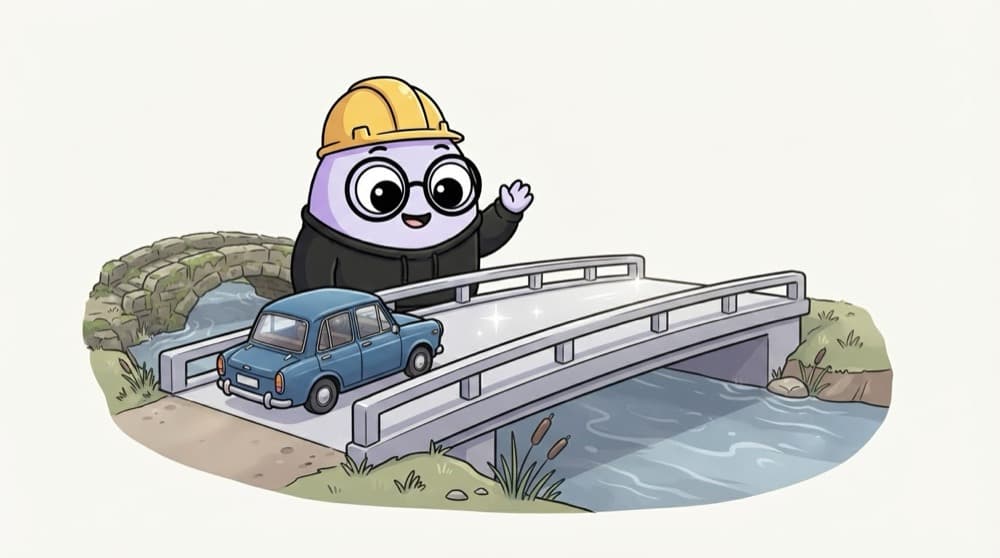
Keep the old bridge standing
When a town replaces an old bridge, engineers build the new one alongside. Traffic shifts a few cars at a time. The old bridge stays open until the new one has carried trucks for weeks. Nobody blows up the old bridge on opening day.
Watch it happen
Managing risk wave by wave
1/6Write down what could go wrong: data loss, long downtime, slow performance, a cost spike, a missing dependency.
The big ideas
What you need to know
Small waves
Moving a few apps at a time limits the damage. One failed wave is a bad night, not a bad year.
Rollback is a plan, not a hope
Decide in advance what triggers rollback, who decides, and test the rollback itself before the real night.
Lower DNS TTL early
Drop DNS TTL to a minute or two a few days before cutover, so switching back and forth is quick.
Don't delete too soon
Keep the old servers and a final backup for a few weeks after cutover, until the new setup is proven.
How it works
A cutover night with go/no-go checks
- 1
Freeze
Announce the window and stop new deployments. Take a final backup of the old database.
- 2
Sync
Let replication catch up until the lag is near zero, then pause writes briefly.
- 3
Switch
Point DNS or the load balancer at the new environment.
- 4
Check
Run smoke tests: login, a test order, a report. Watch error rates for 30 minutes.
- 5
Decide
All green? Go. Any red check you can't fix quickly? Roll back to the old system.
Save yourself the pain
Common mistakes
Oops
Planning a big-bang weekend where every app moves at once.
Do this instead
Move in waves. If something breaks, only a few apps are affected and the team isn't exhausted.
Oops
Writing a rollback plan but never testing it.
Do this instead
Rehearse rollback in a staging run. An untested rollback often fails exactly when you need it.
Your mission
Build a small risk register
Quick check
Why lower the DNS TTL a few days before cutover?
Go deeper
- 1List the top 3 risks for a hypothetical migration project and a mitigation for each.
- 2Learn why migrating in stages (not a single 'big bang' cutover) reduces overall risk.
- 3Draft a rollback plan for a hypothetical migration in case something goes wrong post-cutover.
More topics at this stop
 Cloud Migration Strategies (The 6 Rs)
 Migration Assessment & Planning
 Lift-and-Shift vs Re-Architecting
 Data Migration Techniques
 Hybrid Cloud Connectivity
 Multi-Cloud Strategy & Trade-offs
 Vendor Lock-In Considerations

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
