Database Questions
Part of the Cloud Computing Roadmap
In short
"RDS or DynamoDB for this?" is really asking "do you choose databases by habit or by access pattern?" Start from how the data is read and written, and the answer usually picks itself.
'How would you choose between RDS and DynamoDB for this use case?' — testing Phase 6's database selection judgment against a specific scenario.
Think of it like this
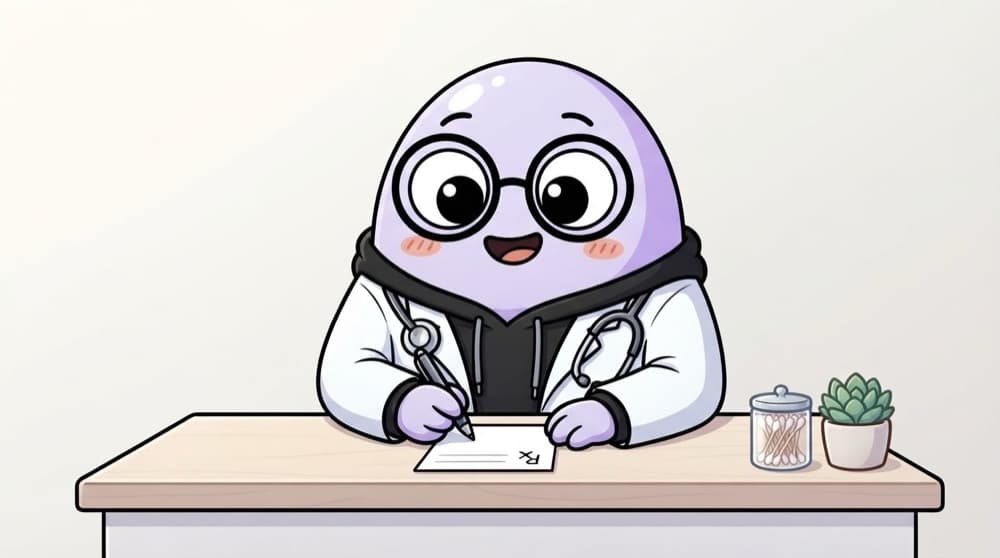
The doctor asks symptoms first
A good doctor doesn't prescribe his favourite medicine to every patient. He asks where it hurts, since when, any allergies. Only then does he write the prescription. Choosing a database works the same way: symptoms, meaning access patterns, before medicine.
Watch it happen
Picking a database from the access pattern
1/5Start with questions: what are the main queries, how much data, how many requests, how strict is consistency?
The big ideas
What you need to know
List the queries first
Write the top five queries the app runs. Relational fits flexible queries; DynamoDB needs them known upfront.
Replicas vs Multi-AZ
Read replicas spread read load. Multi-AZ standby is for failover. Mixing these up is a common slip.
Scaling paths differ
Relational usually scales up and adds replicas. DynamoDB scales out through partitions, if keys are spread well.
Many apps use several
Postgres for orders, Redis for sessions, a warehouse for reports. Saying "it depends, and here's on what" is right.
How it works
Answering "RDS or DynamoDB?"
- 1
Access patterns
Ask which queries matter most and whether they're by key or need joins and filters.
- 2
Scale and traffic
Ask about requests per second and data size. Spiky, huge key-value traffic favours DynamoDB.
- 3
Consistency
Money and inventory often need transactions across rows, which is natural in SQL.
- 4
Choose and caveat
"RDS Postgres, because reporting needs joins. If carts get huge traffic, I'd move them to DynamoDB."
Save yourself the pain
Common mistakes
Oops
Picking DynamoDB because it "scales infinitely" without knowing the queries.
Do this instead
DynamoDB shines when access patterns are known. Ad-hoc queries on it get slow and costly.
Oops
Saying read replicas give high availability.
Do this instead
Replicas mainly help reads. For automatic failover, mention Multi-AZ standby.
Your mission
Three apps, three choices
Quick check
A game stores each player's score and reads it by player id millions of times a minute. No joins. Best fit?
Go deeper
- 1Review Phase 6 and practice justifying a database choice for 2-3 different hypothetical workloads.
- 2Prepare to discuss read replicas and Multi-AZ trade-offs concretely.
- 3Practice explaining caching's role in reducing database load.
More services & technical at this stop
 Compute & Storage Questions
 Networking & Security Questions

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
