Troubleshooting Scenarios
Part of the Cloud Computing Roadmap
In short
'The website is down. Walk me through what you'd do.' There's no single answer they're waiting for. They want a calm, step-by-step process that narrows the problem down fast.
'The application is returning 500 errors, walk me through what you'd do' — testing a calm, systematic diagnostic process rather than a specific memorized answer.
Think of it like this
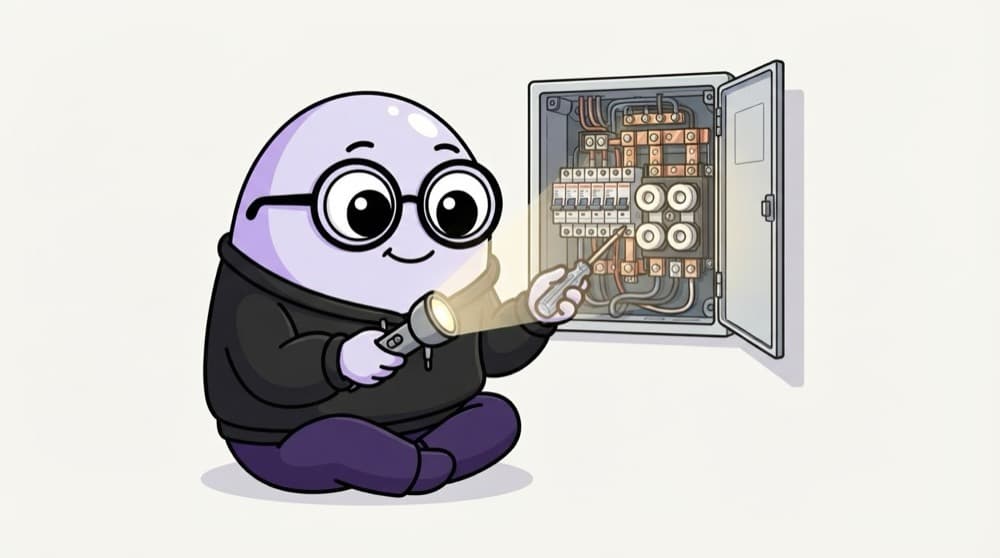
The electrician and the fuse box
When the lights go off, a good electrician doesn't start ripping out wires. First: is the whole street dark, or just this house? Then the main switch, then each circuit breaker, then the one room. Each check cuts the possibilities in half. Troubleshooting is the same.
Watch it happen
Narrowing down 'the site is down'
1/4Scope first. All users or one region? All pages or one? A status page or a single complaint?
The big ideas
What you need to know
Scope before depth
Knowing who is affected and since when rules out half the possibilities before you touch a server.
What changed?
Deploys, config changes, certificate expiry, traffic spikes. Most incidents follow a change.
Mitigate first
If a rollback or failover will bring users back, do it, then investigate. Users care about the fix, not the theory.
Narrate your steps
Say each hypothesis and how you'd test it. A clear process beats guessing the right answer.
See it in code
Walk through the code
1# Outside in, one layer at a time2dig +short shop.example.com # DNS answer?3curl -sS -o /dev/null -w "%{http_code} %{time_total}s\n" https://shop.example.com4openssl s_client -connect shop.example.com:443 </dev/null 2>/dev/null \5 | openssl x509 -noout -enddate # certificate expired?6 7# On an app server8systemctl status myapp # running?9journalctl -u myapp --since "15 min ago" # recent errors10df -h && free -h # disk full? memory?1/3Does the name resolve, and what status code and time does the site return from outside?
These work on most Linux servers. In Kubernetes the app-side checks become kubectl get pods, describe and logs.
Save yourself the pain
Common mistakes
Oops
Diving into application code in the first minute.
Do this instead
Confirm scope and the outer layers first. The bug might be DNS or an expired certificate, not your code.
Oops
Saying 'I'd check the logs' with nothing more specific.
Do this instead
Name which logs, what you'd search for, and what each result would tell you.
Your mission
Practise with a friend
Quick check
Users report the site is down. A deploy went out 10 minutes ago. What's a sensible first action?
Go deeper
- 1Practice a repeatable structure: check monitoring, check recent changes, check logs, isolate the layer.
- 2Prepare a real troubleshooting story from your own practice work, even a small one.
- 3Practice narrating your reasoning out loud — the process is what's being evaluated.
More automation & operations at this stop
 Infrastructure as Code Questions
 Migration Scenario Questions

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
