
Key Tools Overview (Python, SQL, ML, Stats)
Part of the Data Science Roadmap
In short
The data science toolbox looks huge, but four things carry most of the weight: SQL, Python, statistics and machine learning. Here's what each one actually does for you.
A preview of the toolkit this roadmap builds — Python for analysis and modeling, SQL for pulling data at the source, statistics for rigor, and ML frameworks for building predictive systems.
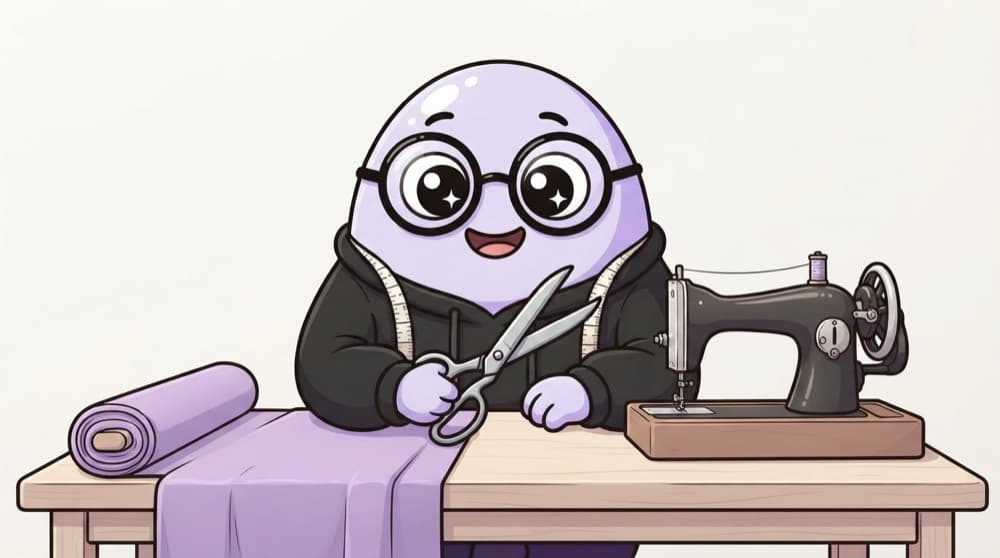
Think of it like this
A tailor's kit
Scissors cut out just the cloth you need, like SQL pulling the rows you want. The sewing machine does the heavy work, like Python. The measuring tape checks sizes, like statistics. The pattern lets you make the next shirt quickly, like an ML model.
Watch it happen
Where each tool fits
1/5SQL pulls just the rows and columns you need from the company database.
The big ideas
What you need to know
SQL is daily bread
Almost every company keeps data in SQL databases or warehouses. You'll write queries nearly every day.
Python is the glue
pandas, NumPy, Matplotlib and scikit-learn cover cleaning, maths, charts and models in one language.
Stats keeps you honest
Averages, spread, sampling and tests stop you from trusting a lucky pattern.
Supporting tools
Jupyter for exploring, Git for saving versions, and a spreadsheet for quick checks.
See it in code
Walk through the code
1import sqlite32import pandas as pd3from sklearn.linear_model import LinearRegression4 5conn = sqlite3.connect("shop.db")6df = pd.read_sql("SELECT ad_spend, sales FROM monthly", conn)7 8print(df.describe()) # stats: mean, spread9print(df.corr()) # do they move together?10 11model = LinearRegression()12model.fit(df[["ad_spend"]], df["sales"])13print(model.predict(pd.DataFrame({"ad_spend": [50000]})))1/3SQL pulls two columns from a local database into a pandas table.
All four tools in one tiny script: SQL to fetch, pandas to hold the table, stats to check, and a model to predict.
Save yourself the pain
Common mistakes
Oops
Learning ten libraries shallowly before mastering SQL and pandas.
Do this instead
Get comfortable with SQL and pandas first. They're used in nearly every task.
Oops
Skipping statistics because libraries 'do the maths'.
Do this instead
Libraries compute numbers. Stats tells you whether those numbers mean anything.
Your mission
Set up your toolkit
Quick check
You've found that users who get push notifications order more. Which tool tells you if that difference could just be chance?
Go deeper
- 1Skim the table of contents of each remaining phase to see how the tools fit together.
- 2Learn that strong SQL and statistics fundamentals matter as much as flashy ML skills.
- 3Set a rough personal priority order — most beginners should go math and Python first.
More topics at this stop
 What Data Scientists Actually Do
 Data Scientist vs Data Analyst vs ML Engineer
 The Data Science Lifecycle (CRISP-DM)
 Types of Data Science Roles (Research, Applied, Product)
 Data-Driven vs Model-Driven Decisions
 Common Industries for Data Scientists
 A Day in the Life of a Data Scientist
 The Data Science Career Ladder

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
