In short
Brands read thousands of reviews and tweets a day. Build a model that sorts them into happy and unhappy, compare a classic baseline with a transformer, and you have a strong NLP project.
The practice project for this phase — build a text classifier that predicts sentiment (positive/negative/neutral), comparing a classic approach (TF-IDF + logistic regression) against a modern one (pretrained model).
Think of it like this
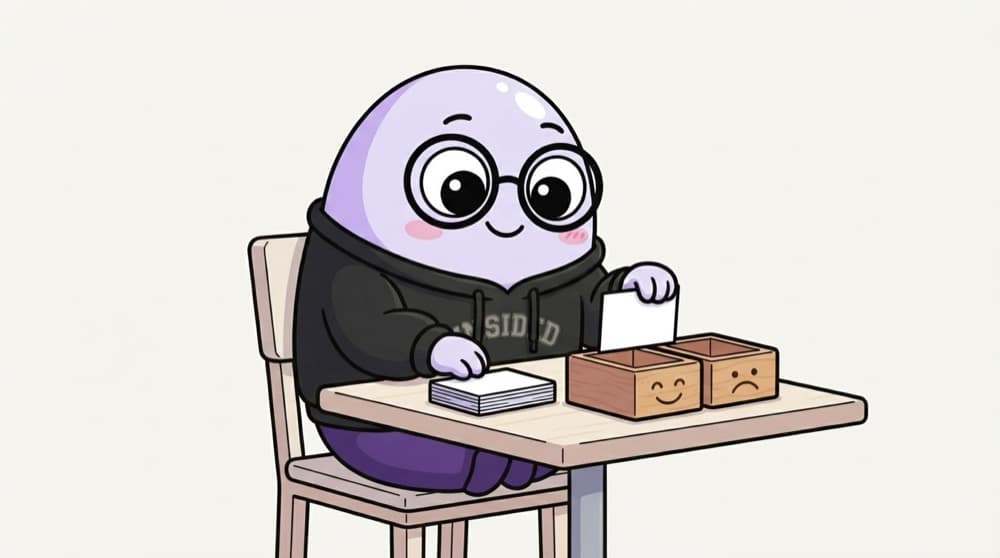
Sorting the feedback cards
A restaurant owner reads every feedback card at closing time and drops it in a happy or unhappy tray. With ten cards that's fine. With ten thousand a day, they need help. Your model is the helper, and you check it on cards it hasn't seen.
Watch it happen
Project build plan
1/5Use a labelled public dataset like IMDB, or app reviews with star ratings turned into labels.
The big ideas
What you need to know
Check balance
If 90% of reviews are positive, accuracy misleads. Report per-class F1.
Baseline vs transformer
Show both. A small gain at ten times the cost is a real trade-off worth discussing.
Sarcasm and mixed reviews
'Great, another late delivery' fools many models. Collect such errors and discuss them.
Hinglish is hard
Mixed Hindi-English text breaks English-only models. Mention it as a limitation or a stretch goal.
See it in code
Walk through the code
1from datasets import load_dataset2from sklearn.feature_extraction.text import TfidfVectorizer3from sklearn.linear_model import LogisticRegression4from sklearn.metrics import classification_report5from sklearn.pipeline import make_pipeline6 7data = load_dataset("imdb")8train, test = data["train"], data["test"]9 10clf = make_pipeline(TfidfVectorizer(ngram_range=(1, 2), min_df=2), LogisticRegression(max_iter=1000))11clf.fit(train["text"], train["label"])12print(classification_report(test["label"], clf.predict(test["text"])))1/3Load the labelled IMDB reviews from Hugging Face Datasets.
The baseline every sentiment project needs. 25,000 training reviews fit in well under a few minutes on a laptop.
Save yourself the pain
Common mistakes
Oops
Reporting only the transformer's score with no baseline.
Do this instead
Always show a simple baseline so readers can judge whether the heavy model was worth it.
Oops
Testing on reviews the model saw while you tuned it.
Do this instead
Keep a test set aside from the start and use it once at the end.
Your mission
First milestone: baseline and error list
Quick check
Why use ngram_range=(1, 2) in the TF-IDF baseline?
Go deeper
- 1Find a public sentiment-labeled dataset (product reviews, tweets, etc).
- 2Build both a classic baseline and a pretrained-model-based approach, and compare accuracy.
- 3Write up which approach you'd recommend for production, and why (accuracy vs simplicity vs cost).

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
