
Ethics & Bias in Machine Learning
Part of the Data Science Roadmap
In short
A model learns from history, and history isn't always fair. If past decisions were biased, your model can copy that bias at scale, quietly, with a confident-looking score.
Models trained on historical data can encode and amplify existing societal biases — recognizing this risk and testing for it is a core professional responsibility, not an optional add-on.
Think of it like this
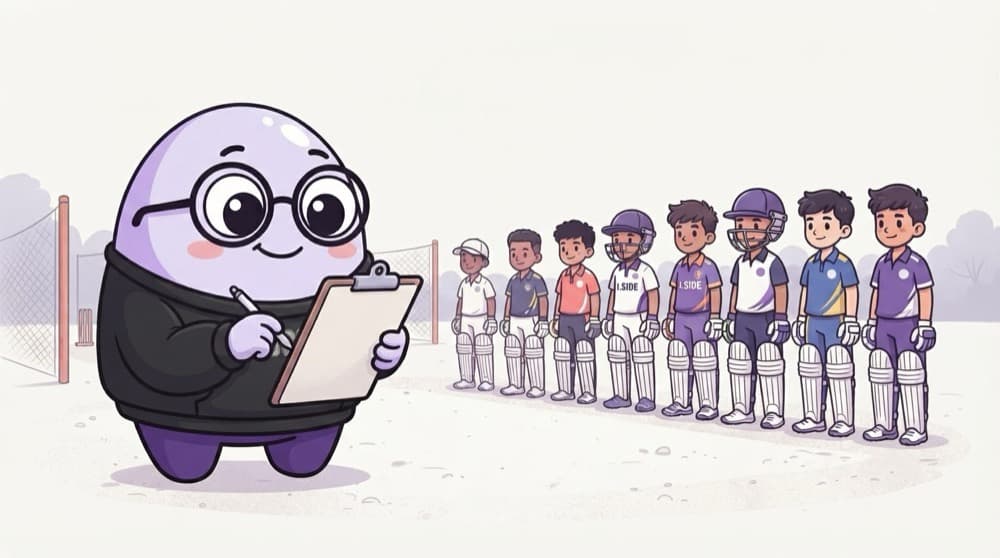
The selector with a blind spot
A selector picks only players from a few big-city academies because past champions came from there. Talented kids from small towns never get a trial, so his 'data' keeps proving him right. Models trained on past hires or loans can fall into exactly this loop.
Watch it happen
Where bias sneaks in
1/6Some groups are missing or rare in the data, so the model sees too few examples of them.
The big ideas
What you need to know
Bias at every stage
Data collection, labelling, features, evaluation and deployment can each add bias. Check all of them.
Dropping a column isn't enough
Removing 'gender' does little if other features act as proxies for it.
Measure per group
Compare approval rate, recall and false positive rate across groups, not just overall accuracy.
Keep humans in the loop
For high-stakes calls like loans, hiring or health, let people review and appeal decisions.
See it in code
Walk through the code
1import pandas as pd2 3df = pd.DataFrame({4 "group": ["A", "A", "A", "A", "B", "B", "B", "B"],5 "actual": [1, 0, 1, 1, 1, 0, 1, 1],6 "pred": [1, 0, 1, 1, 0, 0, 0, 1],7})8 9df["approved"] = df["pred"] == 110pos = df[df["actual"] == 1]11 12print(df.groupby("group")["approved"].mean()) # approval rate per group13print(pos.groupby("group")["pred"].mean()) # recall per group1/3Toy results: each row has a group, the true outcome and the model's prediction.
A tiny fairness check. Group A's approval rate is 0.75 and B's is 0.25; deserving B applicants are missed far more often.
Save yourself the pain
Common mistakes
Oops
Deleting the sensitive column and calling the model fair.
Do this instead
Keep it aside for testing. Measure outcomes per group and look for proxy features.
Oops
Only reporting overall accuracy.
Do this instead
Break metrics down by group. A 90% accurate model can still fail one group badly.
Your mission
Run a group fairness check
Quick check
You removed 'gender' from a hiring model, but it still favours men. What's the most likely reason?
Go deeper
- 1Read a real case study of a biased model that caused a public issue.
- 2Learn to check model performance across different demographic subgroups, not just in aggregate.
- 3Practice identifying a potential bias risk in a hypothetical model idea of your own.
More topics at this stop
 Translating Business Problems Into ML Problems
 Communicating Model Results to Stakeholders
 Data Storytelling With Visualizations
 Explainable AI (SHAP, LIME Overview)
 Writing a Technical Report
 Presenting to Non-Technical Audiences

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
