Simple Web Scraper
Part of the AI Engineer Roadmap
In short
Sometimes the data you need is sitting on a web page with no download button. A scraper fetches the page and pulls out just the parts you want, turning a website into a dataset.
A script that pulls structured data from a public webpage — your first real data-collection project, using `requests` and an HTML parser.
Think of it like this
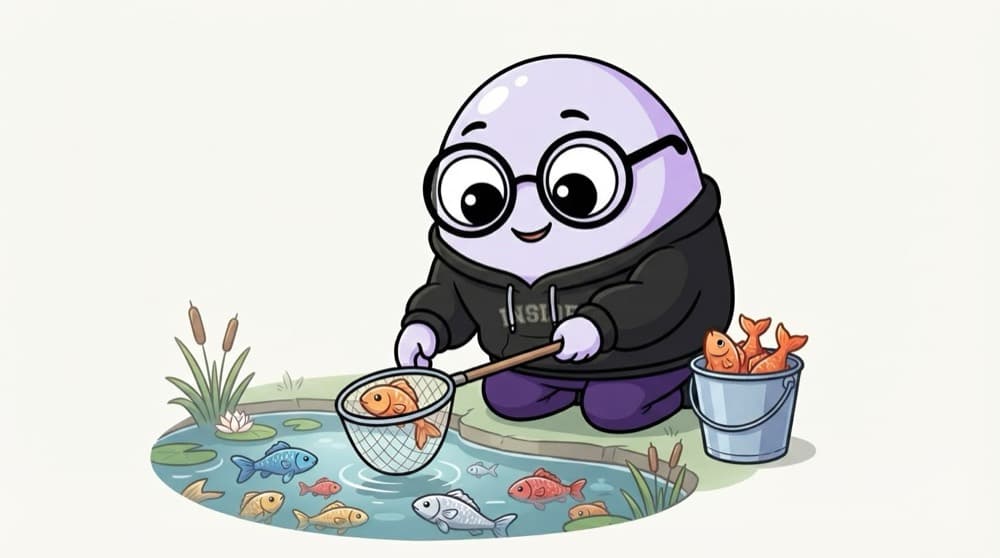
Netting only the orange fish
The pond has fish of every colour. You know you only want the orange ones, so you use a small net and scoop just those into your bucket. The web page is the pond, a CSS selector is the shape of your net, and the CSV is your bucket.
Watch it happen
Scraping book prices
GET /catalogue/page-1
1/5The script asks for the page like a browser would, with a polite User-Agent header.
The big ideas
What you need to know
Inspect before you code
Right-click an item, choose Inspect, and find a class or tag that wraps each item. That becomes your selector.
Be polite
Add a delay between pages and a User-Agent. Hammering a site can get your IP blocked.
Check the rules
Read the site's robots.txt and terms. Scrape only public pages, and prefer an official API if one exists.
Expect pages to change
When a site redesigns, selectors break. Check for missing elements so your script fails clearly.
See it in code
Walk through the code
1import csv, time2import requests3from bs4 import BeautifulSoup4BASE = "https://books.toscrape.com/catalogue/page-{}.html"5rows = []6for page in range(1, 4):7 html = requests.get(BASE.format(page), timeout=10).text8 soup = BeautifulSoup(html, "html.parser")9 for card in soup.select("article.product_pod"):10 title = card.h3.a["title"]11 price = card.select_one(".price_color").get_text(strip=True)12 rows.append({"title": title, "price": price})13 time.sleep(1)14 15with open("books.csv", "w", newline="", encoding="utf-8") as f:16 w = csv.DictWriter(f, fieldnames=["title", "price"]); w.writeheader(); w.writerows(rows)1/4Build each page URL and fetch it with a timeout.
books.toscrape.com is a sandbox site built for scraping practice, so it's safe to experiment on. Install with pip install requests beautifulsoup4.
Save yourself the pain
Common mistakes
Oops
Scraping a site that needs a login, or ignoring its terms of service.
Do this instead
Stick to public pages that allow it. Use the official API when the site offers one.
Oops
Assuming every card has a price and crashing on the one that doesn't.
Do this instead
Check select_one's result for None before calling get_text on it.
Your mission
Scrape quotes into a CSV
Quick check
Your scraper worked yesterday but today returns an empty list. What's the most likely cause?
Go deeper
- 1Scrape a simple static page with BeautifulSoup and save the results to CSV.
- 2Respect `robots.txt` and add delays between requests.
- 3Handle missing elements and page-structure changes without crashing.
More projects at this stop
 Command-Line Data Cleaner

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
