Workflow Orchestration
Part of the AI Engineer Roadmap
In short
Most useful AI features aren't free-roaming agents. They're fixed workflows: classify, then route, then call two models in parallel, then merge. Orchestration is running those steps reliably.
Coordinating multi-step agent or pipeline workflows reliably — including retries, branching logic and state management — as agent systems grow beyond a single call.
Think of it like this
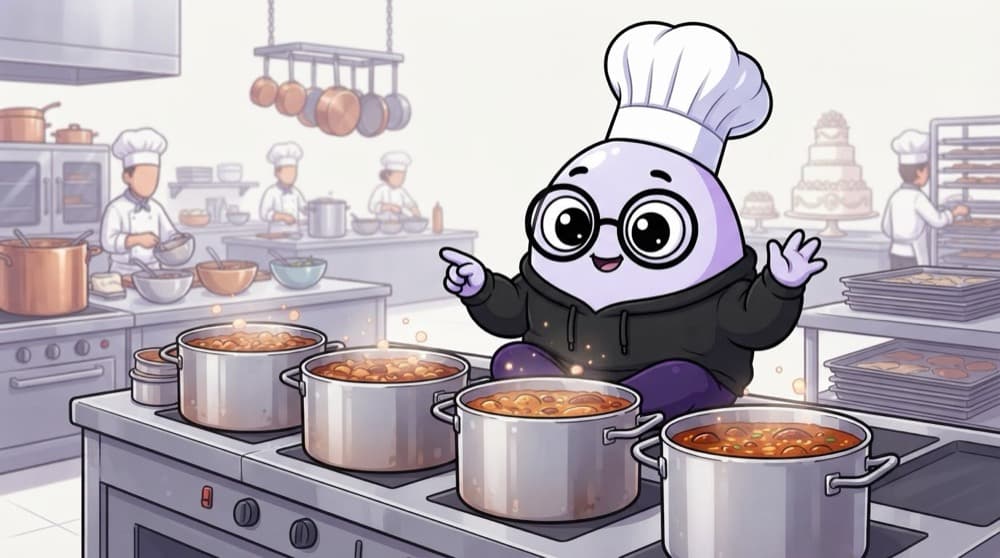
The wedding caterer's kitchen
A wedding caterer doesn't improvise. Rice and dal cook in parallel, the halwa waits for milk, and nothing leaves until the head cook tastes it. If the tandoor fails, they have a backup. AI workflows need that same fixed plan, parallel steps and retries.
Watch it happen
An AI code review workflow
1/5A pull request arrives. The workflow starts with a run id so every step can be traced later.
The big ideas
What you need to know
Workflow vs agent
In a workflow, your code decides the steps. In an agent, the model decides. Prefer workflows when you can.
Chain, route, parallelise
Most workflows mix three moves: steps in a chain, a router that picks a branch, and parallel calls that get merged.
Retries and timeouts
LLM APIs fail and time out. Every step needs a timeout, a retry with backoff and a fallback.
Tools for the job
LangGraph, Temporal and Prefect add state, retries and replays. For small jobs, plain async code is fine.
See it in code
Walk through the code
1import asyncio2 3async def call_llm(prompt): # stand-in for a real API call4 await asyncio.sleep(0.1)5 return f"answer to: {prompt[:30]}"6 7async def review(code):8 bugs, style, tests = await asyncio.gather(9 call_llm(f"Find bugs:\n{code}"),10 call_llm(f"Check style:\n{code}"),11 call_llm(f"Suggest tests:\n{code}"),12 )13 return await call_llm(f"Merge into one review:\n{bugs}\n{style}\n{tests}")14 15print(asyncio.run(review("def add(a, b): return a - b")))1/3A fake LLM call so you can run this without an API key.
Fan out three calls in parallel, then merge. Swap call_llm for a real SDK call and the shape stays the same.
Save yourself the pain
Common mistakes
Oops
Running independent LLM calls one after another.
Do this instead
If calls don't depend on each other, run them in parallel. Three 4-second calls then take about 4 seconds, not 12.
Oops
No record of which step failed in a 6-step run.
Do this instead
Log each step's input, output, time and errors under one run id, so you can replay the failure.
Your mission
Time a parallel workflow
Quick check
When should you choose a fixed workflow over an agent?
Go deeper
- 1Design a multi-step workflow with explicit state transitions for an agent task.
- 2Add retry and fallback logic for steps that can fail (API errors, tool timeouts).
- 3Learn how graph-based orchestration frameworks (e.g. LangGraph) model this differently from linear chains.
More topics at this stop
 Agent Architectures (ReAct, Plan-and-Execute)
 LangChain
 LlamaIndex
 Function/Tool Calling for Agents
 Multi-Agent Systems (AutoGen, CrewAI)
 Memory in Agents
 Agent Guardrails
 Model Context Protocol (MCP, Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
