Caching LLM Responses
Part of the AI Engineer Roadmap
In short
During placement season, 500 students ask your bot 'What's the dress code?' Calling the model 500 times for the same answer is slow and wasteful. Cache it once, serve it 499 times.
Storing and reusing responses for repeated or similar queries to cut both latency and API cost — a high-leverage optimization for any AI product with predictable query patterns.
Think of it like this
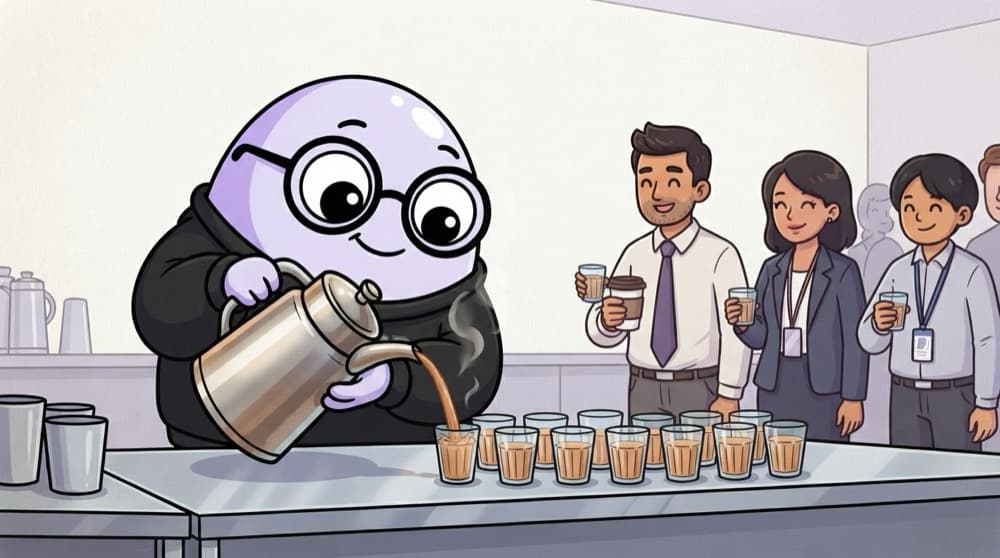
The chaiwala's ready flask
At the 8 am office rush, the chaiwala doesn't brew each cup from scratch. He keeps a big flask of ready cutting chai, because everyone orders the same thing. A fresh batch only when the flask runs out or goes cold. That flask is your cache.
Watch it happen
A cache miss, then a hit
GET key sha256(...)
1/6The app hashes the model name and messages into a key and checks the cache first.
The big ideas
What you need to know
Exact-match cache
Hash model, prompt and settings into a key. Identical requests get the stored answer.
Semantic cache
Embed the question and reuse answers to very similar questions. Faster hits, but risk of wrong matches.
Provider prompt caching
Different idea: the provider caches a long fixed prompt prefix, so you pay less to resend it.
Expire and scope
Set a TTL, and never share cached answers that contain one user's personal data with another user.
See it in code
Walk through the code
1import hashlib, json, time2 3CACHE, TTL = {}, 36004 5def cache_key(model, messages):6 raw = json.dumps({"m": model, "msgs": messages}, sort_keys=True)7 return hashlib.sha256(raw.encode()).hexdigest()8 9def cached_call(model, messages, call):10 key = cache_key(model, messages)11 hit = CACHE.get(key)12 if hit and time.time() - hit[1] < TTL:13 return hit[0]14 answer = call(model, messages)15 CACHE[key] = (answer, time.time())16 return answer1/3sort_keys keeps the JSON identical for identical requests, so the hash matches.
An exact-match cache with expiry. In production, swap the dictionary for Redis so all servers share it.
Save yourself the pain
Common mistakes
Oops
Caching answers to 'What's my exam seat number?' across all users.
Do this instead
Include the user id in the key for personal questions, or don't cache them at all.
Oops
Using a semantic cache with a very loose similarity threshold.
Do this instead
'Refund policy for flights' and 'refund policy for hotels' are close but different. Test thresholds on real questions.
Your mission
Measure your hit rate
Quick check
Why include the model name and settings in the cache key?
Go deeper
- 1Implement exact-match response caching for a repeated query pattern.
- 2Learn semantic caching (matching similar, not identical, queries) at a conceptual level.
- 3Identify cache-invalidation risks specific to AI responses (stale facts, outdated context).
More topics at this stop
 Designing Scalable AI Systems
 Latency & Cost Optimization
 Load Balancing AI Workloads
 Designing a RAG System at Scale
 Designing a Recommendation System
 Designing a Content Moderation System
 Handling High-Throughput Inference
 Choosing Between Fine-Tuning and RAG

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
