Load Balancing AI Workloads
Part of the AI Engineer Roadmap
In short
Some prompts finish in 1 second, others in 30. Taking turns can still pile work onto one busy GPU, so AI load balancing has to look at actual load.
Distributing inference requests across multiple model instances or providers to avoid bottlenecks and single points of failure in an AI service.
Think of it like this
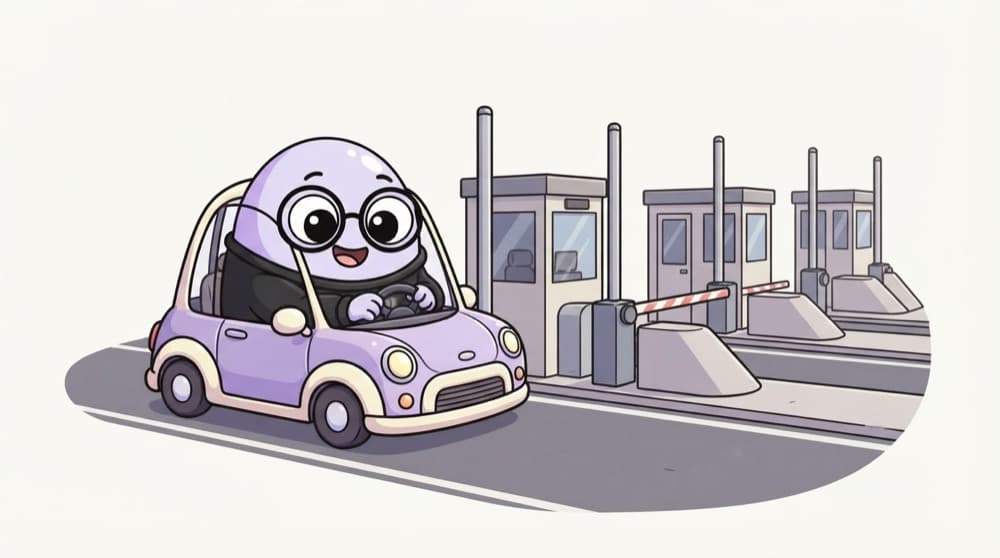
Picking the shortest toll lane
At a toll plaza, smart drivers don't pick lanes in turn. They look for the shortest queue and avoid the booth that's closed. If one lane has a truck with a problem, they switch. Good AI load balancers do the same with model servers.
Watch it happen
Requests in flight per GPU replica
1/5Four model replicas. Each number is how many requests that replica is working on right now.
The big ideas
What you need to know
Least-loaded beats round-robin
Request times vary a lot for LLMs. Route by requests in flight or queue length, not by turn.
Health checks
Remove replicas that fail checks or time out, and add them back when they recover.
Fallback providers
If one model provider is down or rate limiting you, route to a backup model or region.
Scale on queue depth
Autoscale GPU replicas on waiting requests, not just CPU, since GPU work hides from CPU metrics.
See it in code
Walk through the code
1in_flight = {"gpu-a": 0, "gpu-b": 0, "gpu-c": 0}2healthy = {"gpu-a": True, "gpu-b": True, "gpu-c": False}3 4def pick():5 live = [r for r in in_flight if healthy[r]]6 if not live:7 raise RuntimeError("No healthy replicas, use a fallback")8 return min(live, key=lambda r: in_flight[r])9 10def send(request, run):11 replica = pick()12 in_flight[replica] += 113 try:14 return run(replica, request)15 finally:16 in_flight[replica] -= 11/3Only healthy replicas are considered. With none left, fail over elsewhere.
Least-outstanding-requests routing with health checks, in plain Python. Real load balancers and gateways do this for you.
Save yourself the pain
Common mistakes
Oops
Round-robin across GPUs when some prompts take 30 times longer than others.
Do this instead
Use least-connections or queue-aware routing so slow requests don't pile up on one replica.
Oops
Relying on a single model provider with no backup.
Do this instead
Keep a fallback model or provider ready, and test the switch before an outage forces it.
Your mission
Simulate two strategies
Quick check
Why is plain round-robin a weak choice for LLM servers?
Go deeper
- 1Design a load-balancing strategy across multiple model instances or API keys.
- 2Learn how to handle provider-level rate limits with multi-provider fallback.
- 3Understand health checks and graceful degradation when a model endpoint is down.
More topics at this stop
 Designing Scalable AI Systems
 Latency & Cost Optimization
 Caching LLM Responses
 Designing a RAG System at Scale
 Designing a Recommendation System
 Designing a Content Moderation System
 Handling High-Throughput Inference
 Choosing Between Fine-Tuning and RAG

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
