scikit-learn Basics
Part of the AI Engineer Roadmap
In short
scikit-learn has dozens of models, but you only need to learn one pattern: fit, then predict. Learn it once and every model in the library feels familiar.
Python's standard ML library — a consistent `fit`/`predict`/`transform` API across dozens of algorithms, and the tool you'll use for most classical ML work.
Think of it like this
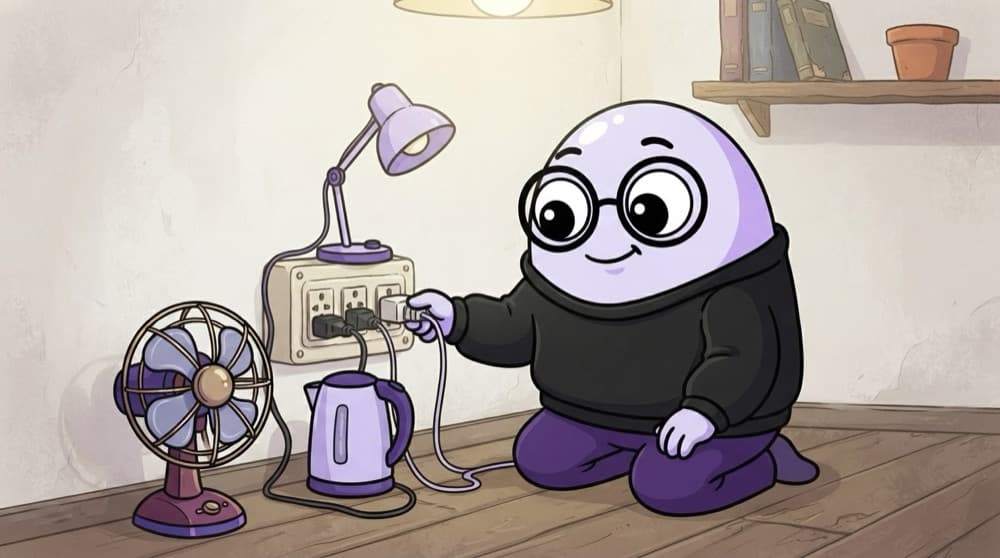
Same switchboard, different appliances
In a hostel room, the fan, the kettle and the lamp all plug into the same switchboard. Different machines, same plug. scikit-learn works the same way: every model plugs into fit() and predict(), so swapping one for another is a one-line change.
Watch it happen
The scikit-learn routine
1/6X is a table of features, one row per example. y is the column of answers.
The big ideas
What you need to know
Estimators learn with fit()
Every model is an estimator. Call fit(X, y) and it stores what it learnt in attributes ending with an underscore, like coef_.
Transformers change data
Scalers and encoders use fit() to learn settings and transform() to apply them. fit_transform() does both in one go.
Pipelines glue steps together
make_pipeline chains transformers and a model, so the same steps run the same way during training and prediction.
Built-in practice data
sklearn.datasets ships small datasets like iris and breast_cancer, so you can practise without hunting for CSV files.
See it in code
Walk through the code
1from sklearn.datasets import load_breast_cancer2from sklearn.model_selection import train_test_split3from sklearn.pipeline import make_pipeline4from sklearn.preprocessing import StandardScaler5from sklearn.linear_model import LogisticRegression6 7X, y = load_breast_cancer(return_X_y=True)8X_train, X_test, y_train, y_test = train_test_split(X, y, random_state=42)9 10model = make_pipeline(StandardScaler(), LogisticRegression())11model.fit(X_train, y_train)12print(model.predict(X_test[:5]))13print("accuracy:", model.score(X_test, y_test))1/3Load the data and keep a test set aside. random_state makes the split the same every run.
A complete model in about ten lines. Swap LogisticRegression for RandomForestClassifier and nothing else needs to change.
Save yourself the pain
Common mistakes
Oops
Calling scaler.fit_transform() on the whole dataset before splitting.
Do this instead
Split first, then fit the scaler on training data only. A pipeline does this for you automatically.
Oops
Passing a 1D list as X, like X = [1, 2, 3].
Do this instead
X must be 2D: rows and columns. Use X.reshape(-1, 1) for a single feature.
Your mission
Swap three models
Quick check
You built make_pipeline(StandardScaler(), LogisticRegression()). What happens when you call model.predict(X_new)?
Go deeper
- 1Practice the fit/predict/transform pattern across multiple different estimators.
- 2Learn to build a `Pipeline` that chains preprocessing and modeling steps.
- 3Read scikit-learn's algorithm cheat sheet to know what to reach for when.
More topics at this stop
 Supervised vs Unsupervised Learning
 Linear Regression
 Logistic Regression
 Decision Trees
 Random Forests
 K-Nearest Neighbors
 K-Means Clustering
 Support Vector Machines
 Naive Bayes
 Train/Test Split
 Cross-Validation

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
