
Supervised vs Unsupervised Learning
Part of the AI Engineer Roadmap
In short
Before you pick any algorithm, ask one question: do I have the answers for my training data? That single question splits most of machine learning into two camps.
Supervised learning trains on labeled data to predict outcomes; unsupervised learning finds structure in unlabeled data — the first fork in the road for choosing an ML approach.
Think of it like this
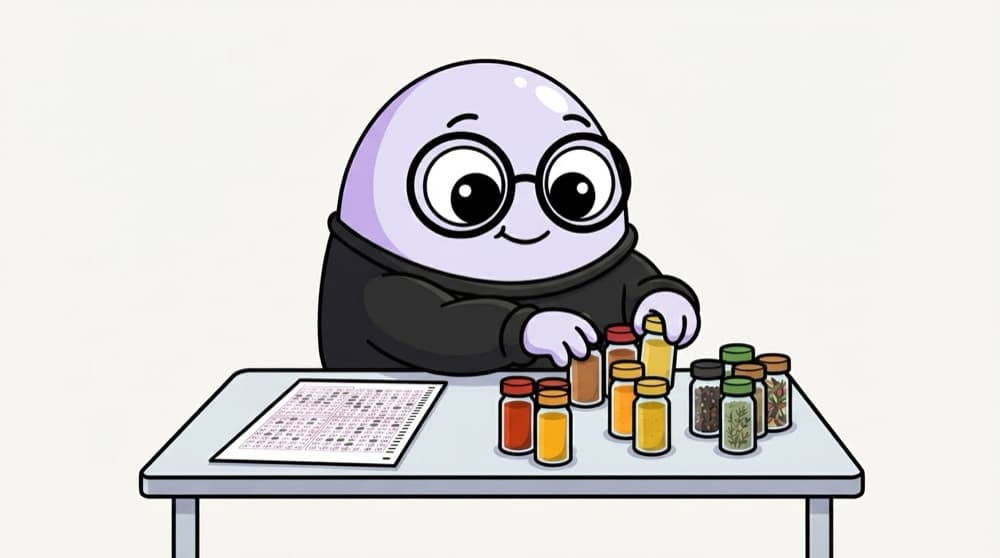
Solved papers vs a mixed-up spice box
Supervised learning is practising with last year's solved papers: every question comes with the right answer. Unsupervised learning is your mom's unlabelled spice box. Nobody tells you the names, but you can still group them by colour and smell.
Watch it happen
Do you have labels?
Supervised
- Each row has an answer (label)
- Predicts price, spam, churn
- Scored against true answers
Unsupervised
- Only features, no answers
- Finds groups and patterns
- Judged by how useful groups are
Have labels and a clear target? Go supervised. Only raw data and a question like 'what kinds of customers do we have?' Go unsupervised.
The big ideas
What you need to know
Labels are the answers
A label is the value you want to predict, like 'spam' or a house price. Supervised models learn the link from features to labels.
Two supervised flavours
Regression predicts a number (rent, temperature). Classification predicts a category (pass or fail, fraud or genuine).
Unsupervised finds structure
Clustering groups similar rows. Dimensionality reduction squeezes many columns into a few that keep most of the information.
Labels cost money
Someone has to tag every example by hand. That's why teams often cluster first, then label a smaller, smarter sample.
See it in code
Walk through the code
1from sklearn.datasets import load_iris2from sklearn.linear_model import LogisticRegression3from sklearn.cluster import KMeans4 5X, y = load_iris(return_X_y=True)6 7# Supervised: learn from features AND labels8clf = LogisticRegression(max_iter=200).fit(X, y)9print(clf.predict(X[:3])) # [0 0 0]10 11# Unsupervised: only features, find groups12km = KMeans(n_clusters=3, n_init=10, random_state=0).fit(X)13print(km.labels_[:3]) # cluster ids, numbering is arbitrary1/3X holds the measurements of each flower. y holds the species, which is the label.
Same flower data, two jobs. The classifier sees y and predicts species. KMeans never sees y and invents its own group numbers.
Save yourself the pain
Common mistakes
Oops
Thinking clustering will 'predict' the right category names for you.
Do this instead
Clusters are just groups with numbers. You still have to look inside each one and decide what it means.
Oops
Using a supervised model when you have only a handful of labelled rows.
Do this instead
Get more labels first, or start with clustering and labelling a small sample from each cluster.
Your mission
One dataset, two questions
Quick check
A shop has a year of customer purchase data but no tags on the customers. They want to find shopper types. What fits best?
Go deeper
- 1List five real-world problems and classify each as supervised, unsupervised, or unclear.
- 2Learn the sub-categories: classification/regression under supervised, clustering/dimensionality reduction under unsupervised.
- 3Understand semi-supervised and self-supervised learning as the bridge to modern deep learning.
More topics at this stop
 Linear Regression
 Logistic Regression
 Decision Trees
 Random Forests
 K-Nearest Neighbors
 K-Means Clustering
 Support Vector Machines
 Naive Bayes
 scikit-learn Basics
 Train/Test Split
 Cross-Validation

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
