Feature Selection
Part of the AI Engineer Roadmap
In short
More columns don't always mean a better model. Useless or duplicate features add noise, slow training and make the model harder to explain. Picking the right few is a skill.
Choosing the subset of features that actually improve model performance — reduces overfitting, training time, and improves interpretability.
Think of it like this
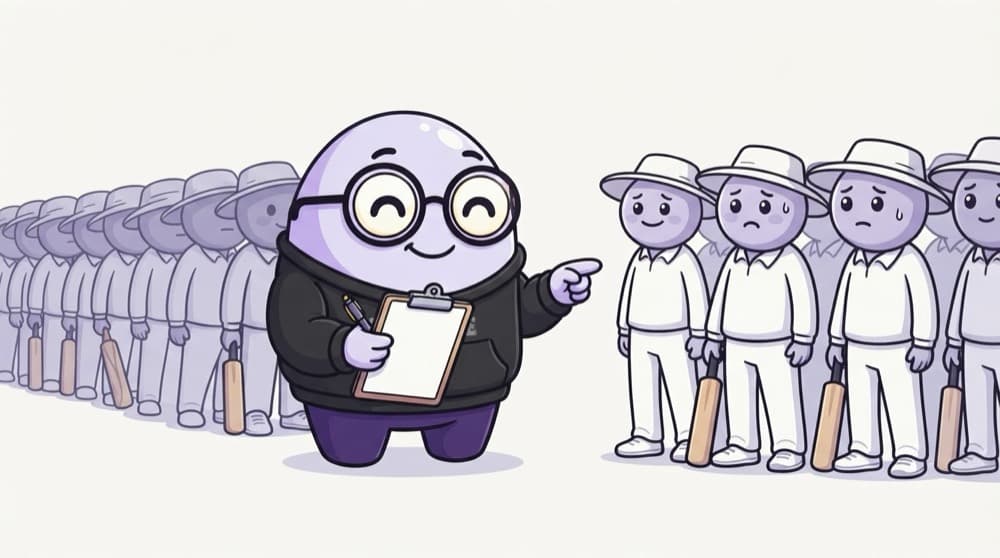
Picking the playing XI
A cricket squad has 20 players, but only 11 take the field. Selectors drop the out-of-form ones and avoid picking two players who do the exact same job. Feature selection picks your playing XI from all the columns you have.
Watch it happen
Trimming a churn dataset
1/4Eight candidate columns for predicting churn. Not all of them will help.
The big ideas
What you need to know
Filter methods
Score each feature against the target with a quick statistic, like correlation or an F-test, and keep the top ones.
Wrapper methods
Recursive feature elimination trains a model, drops the weakest feature, and repeats. Slower, but it sees features working together.
Embedded methods
Some models select while they train. L1 regularisation pushes useless weights to zero, and trees report feature importances.
Select inside the CV loop
If you choose features using all the data, then cross-validate, the score is inflated. Put selection inside a Pipeline.
See it in code
Walk through the code
1from sklearn.datasets import load_breast_cancer2from sklearn.feature_selection import SelectKBest, f_classif3 4data = load_breast_cancer(as_frame=True)5X, y = data.data, data.target # 30 features6 7selector = SelectKBest(score_func=f_classif, k=5)8X_small = selector.fit_transform(X, y)9 10print(X.shape, "->", X_small.shape) # (569, 30) -> (569, 5)11print(list(X.columns[selector.get_support()]))1/3as_frame=True gives a pandas DataFrame, so you keep readable column names.
SelectKBest scores every feature against the target and keeps the top k. get_support() tells you which ones survived.
Save yourself the pain
Common mistakes
Oops
Running feature selection on the full dataset, then measuring accuracy with cross-validation.
Do this instead
Put the selector in a Pipeline with the model so it only ever sees the training folds.
Oops
Dropping a feature because its correlation with the target is low.
Do this instead
Some features only help in combination with others. Check with a model-based method before throwing it out.
Your mission
How few features do you need?
Quick check
Why is a 'customer_id' column usually removed before training?
Go deeper
- 1Practice filter methods (correlation, chi-square) and wrapper methods (RFE).
- 2Use feature importance from a tree-based model to prune weak features.
- 3Compare model performance with and without feature selection on the same dataset.
More topics at this stop
 Feature Scaling & Normalization
 One-Hot & Label Encoding
 Handling Imbalanced Data
 Hyperparameter Tuning (Grid/Random Search)
 Ensemble Methods (Bagging, Boosting)
 XGBoost & LightGBM
 Evaluation Metrics (Accuracy, Precision, Recall, F1)
 ROC-AUC
 Confusion Matrix
 Bias-Variance Tradeoff
 Overfitting & Regularization (L1/L2)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
