Metrics, Logs & Traces
Part of the Cloud Computing Roadmap
In short
When users say "the app is slow", you need three kinds of evidence: how often, what exactly happened, and where the time went. Those are metrics, logs and traces.
Metrics are numeric measurements over time, logs are discrete event records, and traces follow a single request across multiple services — together they give a complete picture of system behavior.
Think of it like this
The hospital ward
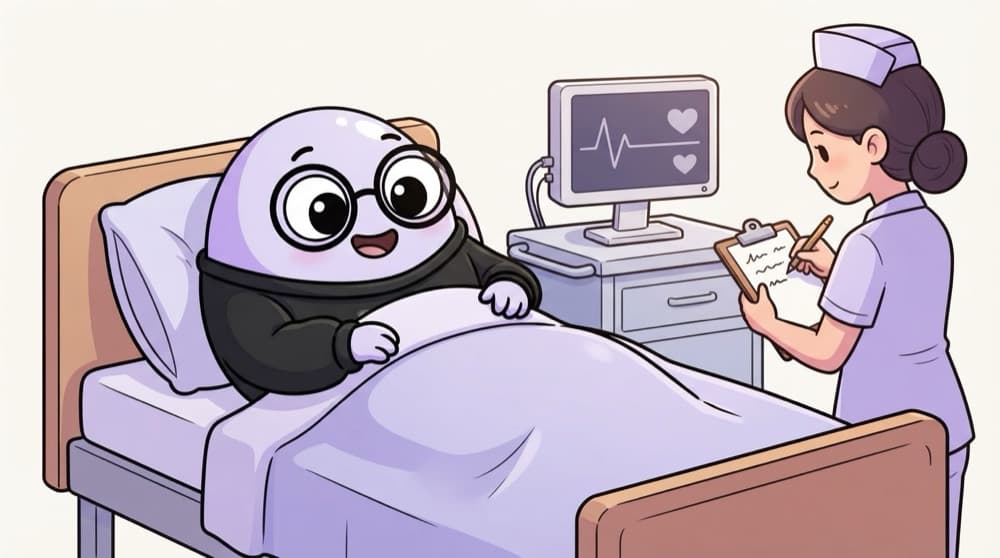
The bedside monitor shows heart rate as a live line. The nurse writes notes: "10:40, fever, gave paracetamol." The patient's file tracks their path from reception to X-ray to ward. Vitals, notes, route: metrics, logs, traces.
Watch it happen
Three signals, three questions
1/5Three kinds of data, each cheap or expensive in different ways, each answering a different question.
The big ideas
What you need to know
Metrics
Counters, gauges and histograms with labels. Watch label cardinality: a user_id label creates millions of series.
Logs
Structured JSON logs with consistent fields are searchable. Free-text print statements mostly aren't.
Traces
A trace is a tree of spans, one per step, all sharing a trace ID passed between services.
OpenTelemetry
An open standard and SDKs for emitting all three, so you can switch backends without re-instrumenting.
See it in code
Walk through the code
1console.log(JSON.stringify({2 level: "error",3 msg: "payment failed",4 orderId: 42,5 traceId: "4bf92f3577b34da6a3ce929d0e0e4736",6 durationMs: 812,7 err: "db timeout after 800ms",8}));1/3A level and a short, fixed message you can count and alert on.
One structured log line. Because traceId is a field, you can jump from this log to the full trace and back.
Save yourself the pain
Common mistakes
Oops
Logging every request in full detail at high traffic and calling it monitoring.
Do this instead
Use metrics for counts and rates, logs for details, and sample traces. Each costs differently.
Oops
Logging passwords, tokens or full card numbers while debugging.
Do this instead
Never log secrets or personal data. Mask fields before they ever reach the logger.
Your mission
Turn prints into signals
Quick check
Your error-rate graph spikes. Which signal tells you which service in the request path was slow?
Go deeper
- 1Identify a real debugging scenario and which pillar (metrics, logs, or traces) would help most.
- 2Learn why traces are especially critical in microservice or serverless architectures.
- 3Understand these three pillars are complementary, not redundant with each other.
More topics at this stop
 Cloud-Native Monitoring (CloudWatch, Stackdriver, Azure Monitor)
 Logging Best Practices
 Alerting & Notification Systems
 Dashboards for Cloud Infrastructure
 SLIs, SLOs & Error Budgets
 Cost Monitoring & Anomaly Detection
 Distributed Tracing Basics

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
