Monitoring & Alerting Setup Project
Part of the Cloud Computing Roadmap
In short
An app nobody watches is an app that fails quietly at 3 a.m. Wiring up dashboards, sensible alerts and a runbook shows you think about day two, not just launch day.
Deploy a full monitoring stack for one of your other portfolio projects — dashboards, meaningful alerts, and documented incident response steps, showing observability skills end to end.
Think of it like this
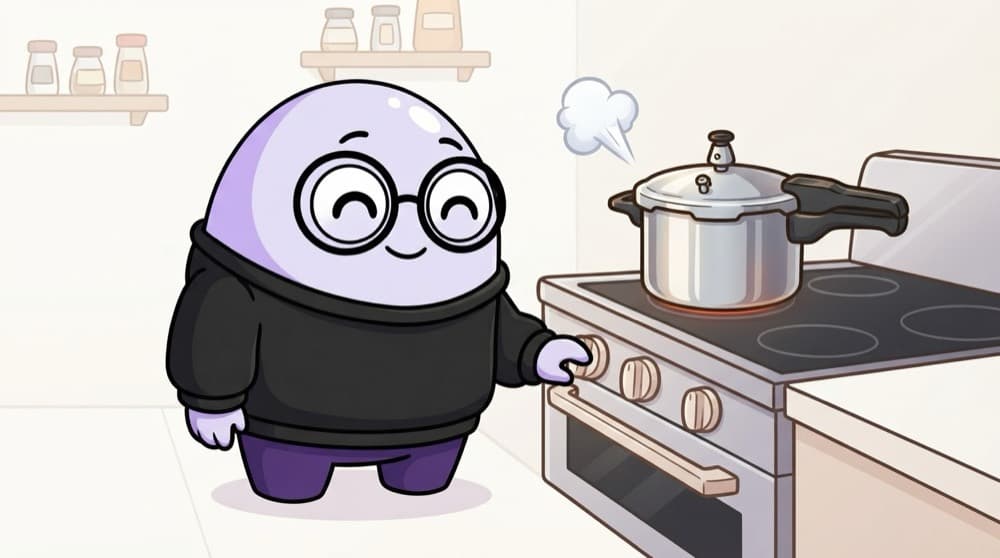
The cooker whistle
Nobody stands staring at the pressure cooker. You go do other things, and the whistle tells you when to act. Too few whistles and the dal burns. A whistle every ten seconds and you stop listening. Good alerts are like the right number of whistles.
Watch it happen
From error spike to your phone
5XX count: 37
1/6The load balancer publishes metrics every minute, including how many 5xx errors the app returned.
The big ideas
What you need to know
One clear dashboard
Requests, error rate, latency and saturation (CPU, memory, connections) on one screen for the app.
Alert on symptoms
Page on what users feel, like high errors or latency. CPU at 80% alone usually isn't worth waking up for.
Runbook per alert
Each alert links to a short page: what it means, first checks, how to fix, who to escalate to.
Test the alert
Trigger it on purpose, for example with a route that returns 500, and record that it fired.
See it in code
Walk through the code
1aws sns create-topic --name oncall-alerts2aws sns subscribe --topic-arn "$TOPIC_ARN" \3 --protocol email --notification-endpoint you@example.com4 5aws cloudwatch put-metric-alarm --alarm-name web-5xx-high \6 --namespace AWS/ApplicationELB --metric-name HTTPCode_Target_5XX_Count \7 --dimensions Name=LoadBalancer,Value=app/web-alb/50dc6c495c0c9188 \8 --statistic Sum --period 300 --evaluation-periods 1 \9 --threshold 10 --comparison-operator GreaterThanThreshold \10 --treat-missing-data notBreaching \11 --alarm-actions "$TOPIC_ARN" --ok-actions "$TOPIC_ARN"1/4Create a topic and subscribe your email. AWS sends a confirmation link first.
An SNS topic plus one alarm on app errors. Confirm the subscription email before testing, or nothing arrives.
Save yourself the pain
Common mistakes
Oops
Creating 40 alerts on day one, most of them on CPU and disk.
Do this instead
Start with three or four symptom alerts. Noisy alerts train everyone to ignore them.
Oops
Alerts that say only "ALARM: metric high" with no next step.
Do this instead
Name alerts clearly and link a runbook in the description.
Your mission
First milestone: one alert that fires
Quick check
Which alert is most useful to page someone at night?
Go deeper
- 1Instrument an existing project with custom metrics, not just default infrastructure metrics.
- 2Build a dashboard focused on your project's key health signals.
- 3Set up at least one alert rule with a clear, documented response plan.
More projects at this stop
 Deploy a 3-Tier Web Application on AWS / Azure / GCP
 Serverless API Project
 Infrastructure as Code Project (Multi-Environment)
 Highly Available Architecture Project
 Cost-Optimized Migration Case Study
 Portfolio Website or GitHub Showcase

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
