In short
Results day, a flash sale, a viral reel: traffic jumps without warning. Auto scaling adds servers when they're needed and removes them when they're not, so you don't stay up watching graphs.
Automatically adding or removing VM instances based on demand — a core mechanism for handling variable traffic without manual intervention, paired with a load balancer to distribute traffic to new instances.
Think of it like this
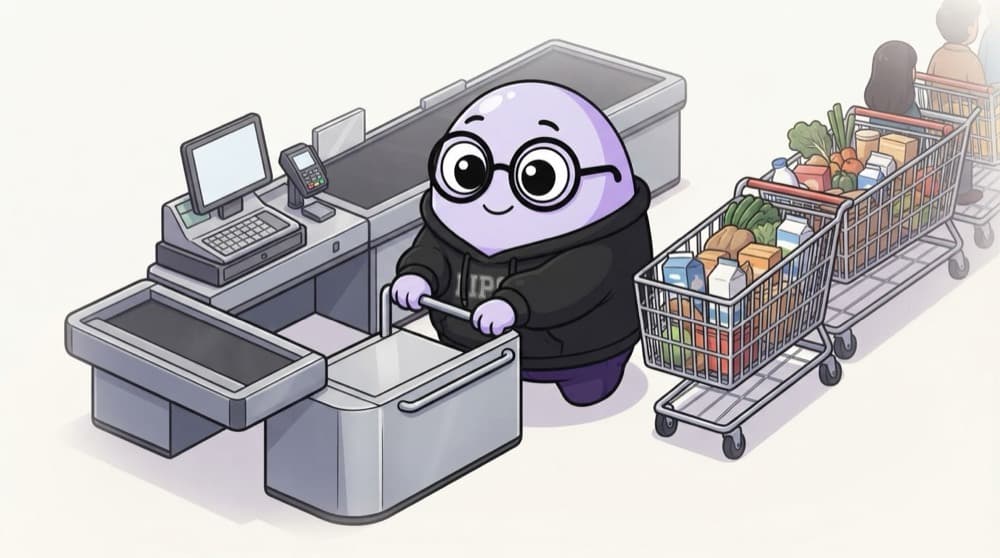
Extra billing counters
On a Sunday evening the supermarket manager sees the queue growing and opens two more counters. When the rush ends, those staff go back to stocking shelves. An auto scaling group is that manager for your servers.
Watch it happen
A traffic spike, handled
avg CPU 78% > 60%
1/6The group's average CPU crosses the 60% target you set. CloudWatch tells Auto Scaling.
The big ideas
What you need to know
Min, max, desired
Min is the floor, max is the ceiling, desired is how many should run right now. Scaling changes desired.
Launch template
The recipe for every new instance: image, type, security groups and user data script. Keep it up to date.
Target tracking
Say 'keep CPU around 60%' and the group adds or removes instances to hold that line.
Self-healing
If an instance fails health checks, the group terminates and replaces it. You get this even with no scaling policy.
See it in code
Walk through the code
1aws autoscaling create-auto-scaling-group \2 --auto-scaling-group-name web-asg \3 --launch-template LaunchTemplateName=web-lt \4 --min-size 2 --max-size 6 --desired-capacity 2 \5 --vpc-zone-identifier "subnet-aaa111,subnet-bbb222"6 7aws autoscaling put-scaling-policy \8 --auto-scaling-group-name web-asg \9 --policy-name keep-cpu-60 \10 --policy-type TargetTrackingScaling \11 --target-tracking-configuration '{"PredefinedMetricSpecification":{"PredefinedMetricType":"ASGAverageCPUUtilization"},"TargetValue":60}'1/3Create the group from an existing launch template.
Two subnets in different zones means one zone going down doesn't take all your servers with it.
Save yourself the pain
Common mistakes
Oops
Storing user uploads or sessions on the instance's own disk.
Do this instead
Instances come and go. Keep state in S3, a database or a cache so any instance can serve any user.
Oops
Setting max size very high with no billing alert.
Do this instead
A bug or attack can scale you to the max. Set a sensible ceiling and a budget alert.
Your mission
Watch it heal
Quick check
Your group has min 2, max 8, desired 2. Traffic triples and CPU passes the target. What changes first?
Go deeper
- 1Set up an auto scaling group with a minimum, maximum, and desired instance count.
- 2Configure a scaling policy based on a metric like CPU utilization.
- 3Learn why auto scaling groups are almost always paired with a load balancer.
More topics at this stop
 Virtual Machines (EC2, Compute Engine, Azure VMs)
 Instance Types & Sizing
 Load Balancing Compute
 Containers Overview (Docker Basics)
 Container Orchestration Overview (Kubernetes / ECS)
 Serverless Computing (Lambda / Functions)
 Choosing Compute: VM vs Container vs Serverless
 Spot & Reserved Instances
 Compute Cost Optimization

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
