A/B Testing Deployed Models
Part of the Data Science Roadmap
In short
A new model that scores better offline can still lose with real users. An A/B test runs old and new models side by side on live traffic, so the decision rests on evidence.
Rolling out a new model to a subset of traffic and comparing its real-world business impact against the current model — the ultimate validation that a model actually improves outcomes, not just offline metrics.
Think of it like this
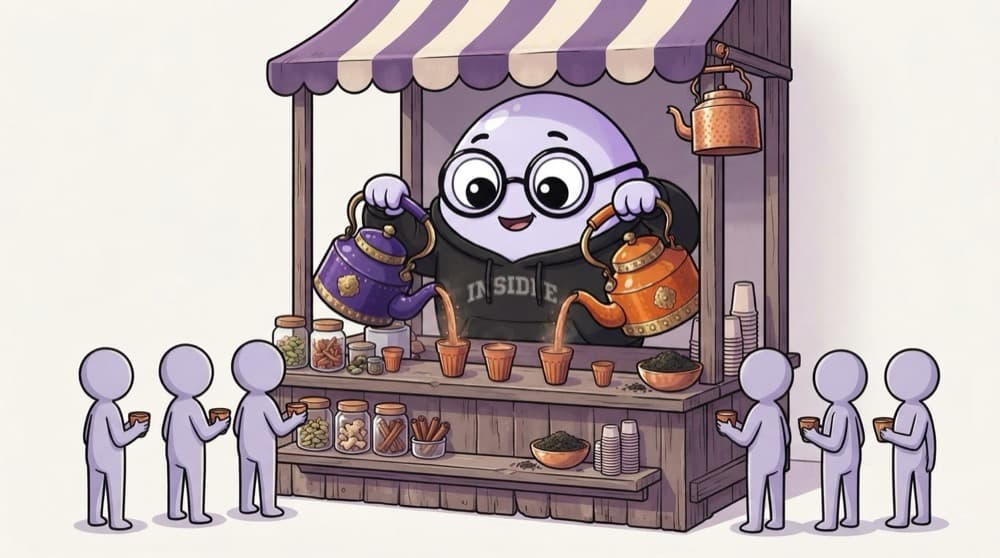
Two chai recipes, one stall
A chai wala tries a new masala recipe. Instead of switching everyone, he serves half his customers the old kettle and half the new one, chosen at random, for two weeks. Then he counts repeat buyers for each kettle. Only then does he decide.
Watch it happen
Routing live users to two models
GET /recommendations
1/6A user opens the app and asks for product suggestions.
The big ideas
What you need to know
Pick the metric first
Decide the business metric, like click rate or orders, and the test length before starting.
Random, sticky assignment
Users must be split randomly, and each should stay in one group for the whole test.
Enough users
Small differences need many users to detect. Estimate the sample size up front.
Canary first
Send a small share, like 5%, to the new model first to catch crashes before a full 50/50 test.
See it in code
Walk through the code
1from statsmodels.stats.proportion import proportions_ztest2 3# clicks on recommendations, after two weeks4conversions = [530, 584] # model A, model B5users = [10000, 10000]6 7stat, p = proportions_ztest(conversions, users)8print(f"A: {530/10000:.1%} B: {584/10000:.1%} p-value: {p:.3f}")1/3Clicks and users in each group.
B looks better, 5.8% vs 5.3%, but the p-value comes out around 0.1. That isn't strong evidence yet, so keep the test running.
Save yourself the pain
Common mistakes
Oops
Checking results daily and stopping as soon as B looks ahead.
Do this instead
Fix the sample size or duration in advance. Peeking and stopping early produces false wins.
Oops
Judging the new model only on offline accuracy.
Do this instead
Offline metrics are a filter. The live business metric in a fair test is the real verdict.
Your mission
Plan an A/B test
Quick check
Why should each user stay in the same group for the whole test?
Go deeper
- 1Design an A/B test plan comparing a new model version against the current production model.
- 2Learn why offline accuracy improvements don't always translate to better business outcomes.
- 3Connect this back to the A/B testing statistics fundamentals from earlier phases.
More topics at this stop
 Saving & Loading Models (Pickle, joblib)
 Building an API for a Model (Flask / FastAPI)
 Docker Basics for ML
 Model Versioning
 CI/CD for ML Pipelines (Overview)
 Model Monitoring & Drift Detection
 Cloud ML Platforms (SageMaker, Vertex AI Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
