CI/CD for ML Pipelines (Overview)
Part of the Data Science Roadmap
In short
Retraining and deploying by hand is slow and error-prone. CI/CD runs tests, training checks and deployment automatically every time someone pushes code, so bad models get caught early.
Automating the testing and deployment of model updates — similar to software CI/CD, but also needs to validate model performance, not just that the code runs without errors.
Think of it like this
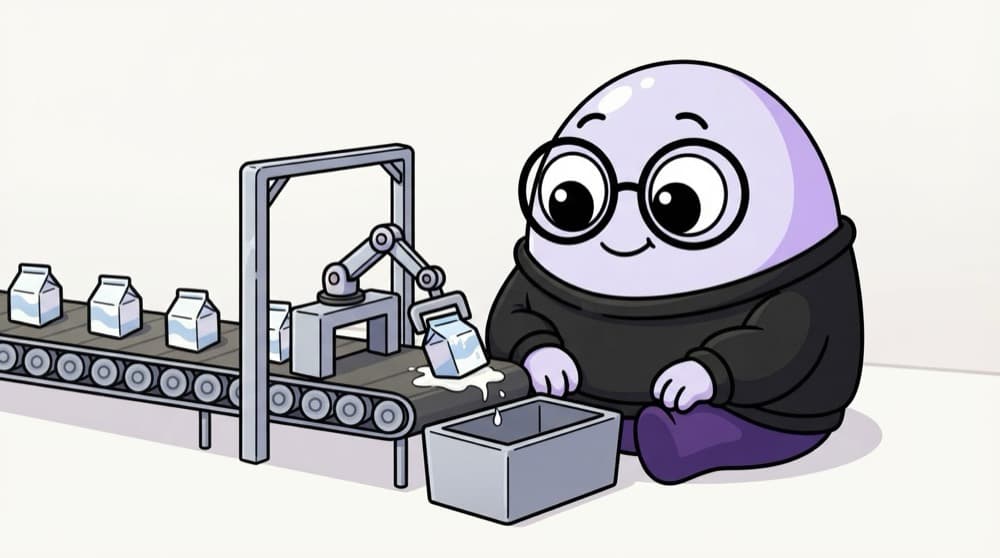
The dairy packing line
At a dairy plant, every milk packet rolls down a belt past checks: weight, seal, leaks. A leaking packet is pushed off the belt before it reaches a truck. CI/CD is that belt for your code and models, with automatic checks at each station.
Watch it happen
What runs on every push
1/5You push code or a config change to GitHub. The workflow starts automatically.
The big ideas
What you need to know
CI = test every change
Continuous integration runs checks on each push so problems show up within minutes.
CD = release automatically
Continuous delivery ships passing builds, often after a manual approval step for production.
ML adds data checks
Unlike normal apps, ML pipelines also test data quality and model metrics, not just code.
Scheduled retraining
Pipelines can also run on a schedule, like weekly, to retrain on fresh data.
See it in code
Walk through the code
1name: ml-ci2on: [push]3jobs:4 test-and-train:5 runs-on: ubuntu-latest6 steps:7 - uses: actions/checkout@v48 - uses: actions/setup-python@v59 with:10 python-version: "3.12"11 - run: pip install -r requirements.txt12 - run: pytest tests/13 - run: python train.py --out model.joblib14 - run: python evaluate.py --model model.joblib --min-f1 0.801/4Run this workflow on every push.
A GitHub Actions workflow in .github/workflows/ml-ci.yml. evaluate.py should exit with an error if F1 falls below the threshold.
Save yourself the pain
Common mistakes
Oops
Retraining on the full dataset inside every CI run.
Do this instead
Use a small sample for fast checks on each push. Run full training on a schedule or on demand.
Oops
Deploying any model that trains without errors.
Do this instead
Add a quality gate: the new model must meet a metric threshold before release.
Your mission
Your first ML workflow
Quick check
What does an ML pipeline check that a normal web app's CI usually doesn't?
Go deeper
- 1Read an overview of how ML pipelines differ from standard software CI/CD.
- 2Learn what an automated 'model performance gate' before deployment might check.
- 3Understand this is often owned jointly with ML/platform engineers, not solely by a data scientist.
More topics at this stop
 Saving & Loading Models (Pickle, joblib)
 Building an API for a Model (Flask / FastAPI)
 Docker Basics for ML
 Model Versioning
 Model Monitoring & Drift Detection
 A/B Testing Deployed Models
 Cloud ML Platforms (SageMaker, Vertex AI Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
