In short
A test that fails one run in ten teaches the team a dangerous habit: 'just rerun it'. Soon real bugs get rerun away too. Managing flaky tests protects trust in the whole suite.
Identifying and fixing tests that fail intermittently without a real underlying bug — flaky tests erode trust in the entire suite, since teams start ignoring failures assuming they're 'just flaky'.
Think of it like this
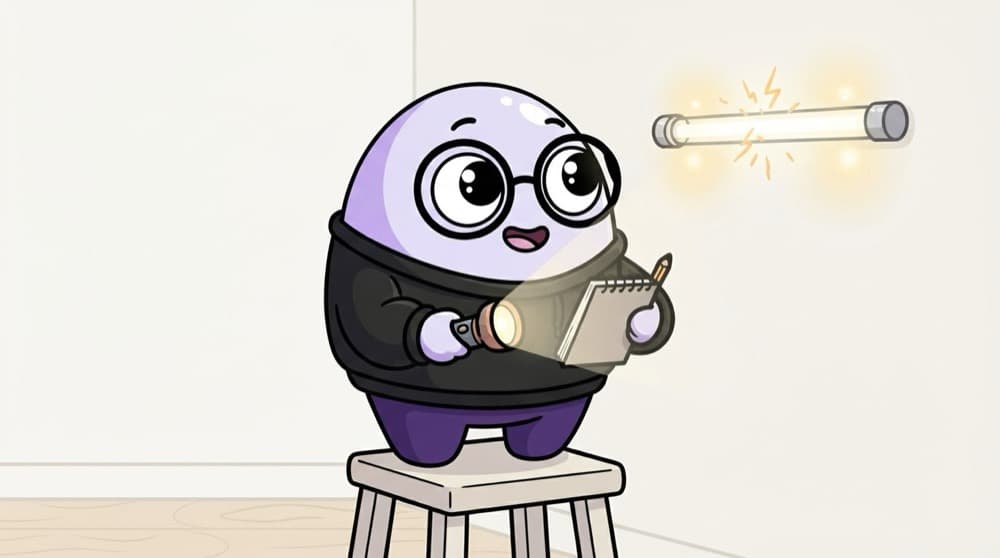
The flickering tube light
A tube light that flickers now and then is worse than a dead one. You can't tell if the problem is the choke, the wiring or the power. So everyone ignores it. A flaky test is that tube light in your pipeline.
Watch it happen
Where flakiness usually comes from
1/5Same code, same test, different result. The cause is almost always one of four families.
The big ideas
What you need to know
Prove it's flaky
Run the test many times in a loop. If it fails sometimes with no code change, it's flaky.
Quarantine fast
Move a known flaky test out of the blocking suite, tag it, and log a ticket. Don't let it block everyone.
Fix the cause
Replace sleeps with waits for real conditions, give tests their own data, and mock unreliable outside services.
Retries are a painkiller
Auto-retry hides the symptom. Use it, but track which tests needed a retry and fix them.
How it works
A simple flaky test process
- 1
Detect
The report marks tests that passed only on retry as flaky.
- 2
Quarantine
Tag it and move it out of the merge-blocking run, with a ticket and an owner.
- 3
Fix
Reproduce it in a loop, find the root cause and fix it.
- 4
Return
Run it 50 times clean, then move it back into the blocking suite.
See it in code
Walk through the code
1// Flaky: guesses how long the page needs2await page.click("#pay");3await page.waitForTimeout(3000);4expect(await page.textContent(".status")).toBe("Paid");5 6// Stable: waits until the condition is actually true7await page.getByRole("button", { name: "Pay" }).click();8await expect(page.locator(".status")).toHaveText("Paid");1/2A fixed 3-second sleep. Too short on a slow day, wasted time on a fast one.
Playwright's expect(...).toHaveText keeps retrying until the text appears or the timeout runs out. No guessing.
Save yourself the pain
Common mistakes
Oops
Turning on 3 retries for everything and calling the suite stable.
Do this instead
Keep retries low and track every test that needed one. Each is a bug in the test or the app.
Oops
Deleting a flaky test because it's annoying.
Do this instead
Quarantine it with an owner. Sometimes the flakiness is a real race condition in the app.
Your mission
Catch a flake in the act
Quick check
A login test fails about once a week, always with a timeout on a shared staging server. What should you do first?
Go deeper
- 1Identify a flaky test pattern (from your own practice work or a public example) and diagnose the likely cause.
- 2Learn common flakiness causes: poor waits, shared test data, timing issues, and environment instability.
- 3Practice a policy for handling flaky tests: quarantine, investigate, and fix rather than ignore indefinitely.
More topics at this stop
 CI/CD Concepts for QA
 Integrating Tests Into Jenkins / GitHub Actions
 Test Reporting & Dashboards
 Parallel Test Execution
 Containerized Testing (Docker Basics)
 Test Environment Automation
 Continuous Testing Pipelines

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
