Data Pipelines (Concept)
Part of the AI Engineer Roadmap
In short
A model is only as fresh as its data. A pipeline is the set of steps that moves raw data into a clean, trusted table, again and again, without someone running cells by hand.
The chain of steps — extract, transform, load, validate — that moves raw data into a form models can train on, run reliably and repeatably.
Think of it like this
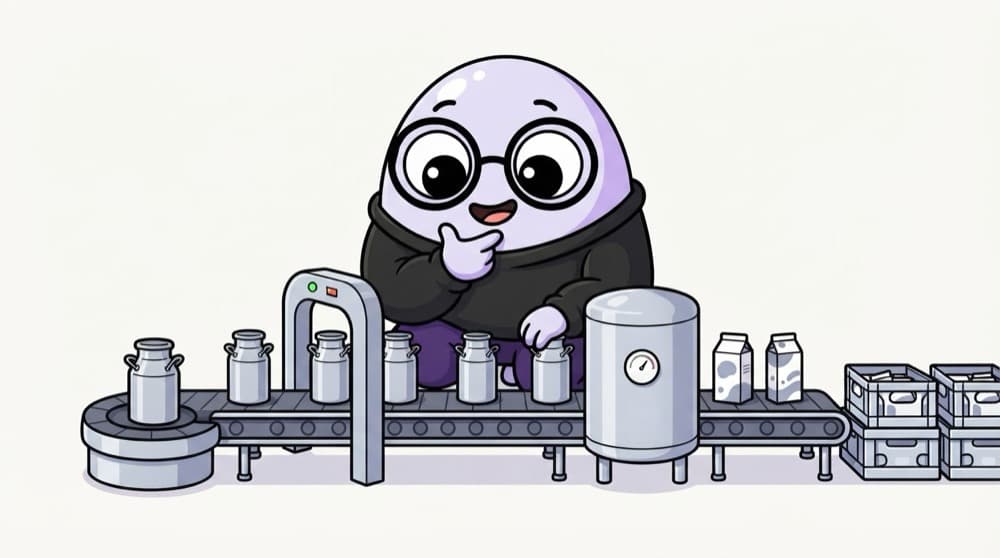
The dairy cooperative
Every morning, milk is collected from villages, tested for quality, heated, packed and sent to shops. If a can fails the test, it's set aside, not mixed in. A data pipeline is the same daily routine: collect, check, clean, store, and flag anything that looks off.
Watch it happen
One daily run
1/5Pull yesterday's orders from the app database and the payments API.
The big ideas
What you need to know
Repeatable
The same code runs every day with no manual steps. If it needs a human to click, it isn't a pipeline yet.
Idempotent
Running a day twice should give the same result, not double the rows. Overwrite by date instead of blindly appending.
Validate early
Catch bad data before it reaches the model. A failed check that stops the run beats silently training on junk.
Observable
Log row counts and timings for every step, so you can tell when something quietly changed.
See it in code
Walk through the code
1import pandas as pd2def extract(day: str) -> pd.DataFrame:3 return pd.read_csv(f"raw/orders_{day}.csv")4 5def validate(df: pd.DataFrame) -> None:6 assert len(df) > 0, "no rows"7 assert (df["amount"] >= 0).all(), "negative amounts"8 assert df["order_id"].is_unique, "duplicate order ids"9 10def transform(df: pd.DataFrame) -> pd.DataFrame:11 df["created_at"] = pd.to_datetime(df["created_at"])12 return df.assign(hour=df["created_at"].dt.hour)13 14def run(day: str) -> None:15 df = extract(day); validate(df)16 transform(df).to_parquet(f"clean/orders/{day}.parquet") # overwrite = idempotent1/4Extract reads one day's raw file. The date is a parameter, so any day can be rerun.
Each step is a small function you can test on its own. Writing one file per day means rerunning a day replaces it instead of duplicating it.
Save yourself the pain
Common mistakes
Oops
Appending every run to the same table, so a retry doubles yesterday's data.
Do this instead
Write by partition (like date) and overwrite it. Reruns become safe.
Oops
Keeping the pipeline as a notebook that someone runs each morning.
Do this instead
Move it into a script with functions, then schedule it with cron or a tool like Airflow.
Your mission
Build a three-step mini pipeline
Quick check
Your pipeline failed halfway and you rerun it for the same day. What property makes this safe?
Go deeper
- 1Diagram a data pipeline for a project you're building end-to-end.
- 2Learn why pipelines need to be idempotent and rerunnable.
- 3Identify where data quality checks should sit in a pipeline.
More topics at this stop
 SQL Basics (SELECT, JOIN, GROUP BY)
 Working with Databases in Python
 ETL vs ELT
 Batch vs Streaming Data
 Data Warehouses (Concept)
 Airflow Basics (Overview)
 Working with APIs for Data Collection
 Web Scraping (BeautifulSoup)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
