Web Scraping (BeautifulSoup)
Part of the AI Engineer Roadmap
In short
When there's no API, the data is still in the page's HTML. BeautifulSoup turns that HTML into a tree you can search, so you can pull out titles, prices and links in a few lines.
Parsing HTML to extract structured data from websites that don't offer an API — a common way to build custom datasets for niche AI projects.
Think of it like this
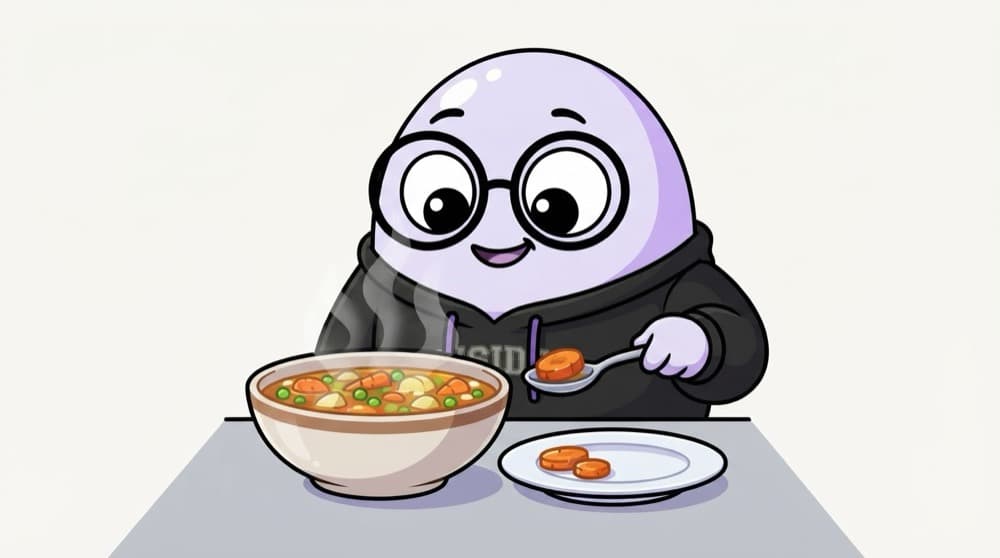
Fishing carrots out of the soup
A bowl of mixed vegetable soup has everything in it. If you only want carrots, you look for orange cubes and lift just those out with your spoon. HTML is the soup, a CSS selector describes 'orange cubes', and BeautifulSoup is the spoon. Fitting, given the name.
Watch it happen
soup.select('div.product')
1/4BeautifulSoup parses the HTML into a tree of tags, the same structure you see in DevTools.
The big ideas
What you need to know
Find selectors in DevTools
Right-click, Inspect, and look for a class or tag that wraps each item. Test it in the console with document.querySelectorAll.
select and select_one
select returns a list of every match. select_one returns the first match or None.
Text and attributes
.get_text(strip=True) gives clean text. tag['href'] or tag.get('href') reads an attribute.
Scrape responsibly
Check robots.txt and the terms, go slowly, and never scrape behind a login or collect personal data you have no right to.
See it in code
Walk through the code
1from bs4 import BeautifulSoup2 3html = """4<div class="product"><h2 class="title">Chai Mug</h2>5 <span class="price">₹249</span><a href="/p/12">View</a></div>6<div class="product"><h2 class="title">Kettle</h2><a href="/p/13">View</a></div>7"""8 9soup = BeautifulSoup(html, "html.parser")10for card in soup.select("div.product"):11 title = card.select_one("h2.title").get_text(strip=True)12 price_tag = card.select_one(".price")13 price = price_tag.get_text(strip=True) if price_tag else None14 link = card.find("a")["href"]15 print(title, price, link) # Chai Mug ₹249 /p/12, then Kettle None /p/131/4A tiny page with two product cards. The second has no price.
Practise on a small HTML string first, then swap in requests.get(url).text. Installing lxml and using it as the parser is faster on big pages.
Save yourself the pain
Common mistakes
Oops
Expecting BeautifulSoup to see content that JavaScript loads after the page opens.
Do this instead
Check View Source. If the data isn't there, look for the JSON API the page calls in the Network tab, or use a browser tool like Playwright.
Oops
Chaining .find().find().text with no checks, then crashing on one odd card.
Do this instead
Check each select_one result for None, or wrap per-item parsing in try/except and log what failed.
Your mission
Parse a real practice page
Quick check
card.select_one('.price') returns None for some products. What's the right fix?
Go deeper
- 1Parse a static HTML page with BeautifulSoup and extract specific elements.
- 2Learn to use browser dev tools to identify the right selectors.
- 3Understand the legal and ethical boundaries of scraping before doing it at scale.
More topics at this stop
 SQL Basics (SELECT, JOIN, GROUP BY)
 Working with Databases in Python
 Data Pipelines (Concept)
 ETL vs ELT
 Batch vs Streaming Data
 Data Warehouses (Concept)
 Airflow Basics (Overview)
 Working with APIs for Data Collection

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
