
Working with APIs for Data Collection
Part of the AI Engineer Roadmap
In short
Need 10,000 GitHub issues or a year of weather readings for a dataset? An API usually gives clean, structured data faster and more reliably than scraping. Collect it politely and completely.
Pulling structured data from public and third-party APIs for training or analysis — often faster and more reliable than scraping.
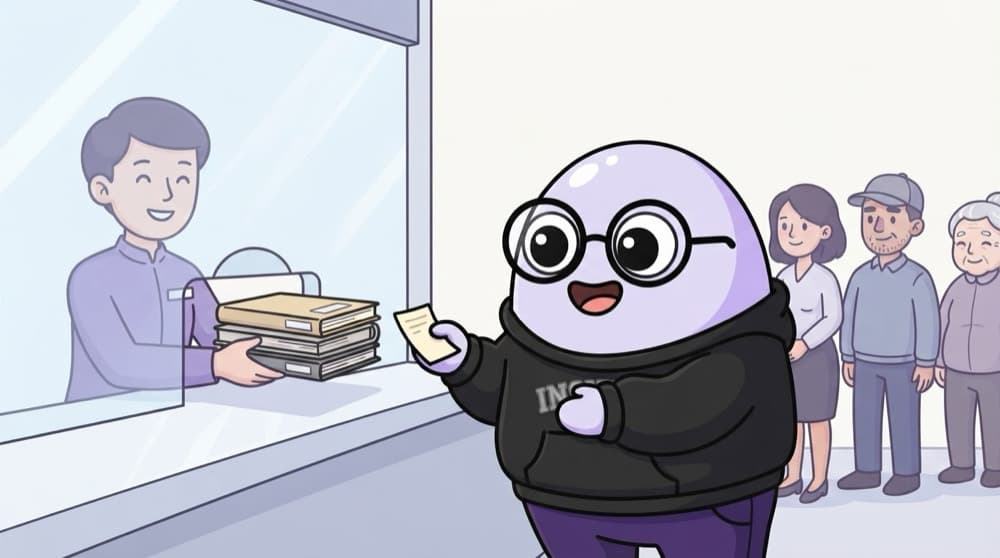
Think of it like this
The bank token counter
You take a token and wait your turn. The clerk hands over a bundle of files, says 'that's 100, come back for the next set', and there's a limit on visits per hour. APIs work the same way: pages of results, a cursor for the next page, and rate limits you must respect.
Watch it happen
Collecting every page
GET ?page=1&per_page=100
1/5Ask for the first page of results, as many per page as the API allows.
The big ideas
What you need to know
Pagination
APIs return data in pages. Follow page numbers, a next cursor or a next link until there's nothing left.
Rate limits
Check the docs for limits. On a 429, wait for the Retry-After time. Add a small sleep between calls anyway.
Save raw first
Write each page to disk as JSON Lines before cleaning. If your parsing has a bug, you won't need to re-download.
Authenticate properly
An API key or token often raises your limit. Keep it in an environment variable, never in the notebook.
See it in code
Walk through the code
1import json, time2import requests3 4url = "https://api.github.com/repos/pandas-dev/pandas/issues"5params = {"state": "closed", "per_page": 100, "page": 1}6 7with open("issues.jsonl", "w", encoding="utf-8") as f:8 while params["page"] <= 5:9 r = requests.get(url, params=params, timeout=10)10 if r.status_code == 429:11 time.sleep(int(r.headers.get("Retry-After", 30))); continue12 r.raise_for_status()13 batch = r.json()14 if not batch: break15 f.writelines(json.dumps(item) + "\n" for item in batch)16 params["page"] += 1; time.sleep(1)1/4The endpoint and query parameters, including page size and starting page.
GitHub's public API works without a key but at a low hourly limit, so this stops after 5 pages. Load the result later with pd.read_json('issues.jsonl', lines=True).
Save yourself the pain
Common mistakes
Oops
Collecting only the first page and thinking that's the whole dataset.
Do this instead
Check the docs for how pagination works and loop until the API says there's nothing more.
Oops
Cleaning data in the same loop that downloads it, then losing everything on one parsing error.
Do this instead
Save the raw responses first. Clean in a separate step that you can rerun freely.
Your mission
Build a small API dataset
Quick check
Your collector gets a 429 response with Retry-After: 60. What should it do?
Go deeper
- 1Collect a small dataset from a public API and save it locally.
- 2Learn to handle pagination when an API returns data in pages.
- 3Practice respecting rate limits with retries and backoff.
More topics at this stop
 SQL Basics (SELECT, JOIN, GROUP BY)
 Working with Databases in Python
 Data Pipelines (Concept)
 ETL vs ELT
 Batch vs Streaming Data
 Data Warehouses (Concept)
 Airflow Basics (Overview)
 Web Scraping (BeautifulSoup)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
