Named Entity Recognition
Part of the AI Engineer Roadmap
In short
Resumes, news, invoices and chat logs are full of names, places, companies and dates buried in plain text. NER pulls them out automatically, so you can search, count and link them.
Identifying and classifying entities (people, organizations, locations, dates) in text — a common building block for information extraction pipelines.
Think of it like this
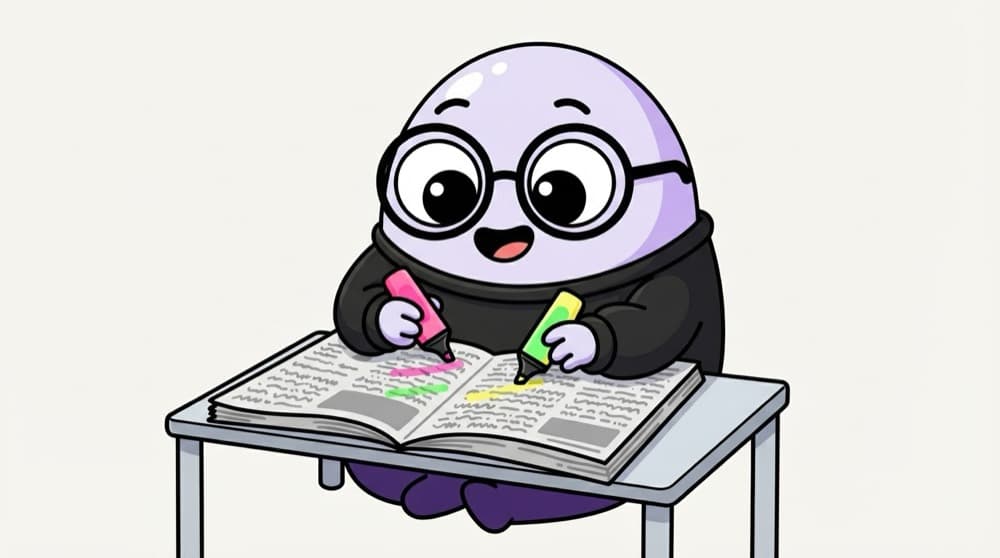
Colour-coding the newspaper
Exam aspirants read the newspaper with three highlighters: pink for people, green for places, yellow for dates. After a month, they can flip back and find every mention at a glance. An NER model does that highlighting for you, on millions of documents.
Watch it happen
Tagging one sentence
1/5The sentence is split into tokens. The model will give each one a tag.
The big ideas
What you need to know
It's token classification
NER gives every token a label. B- starts an entity, I- continues it, O means not an entity.
Common entity types
Person, organisation, location and date are standard. Domain models add things like drug names, PAN numbers or product codes.
Context decides
'Apple' can be a fruit or a company, 'Jordan' a person or a country. The surrounding words settle it.
Custom entities need training
Off-the-shelf models won't know your company's product names. Label a few hundred examples and fine-tune.
See it in code
Walk through the code
1# pip install spacy && python -m spacy download en_core_web_sm2import spacy3 4nlp = spacy.load("en_core_web_sm")5doc = nlp("Priya Nair joined Infosys in Pune in March 2024.")6 7for ent in doc.ents:8 print(ent.text, "->", ent.label_)9# typically: Priya Nair -> PERSON, Infosys -> ORG, Pune -> GPE, March 2024 -> DATE1/3Load a small pretrained pipeline and run it over a sentence.
spaCy's small English model finds common entities in one call. GPE means a country, state or city.
Save yourself the pain
Common mistakes
Oops
Trusting a general model on legal or medical text without checking.
Do this instead
Test on 50 real documents from your domain first. If it misses key entities, fine-tune on labelled examples.
Oops
Measuring NER by token accuracy.
Do this instead
Most tokens are O, so accuracy looks great anyway. Use entity-level precision, recall and F1.
Your mission
Extract entities from the news
Quick check
In BIO tagging, what does 'I-ORG' on a token mean?
Go deeper
- 1Run a pretrained NER model (spaCy or Hugging Face) on real text and inspect the output.
- 2Learn the standard entity tagging scheme (BIO tagging).
- 3Fine-tune an NER model on a small custom-labeled dataset.
More topics at this stop
 Text Preprocessing (Tokenization, Stemming, Lemmatization)
 Bag of Words & TF-IDF
 Word Embeddings (Word2Vec, GloVe)
 Sentiment Analysis
 Hugging Face Transformers Library
 Pretrained NLP Models (BERT, RoBERTa)
 Sequence Classification
 Text Summarization
 Question Answering Models

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
