Question Answering Models
Part of the AI Engineer Roadmap
In short
Ask a question, get the exact answer from a document. QA models power help-desk bots and document search, and they're a key building block behind retrieval-augmented chatbots.
Models that extract or generate an answer to a question given a context passage — the core mechanism behind search-augmented and RAG-based assistants.
Think of it like this
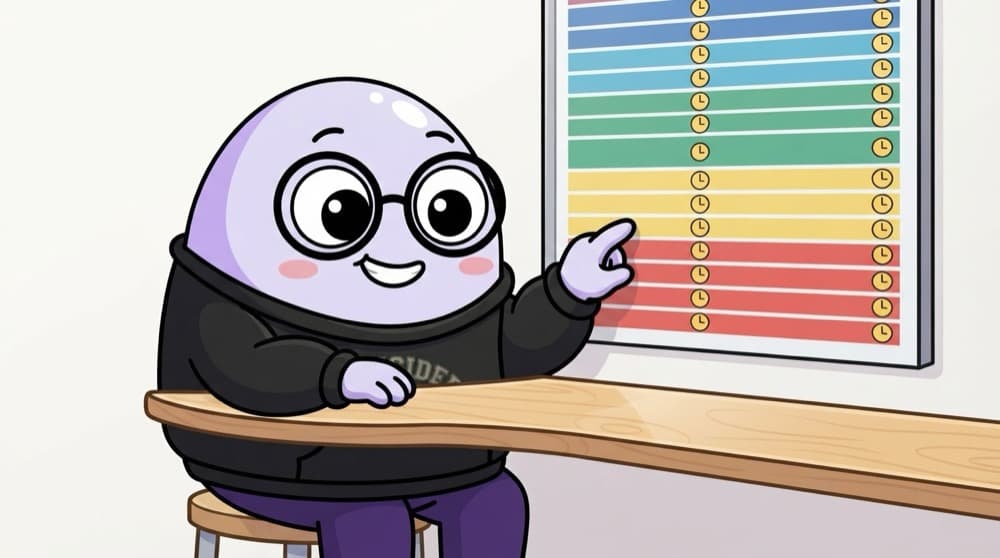
The railway enquiry counter
You ask the enquiry clerk when the evening train to Chennai leaves. He runs his finger down the timetable, stops at the right row and points: 6:40 pm. He doesn't invent anything, he finds it. An extractive QA model points to the answer inside your text.
Watch it happen
Finding the answer span
1/4Question: 'When does the library close?' The model reads the question and this context together.
The big ideas
What you need to know
Extractive QA predicts a span
The model outputs a start score and an end score for each token, then picks the best valid span.
Sometimes there's no answer
Models trained on SQuAD 2.0 can say 'not in the text' instead of forcing a guess. Check the score.
Retrieve first, then read
For many documents, first find the few relevant passages with search, then run QA on those. That's the core of RAG.
Generative QA
LLMs write answers in their own words. More flexible, but they can make things up if the context lacks the answer.
See it in code
Walk through the code
1from transformers import pipeline2 3qa = pipeline("question-answering", model="deepset/roberta-base-squad2")4 5context = ("The central library opens at 8 am and closes at 10 pm on weekdays. "6 "On Sundays it is open only from 10 am to 4 pm.")7 8for q in ["When does the library close on weekdays?", "Is it open on Sundays?"]:9 ans = qa(question=q, context=context)10 print(q, "->", ans["answer"], round(ans["score"], 2))1/3Load a model trained to find answer spans, including questions that have no answer.
A RoBERTa model fine-tuned on SQuAD 2.0. The answer is always a span copied from the context.
Save yourself the pain
Common mistakes
Oops
Expecting an extractive QA model to answer yes/no or summarise reasons.
Do this instead
It can only copy a span. For yes/no or explanations, use a generative model with the context.
Oops
Passing a whole book as the context.
Do this instead
Contexts longer than the model's limit are split into windows. Retrieve the relevant passages first for speed and accuracy.
Your mission
Build a mini FAQ bot
Quick check
What does an extractive QA model actually output?
Go deeper
- 1Run a pretrained extractive QA model (e.g. fine-tuned BERT on SQuAD) on real passages.
- 2Learn the difference between extractive QA and generative QA.
- 3Understand how this connects directly to the retrieval-augmented generation you'll build later.
More topics at this stop
 Text Preprocessing (Tokenization, Stemming, Lemmatization)
 Bag of Words & TF-IDF
 Word Embeddings (Word2Vec, GloVe)
 Named Entity Recognition
 Sentiment Analysis
 Hugging Face Transformers Library
 Pretrained NLP Models (BERT, RoBERTa)
 Sequence Classification
 Text Summarization

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
