Sequence Classification
Part of the AI Engineer Roadmap
In short
Spam or not, angry or calm, billing or technical issue. Putting a label on a whole piece of text is the most common NLP job in industry, and fine-tuning a pretrained model is how it's done today.
Classifying an entire piece of text into a category — the task family that covers sentiment analysis, topic classification, spam detection and intent recognition.
Think of it like this
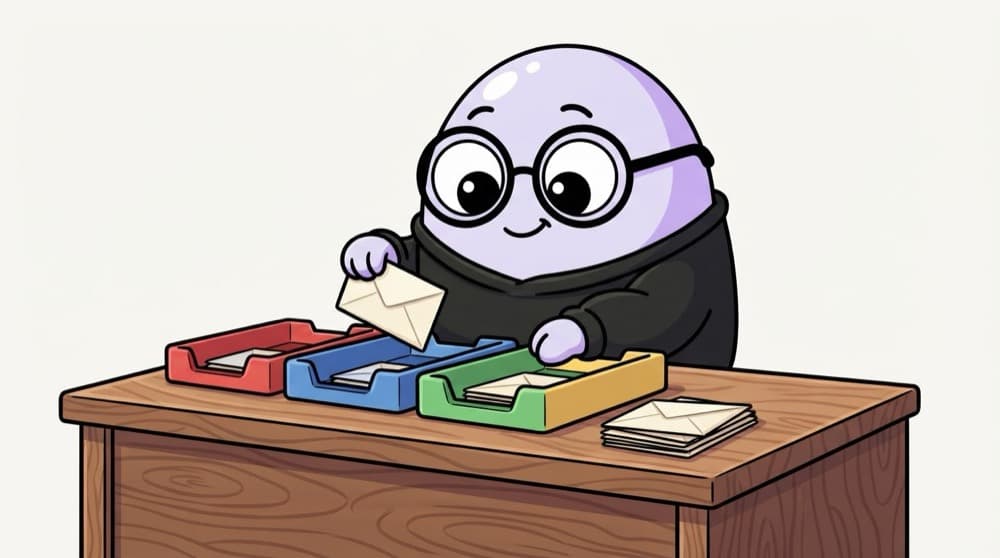
The college office trays
The college office gets hundreds of letters a week. The clerk reads each one and drops it in a tray: fees, hostel, exams, other. She doesn't need every word, just the gist. A sequence classifier reads the whole text and drops it into the right tray.
Watch it happen
From text to label
1/6Input: 'My hostel fee receipt hasn't been updated on the portal.'
The big ideas
What you need to know
One label per text
Unlike NER, which labels each token, sequence classification gives one label to the whole sentence or document.
Fine-tune, don't start from zero
Load a pretrained model with num_labels set, then train on a few thousand labelled examples.
Multi-label is different
If a text can have several labels at once, use sigmoid outputs and binary cross-entropy instead of softmax.
Watch class balance
If 90% of tickets are 'other', report per-class F1, not just accuracy.
See it in code
Walk through the code
1from datasets import load_dataset2from transformers import AutoTokenizer, AutoModelForSequenceClassification, Trainer, TrainingArguments3 4name = "distilbert/distilbert-base-uncased"5data = load_dataset("imdb")6tok = AutoTokenizer.from_pretrained(name)7data = data.map(lambda b: tok(b["text"], truncation=True, max_length=256), batched=True)8 9model = AutoModelForSequenceClassification.from_pretrained(name, num_labels=2)10args = TrainingArguments("out", per_device_train_batch_size=16, num_train_epochs=1)11trainer = Trainer(model=model, args=args, processing_class=tok,12 train_dataset=data["train"].shuffle(seed=0).select(range(2000)),13 eval_dataset=data["test"].shuffle(seed=0).select(range(500)))14trainer.train()15print(trainer.evaluate())1/4Load the IMDB reviews and tokenise every review, cutting long ones at 256 tokens.
Fine-tuning DistilBERT on 2,000 movie reviews. Use a GPU runtime; on a CPU this is very slow.
Save yourself the pain
Common mistakes
Oops
Fine-tuning with a high learning rate like 1e-2.
Do this instead
Pretrained transformers need small learning rates, typically around 2e-5 to 5e-5, or they forget what they learnt.
Oops
Truncating long documents without checking where the key information sits.
Do this instead
If the important part is at the end, truncation cuts it off. Look at your data and chunk if needed.
Your mission
Train your own classifier
Quick check
In BERT-style sequence classification, which token's output is commonly used to represent the whole text?
Go deeper
- 1Fine-tune a transformer for sequence classification on a labeled dataset.
- 2Learn to evaluate with a proper classification report, not just accuracy.
- 3Practice handling class imbalance in a text classification setting.
More topics at this stop
 Text Preprocessing (Tokenization, Stemming, Lemmatization)
 Bag of Words & TF-IDF
 Word Embeddings (Word2Vec, GloVe)
 Named Entity Recognition
 Sentiment Analysis
 Hugging Face Transformers Library
 Pretrained NLP Models (BERT, RoBERTa)
 Text Summarization
 Question Answering Models

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
