In short
When one database machine can't hold all the data or handle all the writes, you split the data across several. Each piece is a shard. Powerful, and painful if you pick the wrong key.
Splitting a single large database into multiple smaller databases (shards), each holding a subset of the data — used when a single database server can no longer hold or serve all your data.
Think of it like this
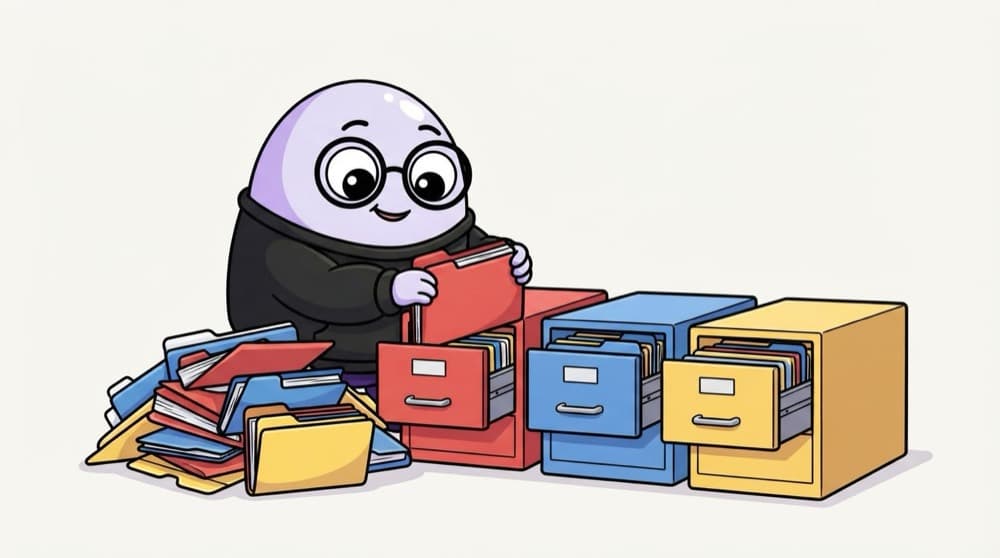
Filing cabinets by colour
A school office has too many files for one cabinet. So it splits them: red folders for classes 1 to 4, yellow for 5 to 8, blue for 9 to 12. Finding a file is quick if you know the class. Finding 'every student named Riya' means opening every cabinet.
Watch it happen
Sharding by user_id % 3
1/5Six users, three shards. The shard key is user_id, and the rule is user_id % 3.
The big ideas
What you need to know
The shard key is everything
Pick a key most queries include, like user_id or tenant_id, so each query hits exactly one shard.
Avoid hot shards
Sharding by date or by one big customer can pile traffic onto a single shard. Spread the load evenly.
Cross-shard work hurts
Joins and transactions across shards are slow and complex. Design so most work stays inside one shard.
Resharding is hard
Going from 3 to 4 shards with % moves most rows. Consistent hashing or many small logical shards help.
See it in code
Walk through the code
1import { Pool } from "pg";2 3const shards = [4 new Pool({ connectionString: process.env.SHARD_0_URL }),5 new Pool({ connectionString: process.env.SHARD_1_URL }),6 new Pool({ connectionString: process.env.SHARD_2_URL }),7];8 9function shardFor(userId: number) {10 return shards[userId % shards.length];11}12 13export function getOrders(userId: number) {14 return shardFor(userId).query("SELECT * FROM orders WHERE user_id = $1", [userId]);15}1/3Three separate databases, each holding the same tables but different rows.
This is application-level sharding. Tools like Citus or Vitess, or databases with built-in sharding, move this routing out of your code.
Save yourself the pain
Common mistakes
Oops
Sharding on day one 'for scale'.
Do this instead
It adds huge complexity. Indexes, caching, bigger machines and replicas carry most apps a very long way first.
Oops
Using created_at as the shard key.
Do this instead
All new writes then hit the newest shard while the others sit idle. Pick a key that spreads writes.
Your mission
Shard by user
Quick check
Almost all your queries filter by tenant_id. Which shard key fits best?
Go deeper
- 1Design a sharding key for a hypothetical multi-tenant app, e.g. shard by customer ID.
- 2Learn why resharding an already-live system is one of the hardest operations in backend engineering.
- 3Understand sharding solves a different problem than replication — data volume, not just read throughput.
More topics at this stop
 Scalability Basics
 Vertical vs Horizontal Scaling
 Load Balancing
 Database Replication
 CAP Theorem
 Microservices vs Monolith
 API Gateway
 Service Discovery
 Circuit Breaker Pattern
 Distributed Caching
 Consistent Hashing
 Rate Limiting Algorithms
 Designing a URL Shortener
 Designing a Rate Limiter

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
