Job Queue System
Part of the Backend Developer Roadmap
In short
Sending emails, resizing images, generating PDFs: slow work shouldn't block an API response. Building your own job queue teaches retries, locking and failure handling from the ground up.
Your own background job processing system — practice for queue theory, worker processes, retries and failure handling, built from first principles rather than just using BullMQ.
Think of it like this
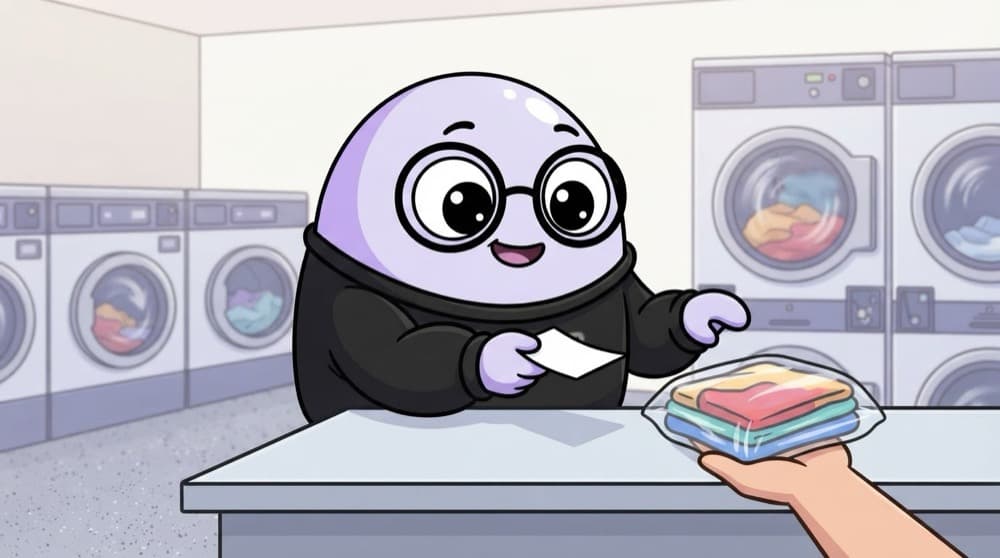
Dropping clothes at the laundry
You hand over your clothes, get a slip, and leave. You don't stand there while they wash. Workers in the back handle bundles in order, rewash anything that comes out dirty, and you collect later with your slip.
Watch it happen
A job that fails once, then succeeds
POST /reports
1/7The client asks for a big report that takes a minute to build.
The big ideas
What you need to know
Safe claiming
Many workers, no duplicates. FOR UPDATE SKIP LOCKED in Postgres or atomic pops in Redis do the job.
Retries with backoff
Retry failures after 2, 4, 8 seconds and so on, up to a max. Then move the job to a dead-letter list.
Idempotent jobs
A job may run twice after a crash. Design jobs so running twice is safe, like checking "already sent?".
Stuck job recovery
If a worker dies mid-job, a timeout puts its running jobs back in the queue.
See it in code
Walk through the code
1-- A worker claims one job. SKIP LOCKED lets many workers run without grabbing the same row.2UPDATE jobs3SET status = 'running', locked_at = now(), attempts = attempts + 14WHERE id = (5 SELECT id FROM jobs6 WHERE status = 'queued' AND run_at <= now()7 ORDER BY run_at8 LIMIT 19 FOR UPDATE SKIP LOCKED10)11RETURNING id, type, payload, attempts;12 13-- On failure: retry later with exponential backoff (2^attempts seconds)14UPDATE jobs SET status = 'queued', run_at = now() + make_interval(secs => power(2, attempts))15WHERE id = $1;1/4Pick the oldest job that is due to run.
This is the core of most Postgres-backed queues. Add an index on (status, run_at) so claiming stays fast as the table grows.
Save yourself the pain
Common mistakes
Oops
Doing slow work inside the HTTP request and hoping it doesn't time out.
Do this instead
Return 202 with a job ID quickly, process in a worker, and let clients poll or get a webhook.
Oops
Retrying forever with no delay.
Do this instead
Use exponential backoff and a max attempt count. A failing job retried instantly can hammer a struggling service.
Your mission
Milestone 1: two workers, no duplicates
Quick check
Why should the API return 202 Accepted for a job it queued?
Go deeper
- 1Implement job scheduling, retries with backoff, and a dead letter queue.
- 2Build a simple dashboard showing job status (pending, running, failed, completed).
- 3Support job priorities so critical jobs process before low-priority ones.
More projects at this stop
 URL Shortener
 Blogging Platform API
 E-commerce Backend
 Rate Limiter Service
 Real-time Chat Backend (WebSocket)
 Authentication Microservice
 Payment Integration Backend (Stripe)
 Multi-tenant SaaS API
 File Storage Service (S3-like)
 Notification Service (Email/SMS/Push)
 API Gateway for Microservices
 Video Streaming Backend
 Social Media Backend (Feed, Comments, Likes)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
