Handling Imbalanced Data
Part of the Data Science Roadmap
In short
When only 1 in 100 cases is the thing you care about, like fraud or a rare disease, a model can look 99% accurate while catching nothing. Here's how to spot and fix that.
When one class vastly outnumbers another (e.g. 1% fraud cases) — plain accuracy becomes meaningless, and techniques like resampling, class weighting, or better metrics become necessary.
Think of it like this
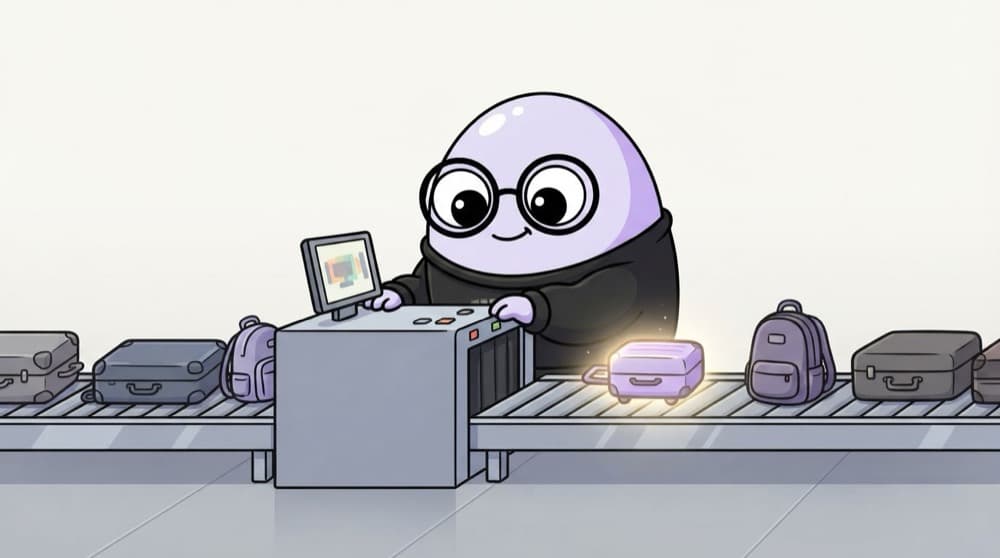
The airport security guard
Almost every bag at security is harmless. A guard who waves every bag through would be right 99.99% of the time, and completely useless. What matters is how many dangerous bags he catches, and how many innocent bags he stops.
Watch it happen
1,000 payments, 10 of them fraud
1/5A heavily imbalanced dataset. The rare class is the one you actually care about.
The big ideas
What you need to know
Use better metrics
Precision, recall, F1 and precision-recall AUC tell the truth that accuracy hides.
Class weights
Make mistakes on the rare class cost more during training. Many sklearn models accept class_weight.
Resampling
Oversample the rare class or undersample the common one, but only inside the training data.
Tune the threshold
The default 0.5 cut-off is rarely best. Pick it based on what misses and false alarms cost.
See it in code
Walk through the code
1from sklearn.datasets import make_classification2from sklearn.model_selection import train_test_split3from sklearn.linear_model import LogisticRegression4from sklearn.metrics import classification_report5 6X, y = make_classification(n_samples=20_000, weights=[0.99], random_state=0)7X_tr, X_te, y_tr, y_te = train_test_split(X, y, stratify=y, random_state=0)8 9model = LogisticRegression(class_weight="balanced", max_iter=1000)10model.fit(X_tr, y_tr)11print(classification_report(y_te, model.predict(X_te), digits=3))1/4Make a dataset where about 99% of rows are class 0.
A fake dataset with about 1% positives, a stratified split and class weights. Read the recall row for class 1.
Save yourself the pain
Common mistakes
Oops
Oversampling before splitting into train and test.
Do this instead
Split first, then resample only the training set. Otherwise copies of test rows leak into training.
Oops
Reporting 99% accuracy on a 1% fraud problem.
Do this instead
Report recall and precision for the rare class, and the trade-off you chose.
Your mission
Beat the lazy model
Quick check
A disease affects 2% of patients. Your model has 98% accuracy. What should you check first?
Go deeper
- 1Find a public imbalanced dataset (fraud, churn) and check the class distribution.
- 2Learn why a model predicting 'always no fraud' can still show 99% accuracy.
- 3Research oversampling (SMOTE), undersampling, and class-weighting as mitigation strategies.
More topics at this stop
 EDA Process & Techniques
 Handling Missing Data
 Outlier Detection & Treatment
 Feature Scaling (Normalization / Standardization)
 Encoding Categorical Variables
 Feature Creation & Selection
 Dimensionality Reduction (PCA Overview)
 Correlation Analysis

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
