Correlation Analysis
Part of the Data Science Roadmap
In short
Correlation tells you which columns move together, which is great for spotting patterns and repeated features. It also tricks smart people into seeing causes that aren't there.
Measuring how strongly two variables move together — used both to understand a dataset and to catch multicollinearity (highly correlated features) that can destabilize some models.
Think of it like this
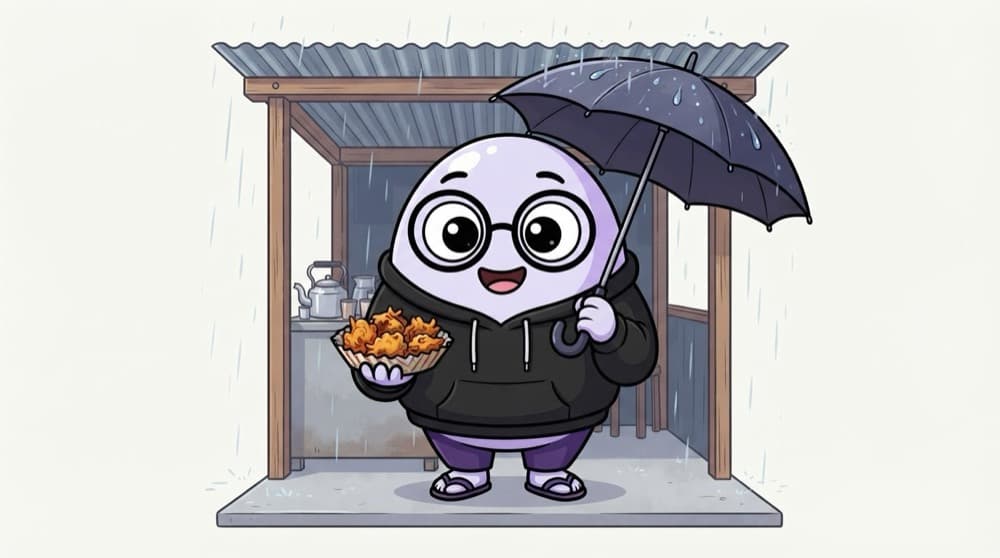
Umbrellas and pakoras
In the monsoon, umbrella sales and pakora sales both shoot up together. Buying umbrellas doesn't make anyone hungry for pakoras. Rain drives both. Correlation spots that they move together; it can't tell you why.
Watch it happen
Two ways to measure 'moving together'
Pearson
- Measures straight-line relationships
- Sensitive to outliers
- Best for roughly normal numbers
Spearman
- Uses ranks, not raw values
- Catches steady curved trends
- Less affected by outliers
Start with Pearson, check Spearman when data is skewed or curved, and always look at the scatter plot too.
The big ideas
What you need to know
From −1 to +1
+1 means they rise together perfectly, −1 means one falls as the other rises, 0 means no straight-line link.
Correlation isn't causation
A hidden third factor, like rain, can drive both. Proving cause needs experiments or causal methods.
Spot repeated features
Two features with very high correlation carry similar information. Keeping both can confuse linear models.
Always plot it
A correlation near 0 can hide a strong U-shape. Scatter plots catch what one number misses.
See it in code
Walk through the code
1import pandas as pd2 3df = pd.read_csv("city_weather_sales.csv") # rain_mm, umbrellas, pakoras, temp_c4 5print(df.corr(method="pearson", numeric_only=True).round(2))6print(df.corr(method="spearman", numeric_only=True).round(2))7 8r = df["umbrellas"].corr(df["pakoras"])9print(f"umbrellas vs pakoras: r = {r:.2f}") # high, but rain drives both1/3Daily rainfall, temperature, and umbrella and pakora sales for one city.
Compare Pearson and Spearman tables side by side. Big differences hint at outliers or curved relationships.
Save yourself the pain
Common mistakes
Oops
Claiming 'more umbrellas cause more pakora sales' from a high r.
Do this instead
Look for a common driver first, like rain. Say 'are associated with', not 'cause'.
Oops
Concluding 'no relationship' because r is near 0.
Do this instead
Plot the data. A U-shaped or seasonal pattern can have near-zero correlation.
Your mission
Find a hidden driver
Quick check
Two features have a correlation of 0.97. What's a sensible step for a linear regression model?
Go deeper
- 1Build a correlation heatmap for a sample dataset's numeric features.
- 2Learn why highly correlated features can cause issues specifically for linear models.
- 3Remember: correlation analysis reveals association, never causation on its own.
More topics at this stop
 EDA Process & Techniques
 Handling Missing Data
 Outlier Detection & Treatment
 Feature Scaling (Normalization / Standardization)
 Encoding Categorical Variables
 Feature Creation & Selection
 Dimensionality Reduction (PCA Overview)
 Handling Imbalanced Data

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
