Handling Missing Data
Part of the Data Science Roadmap
In short
Blank cells are everywhere, and how you treat them changes your answer. Drop them, fill them or flag them, the right choice depends on why the data went missing.
Deciding whether to drop, impute, or flag missing values — the right choice depends on why the data is missing and how a model would react to each option, not a single universal rule.
Think of it like this
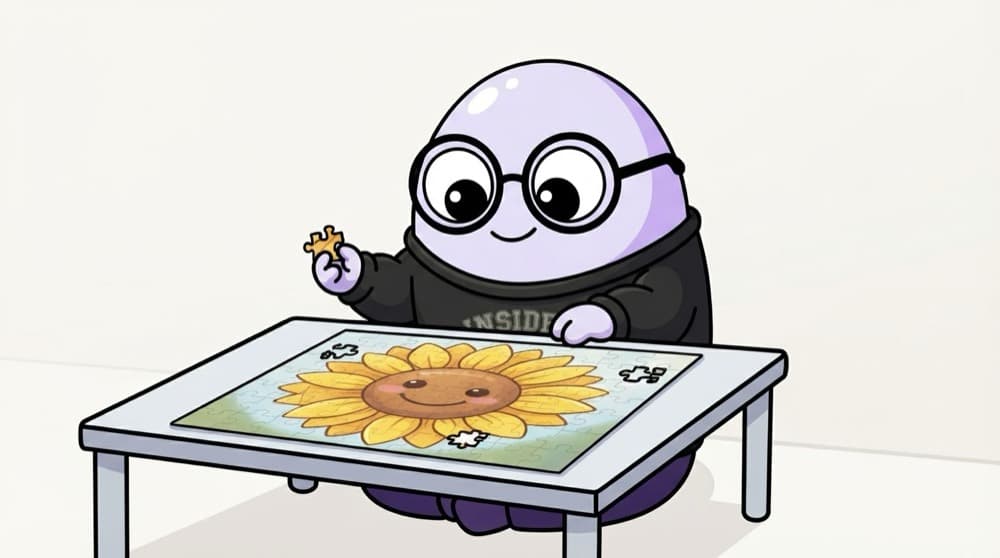
The jigsaw with missing pieces
A puzzle with three pieces missing still shows the picture. You can leave gaps, guess the colour from neighbours, or note 'pieces lost'. But if all the missing pieces came from the sky, guessing blue is reasonable. Why they're missing decides what's safe.
Watch it happen
Three ways to treat missing ages
1/4Seven customers. Two ages are missing, shown as NaN, which means 'not a number'.
The big ideas
What you need to know
Ask why it's missing
Random gaps are easier. If rich customers skip the income question, filling with the average biases results.
Dropping
Simple and honest when few rows are affected. Dangerous when it removes a whole group.
Filling (imputation)
Median for skewed numbers, mode or 'Unknown' for categories, forward-fill for time series.
Flag what you filled
An indicator column keeps the information that a value was originally missing.
See it in code
Walk through the code
1print(df.isna().sum())2 3df = df.dropna(subset=["order_id", "amount"])4 5df["age_missing"] = df["age"].isna()6df["age"] = df["age"].fillna(df["age"].median())7 8df["city"] = df["city"].fillna("Unknown")9 10df = df.sort_values("date")11df["stock"] = df["stock"].ffill()1/4Always count blanks per column first.
Different columns, different treatments. Required fields drop, numbers get median plus a flag, categories get 'Unknown'.
Save yourself the pain
Common mistakes
Oops
Filling every blank with 0.
Do this instead
0 is a real value. A missing price is not a free product. Use NaN, a median or an explicit flag.
Oops
Dropping all rows with any blank and not checking who disappeared.
Do this instead
Compare the dropped rows to the kept ones. If one region vanishes, your results are skewed.
Your mission
Same data, three answers
Quick check
Income is missing mostly for high earners who skipped the question. What's risky about filling with the overall average?
Go deeper
- 1Learn the difference between data missing at random versus missing systematically.
- 2Practice both dropping and imputing (mean/median/mode) missing values on the same dataset.
- 3Learn how tree-based models handle missing values differently from linear models.
More topics at this stop
 EDA Process & Techniques
 Outlier Detection & Treatment
 Feature Scaling (Normalization / Standardization)
 Encoding Categorical Variables
 Feature Creation & Selection
 Dimensionality Reduction (PCA Overview)
 Handling Imbalanced Data
 Correlation Analysis

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
