
Classification Metrics (Accuracy, Precision, Recall, F1)
Part of the Data Science Roadmap
In short
A fraud model that never flags anything can still score 99% accuracy. Picking the right metric is how you stop a useless model from looking like a topper.
Accuracy alone is misleading on imbalanced data — precision measures how many predicted positives were correct, recall measures how many actual positives were caught, and F1 balances both.
Think of it like this
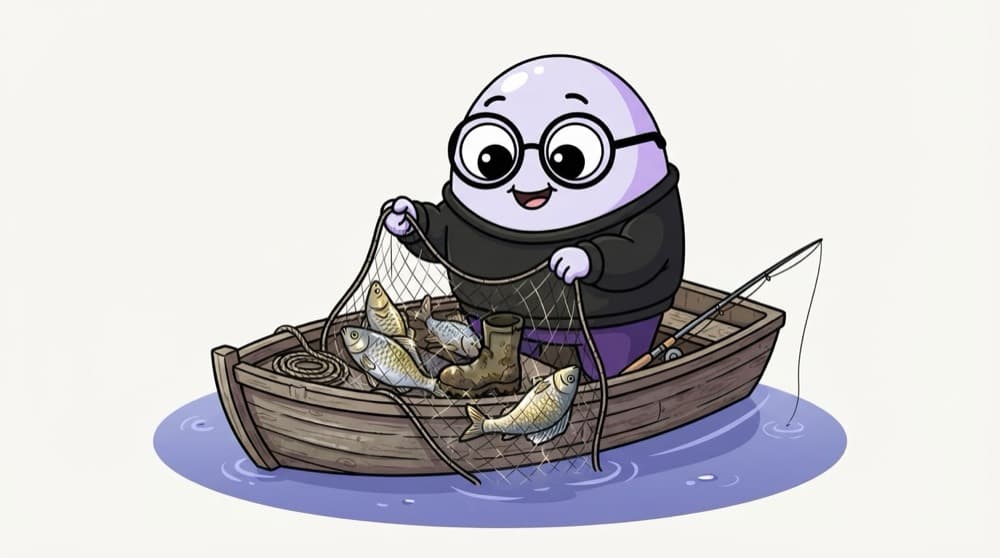
Fishing with a net
You cast a net into a pond. Recall asks: of all the fish in the pond, how many did you catch? Precision asks: of everything in your net, how much is actually fish and not old boots? A huge net catches every fish, plus a lot of junk.
Watch it happen
Ten predictions from a fraud model
1/5Each cell is one transaction. TP = fraud caught, FN = fraud missed, FP = false alarm, TN = normal and left alone.
The big ideas
What you need to know
Accuracy lies on imbalance
If 99% of rows are normal, predicting 'normal' every time gets 99% accuracy and catches zero fraud.
Precision: trust your flags
High precision means few false alarms. Matters when acting on a flag is costly, like blocking a customer's card.
Recall: miss nothing
High recall means few misses. Matters when missing a case is dangerous, like a cancer screening test.
F1 balances both
F1 stays low if either precision or recall is low. A handy single number for imbalanced classes.
See it in code
Walk through the code
1from sklearn.metrics import accuracy_score, precision_score, recall_score, f1_score2 3y_true = [1, 0, 1, 1, 0, 0, 1, 0, 0, 0] # 1 = fraud4y_pred = [1, 0, 0, 1, 0, 1, 1, 0, 0, 0]5 6print("accuracy ", accuracy_score(y_true, y_pred))7print("precision", precision_score(y_true, y_pred))8print("recall ", recall_score(y_true, y_pred))9print("f1 ", f1_score(y_true, y_pred))1/4Real answers and model guesses. Label 1 is the positive class, fraud.
The same ten predictions as the scene. Accuracy prints 0.8, and the other three print 0.75.
Save yourself the pain
Common mistakes
Oops
Reporting only accuracy on a dataset where one class is rare.
Do this instead
Report precision, recall and F1 for the rare class, and say how imbalanced the data is.
Oops
Chasing a higher F1 without asking which error costs more.
Do this instead
Talk to the business first. A missed fraud and a false alarm rarely cost the same.
Your mission
Break accuracy on purpose
Quick check
A hospital screening model must miss as few sick patients as possible. Which metric matters most?
Go deeper
- 1Calculate all 4 metrics by hand on a small confusion matrix example.
- 2Learn a scenario where you'd prioritize recall over precision (e.g. cancer screening) and vice versa.
- 3Practice choosing the right metric for a given business problem before training a model.
More topics at this stop
 Confusion Matrix
 ROC-AUC Curve
 Regression Metrics (MAE, RMSE, R²)
 Hyperparameter Tuning (Grid / Random Search)
 Regularization (L1 / L2)
 Ensemble Methods
 Model Selection Strategy

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
