Model Selection Strategy
Part of the Data Science Roadmap
In short
There are dozens of algorithms you could try. A clear strategy stops you testing random models until one looks lucky, and gives you a choice you can defend.
Choosing the final model isn't just picking the highest metric — interpretability needs, training/inference speed, and maintenance complexity all matter for a real production decision.
Think of it like this
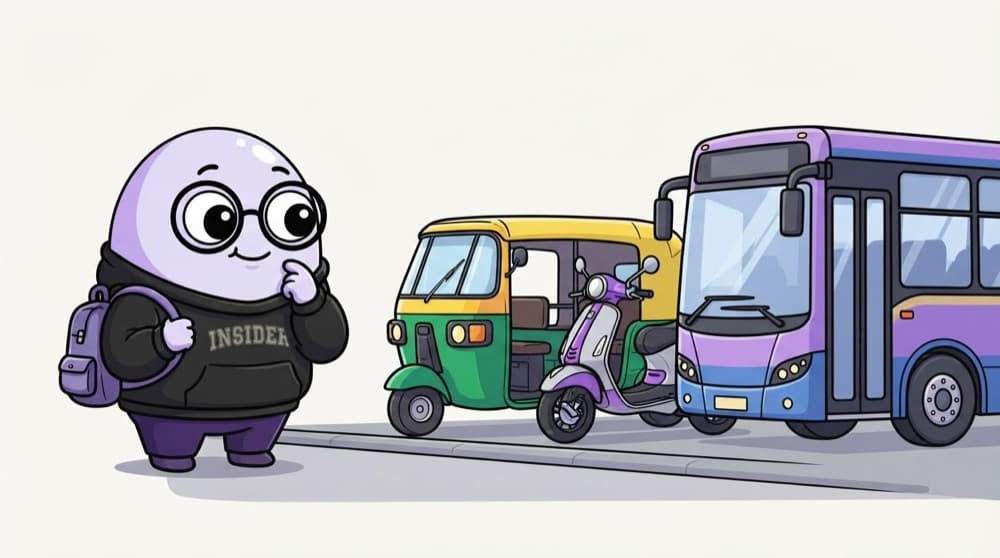
Choosing how to get there
For a 2 km trip you take an auto. For a cross-city trip with luggage, maybe a cab. For a daily commute, the bus pass wins. You don't pick the fanciest vehicle, you pick the one that fits distance, budget and comfort. Models are the same.
Watch it happen
A sane order for picking a model
1/5Start with a dumb baseline, like 'always predict the majority class'. Anything you build must beat it.
The big ideas
What you need to know
Agree the metric first
Decide F1, recall or RMSE before comparing models. Changing the metric after seeing results is cheating yourself.
Same folds for everyone
Score every candidate on identical cross-validation splits so the comparison is fair.
Simpler wins ties
If two models score about the same, choose the faster, easier-to-explain one.
Think about production
Prediction speed, memory and retraining cost count too. A model that's slightly better but ten times slower may lose.
See it in code
Walk through the code
1from sklearn.datasets import load_breast_cancer2from sklearn.dummy import DummyClassifier3from sklearn.ensemble import RandomForestClassifier4from sklearn.linear_model import LogisticRegression5from sklearn.model_selection import cross_val_score6from sklearn.pipeline import make_pipeline7from sklearn.preprocessing import StandardScaler8 9X, y = load_breast_cancer(return_X_y=True)10candidates = {11 "baseline": DummyClassifier(strategy="most_frequent"),12 "logistic": make_pipeline(StandardScaler(), LogisticRegression()),13 "forest": RandomForestClassifier(random_state=0),14}15for name, model in candidates.items():16 print(name, cross_val_score(model, X, y, cv=5, scoring="f1").mean().round(3))1/3The baseline always predicts the most common class. It sets the floor.
Baseline, simple and stronger candidates, all judged on the same metric and the same 5 folds.
Save yourself the pain
Common mistakes
Oops
Jumping straight to deep learning or XGBoost without a baseline.
Do this instead
Always build a baseline and a simple model first. They show whether the fancy model is worth its cost.
Oops
Choosing the model with the highest score by 0.001.
Do this instead
Look at the spread across folds. Differences smaller than the spread are mostly noise.
Your mission
Run a mini model bake-off
Quick check
Why build a DummyClassifier baseline before trying real models?
Go deeper
- 1List the trade-offs (accuracy, speed, interpretability) for 3 models you've trained.
- 2Practice justifying a model choice that isn't simply 'the one with the highest score'.
- 3Learn when a simpler, more interpretable model is the right business choice, even if slightly less accurate.
More topics at this stop
 Classification Metrics (Accuracy, Precision, Recall, F1)
 Confusion Matrix
 ROC-AUC Curve
 Regression Metrics (MAE, RMSE, R²)
 Hyperparameter Tuning (Grid / Random Search)
 Regularization (L1 / L2)
 Ensemble Methods

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
