
Hyperparameter Tuning (Grid / Random Search)
Part of the Data Science Roadmap
In short
Tree depth, learning rate, number of neighbours: these settings aren't learned from data, you choose them. Tuning is the organised way to find good values instead of guessing.
Systematically searching for the best model settings — grid search tries every combination in a defined range, random search samples combinations randomly, often nearly as effective and much faster.
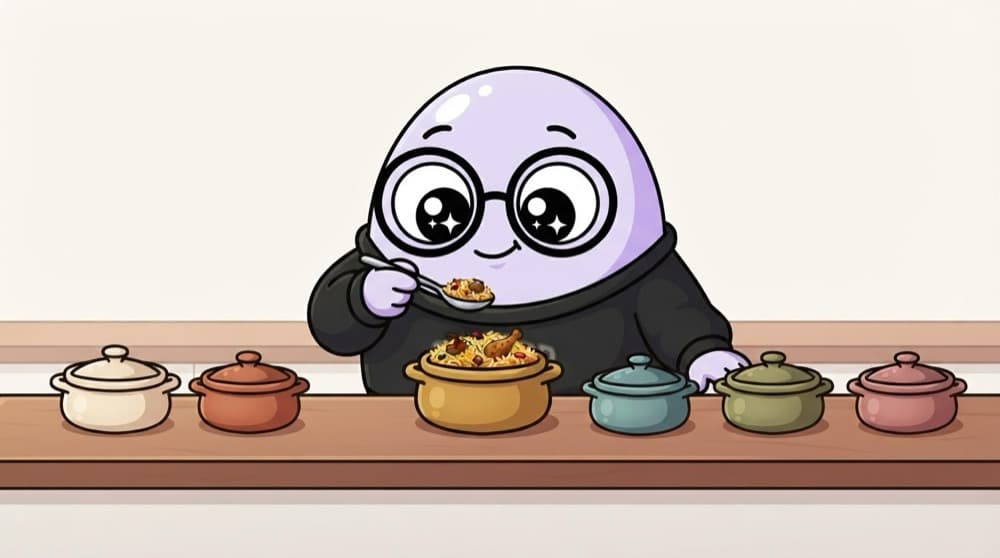
Think of it like this
Perfecting the biryani
You want the best biryani. Rice soaking time and dum time are your knobs. Grid search cooks every combination on your list. Random search cooks a few random combinations from a wider range. Either way, a panel of friends tastes each pot fairly before you pick.
Watch it happen
Two ways to search
Grid search
- Tries every combination you list
- Cost grows fast with each parameter
- Good for 2 or 3 small lists
Random search
- Samples combinations from ranges
- You fix the budget with n_iter
- Covers wide ranges more cheaply
Use grid search for a small, known set of values. Use random search when you have many parameters or wide ranges.
The big ideas
What you need to know
Parameters vs hyperparameters
Weights are learned during fit. Hyperparameters, like max_depth, are set by you before training starts.
Score with cross-validation
Each candidate is scored on several folds of training data, so one lucky split doesn't fool you.
Keep the test set out
Tune only on training data. Touch the test set once, after tuning is finished.
Budget matters
3 values for 4 parameters with 5 folds is 405 fits. Random search lets you cap that.
How it works
What the search does for each candidate
- 1
Pick settings
Take the next combination from the grid, or sample one at random.
- 2
Cross-validate
Train on k-1 folds, score on the held-out fold, repeat k times.
- 3
Average the score
Store the mean score for this combination.
- 4
Refit the winner
After all candidates, refit the best settings on all training data.
See it in code
Walk through the code
1from scipy.stats import randint2from sklearn.datasets import load_breast_cancer3from sklearn.ensemble import RandomForestClassifier4from sklearn.model_selection import GridSearchCV, RandomizedSearchCV5 6X, y = load_breast_cancer(return_X_y=True)7rf = RandomForestClassifier(random_state=0)8 9grid = GridSearchCV(rf, {"max_depth": [3, 5, None], "n_estimators": [100, 300]}, cv=5)10grid.fit(X, y)11 12rand = RandomizedSearchCV(rf, {"max_depth": randint(2, 20), "n_estimators": randint(50, 500)},13 n_iter=10, cv=5, random_state=0)14rand.fit(X, y)15print(grid.best_params_, rand.best_params_)1/3Grid: 3 depths times 2 sizes = 6 combinations, each fitted 5 times.
Both searches cross-validate every candidate. In a real project, run them on the training split only.
Save yourself the pain
Common mistakes
Oops
Tuning against the test set and then reporting that same test score.
Do this instead
Tune with cross-validation on training data. The test score is only honest if it never guided a choice.
Oops
Building a giant grid with six parameters and ten values each.
Do this instead
Start with random search over wide ranges, then try a small grid around the best region.
Your mission
Grid vs random on a budget
Quick check
Why does GridSearchCV use cross-validation for each candidate?
Go deeper
- 1Run a grid search over 2-3 hyperparameters for a model you've trained.
- 2Compare grid search results to a random search over the same range.
- 3Learn why tuning must always be validated on held-out data, never the training set.
More topics at this stop
 Classification Metrics (Accuracy, Precision, Recall, F1)
 Confusion Matrix
 ROC-AUC Curve
 Regression Metrics (MAE, RMSE, R²)
 Regularization (L1 / L2)
 Ensemble Methods
 Model Selection Strategy

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
