In short
K-Means forces every point into a group. DBSCAN finds crowded regions of any shape and is happy to say 'this point belongs nowhere', which is perfect for messy real data.
A density-based clustering algorithm that finds clusters of arbitrary shape and automatically identifies outliers as noise — unlike K-Means, it doesn't require specifying the number of clusters upfront.
Think of it like this
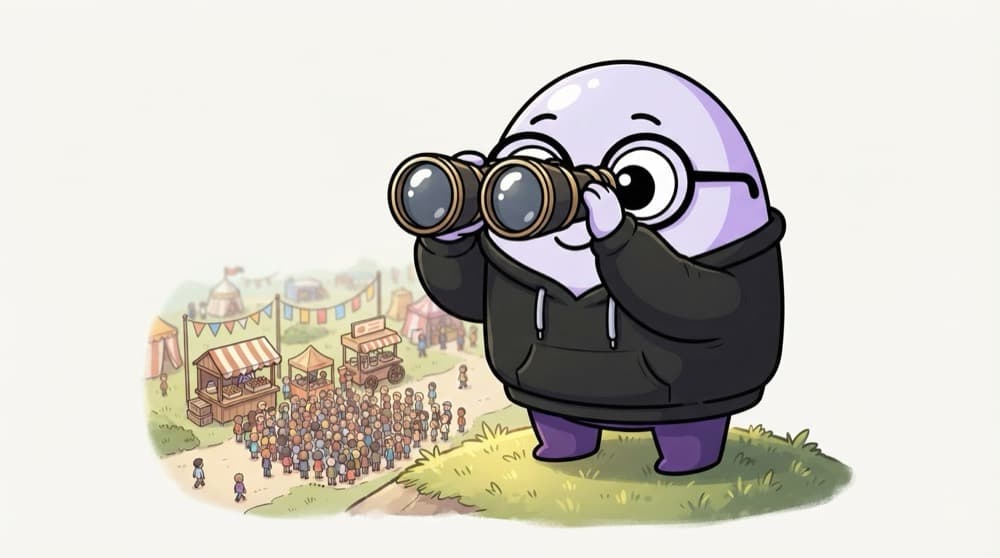
Crowds at the village mela
From a hill you watch a mela. Tight crowds form around the food stalls and the giant wheel. Those crowds are clusters, whatever their shape. A few people wander alone near the parking. They aren't part of any crowd, so DBSCAN calls them noise.
Watch it happen
How DBSCAN labels each point
1/5Pick eps, the neighbourhood radius, and min_samples, how many neighbours make a crowd.
The big ideas
What you need to know
Any shape works
DBSCAN follows dense regions, so it finds curved, stretched or ring-like clusters that confuse K-Means.
No k needed
The number of clusters comes out of the data. You tune eps and min_samples instead.
Noise is a feature
Points labelled -1 are not forced into a group. That makes DBSCAN useful for spotting outliers too.
Uneven density hurts
One eps can't fit both a packed cluster and a sparse one. HDBSCAN handles mixed densities better.
See it in code
Walk through the code
1from sklearn.cluster import DBSCAN2from sklearn.datasets import make_moons3from sklearn.preprocessing import StandardScaler4 5X, _ = make_moons(n_samples=300, noise=0.06, random_state=0)6X = StandardScaler().fit_transform(X)7 8db = DBSCAN(eps=0.3, min_samples=5).fit(X)9labels = db.labels_10print("clusters:", len(set(labels)) - (1 if -1 in labels else 0))11print("noise points:", (labels == -1).sum())1/3Make two curved clusters and scale them so eps means the same in both directions.
Two interlocking half-moons: a shape K-Means splits badly. DBSCAN follows each curve.
Save yourself the pain
Common mistakes
Oops
Guessing eps randomly and giving up when everything becomes noise.
Do this instead
Plot each point's distance to its k-th nearest neighbour, sorted. The bend in that curve is a good eps.
Oops
Using DBSCAN on unscaled data with mixed units.
Do this instead
Scale features first. eps is one radius for all directions.
Your mission
K-Means vs DBSCAN on moons
Quick check
What does a DBSCAN label of -1 mean?
Go deeper
- 1Run DBSCAN on a dataset with non-spherical cluster shapes and compare to K-Means.
- 2Learn its two key parameters: epsilon (neighborhood radius) and minimum samples.
- 3Understand why DBSCAN naturally handles outliers, unlike K-Means.
More topics at this stop
 K-Means Clustering
 Hierarchical Clustering
 Principal Component Analysis (PCA)
 Anomaly Detection
 Association Rule Mining (Market Basket Analysis)
 Dimensionality Reduction (t-SNE, UMAP Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
