In short
Sometimes you don't know how many groups you want. Hierarchical clustering builds a whole family tree of groupings, and you choose where to cut it.
A clustering method that builds a tree of nested clusters (a dendrogram) rather than requiring you to pick K upfront — useful for exploring data structure at multiple levels of granularity.
Think of it like this
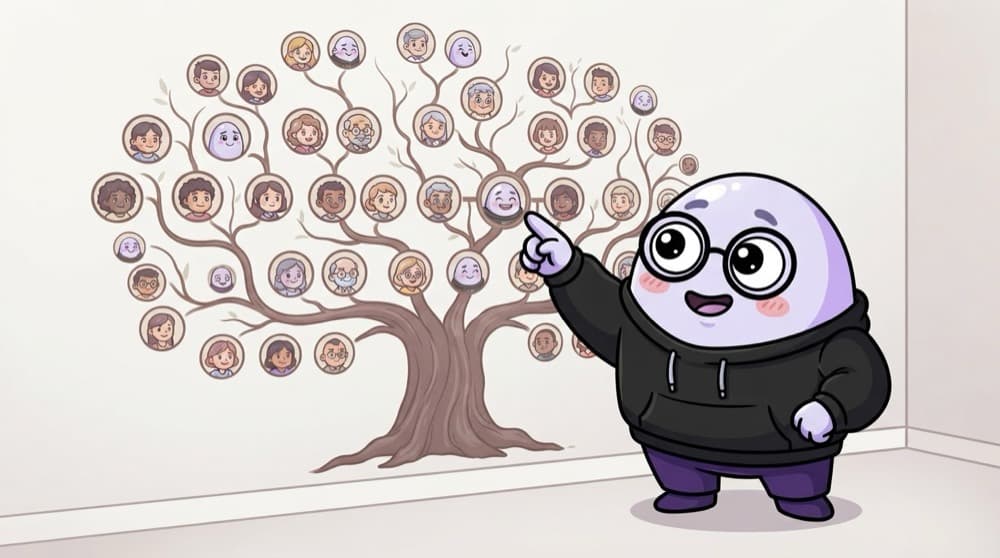
The joint family tree
Siblings are the closest pairs. Siblings join their cousins to form a family branch. Branches join into the whole clan. Cut the tree near the bottom and you get many small families. Cut near the top and you get two big sides of the clan.
Watch it happen
Merging five customers bottom-up
1/5Start with every customer as its own tiny cluster.
The big ideas
What you need to know
Bottom-up merging
Agglomerative clustering starts with single points and keeps merging the two closest clusters until one remains.
Linkage decides 'closest'
Single, complete, average and Ward linkage measure cluster distance differently, and can give different trees.
Cut the dendrogram
The tree diagram is called a dendrogram. A horizontal cut at some height gives you the clusters.
Slow on big data
It compares many pairs of points, so it gets slow beyond tens of thousands of rows. Sample first.
See it in code
Walk through the code
1import numpy as np2from scipy.cluster.hierarchy import dendrogram, fcluster, linkage3import matplotlib.pyplot as plt4 5X = np.array([[1, 2], [1.2, 2.1], [5, 6], [5.1, 6.2], [9, 1]])6Z = linkage(X, method="average")7 8dendrogram(Z, labels=["A", "B", "C", "D", "E"])9plt.show()10 11print(fcluster(Z, t=3, criterion="maxclust")) # cut into 3 clusters1/4Five customers, each with two features.
The same five customers as the scene. Cutting into 3 clusters gives A B, C D and E on their own.
Save yourself the pain
Common mistakes
Oops
Using Ward or average linkage without scaling features first.
Do this instead
Scale features so one large-unit column doesn't decide every merge.
Oops
Running it on a million rows and waiting forever.
Do this instead
Sample a few thousand rows, or use K-Means or MiniBatchKMeans for very large data.
Your mission
Draw a country dendrogram
Quick check
In agglomerative clustering, what is at the very bottom of the dendrogram?
Go deeper
- 1Build a dendrogram for a small sample dataset and interpret its structure.
- 2Learn the difference between agglomerative (bottom-up) and divisive (top-down) approaches.
- 3Compare its output to K-Means on the same dataset.
More topics at this stop
 K-Means Clustering
 DBSCAN
 Principal Component Analysis (PCA)
 Anomaly Detection
 Association Rule Mining (Market Basket Analysis)
 Dimensionality Reduction (t-SNE, UMAP Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
