Horizontal Pod Autoscaling
Part of the DevOps Roadmap
In short
Traffic doubles every evening when people order dinner, then drops at midnight. Paying for peak capacity all day is wasteful; the Horizontal Pod Autoscaler adds pods when busy and removes them when quiet.
Automatically increasing or decreasing the number of running Pod replicas based on observed metrics like CPU or memory usage — a core mechanism for handling variable traffic without manual intervention.
Think of it like this
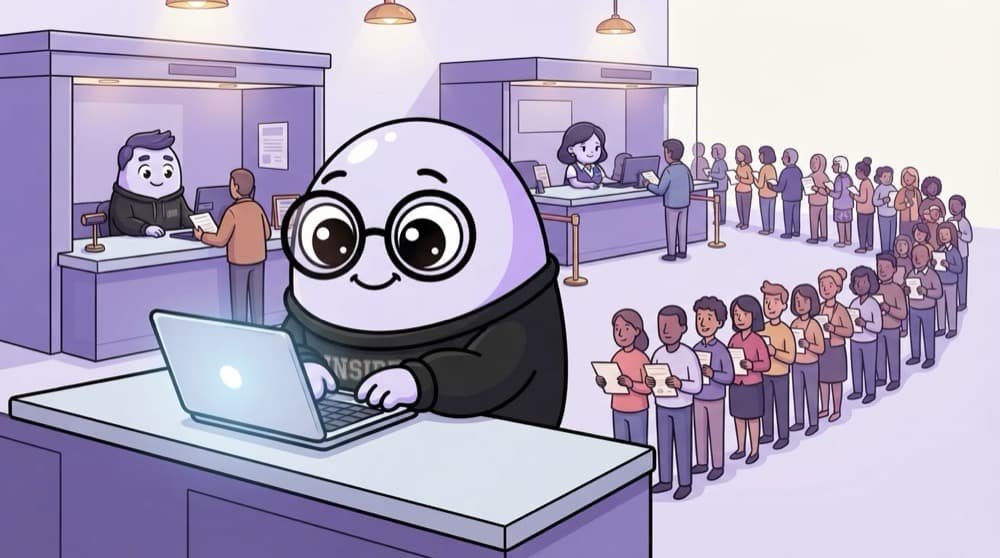
Extra counters at the bank
On salary day the bank queue stretches out the door, so the manager opens more counters. By afternoon, it's quiet and those staff go back to other work. The HPA is that manager, watching the queue (CPU or requests) and opening or closing counters (pods).
Watch it happen
Replicas through an evening rush
1/56 pm. Two pods, average CPU 40% against a 70% target. The HPA leaves things alone.
The big ideas
What you need to know
Target, not threshold
You set a target like 70% CPU. The HPA calculates how many pods would bring the average back to it.
Requests are required
CPU utilisation is measured against each container's CPU request. No requests set, no percentage to scale on.
Metrics come from somewhere
Install metrics-server for CPU and memory. Custom metrics, like queue length, need an adapter or a tool like KEDA.
Scale down slowly
The HPA waits before removing pods, so a short dip doesn't cause flapping up and down.
See it in code
Walk through the code
1apiVersion: autoscaling/v22kind: HorizontalPodAutoscaler3metadata: { name: web }4spec:5 scaleTargetRef: { apiVersion: apps/v1, kind: Deployment, name: web }6 minReplicas: 27 maxReplicas: 108 metrics:9 - type: Resource10 resource:11 name: cpu12 target: { type: Utilization, averageUtilization: 70 }1/3This HPA controls the replica count of the web Deployment.
Watch it work with kubectl get hpa web -w while you generate load. The TARGETS column shows current versus target utilisation.
Save yourself the pain
Common mistakes
Oops
Creating an HPA for pods with no CPU requests and seeing <unknown> forever.
Do this instead
Set resources.requests.cpu on the containers, and make sure metrics-server is installed and healthy.
Oops
Setting maxReplicas very high and assuming the cluster will cope.
Do this instead
Pods need nodes. Pair the HPA with a cluster autoscaler, and pick a max your budget and database can handle.
Your mission
Make it scale
Quick check
An HPA targets 50% CPU. Three pods are averaging 100%. Roughly how many replicas will it ask for?
Go deeper
- 1Set up a Horizontal Pod Autoscaler on a Deployment targeting CPU utilization.
- 2Simulate load and observe the autoscaler adding replicas in response.
- 3Learn why autoscaling requires resource requests/limits to be set correctly to work well.
More topics at this stop
 Kubernetes Architecture
 Pods, Deployments & Services
 ConfigMaps & Secrets
 Kubernetes Networking
 Ingress Controllers
 Persistent Volumes & Storage
 Helm Charts
 Namespaces & RBAC
 Kubernetes Operators (Overview)
 Kubectl Essentials
 Troubleshooting Kubernetes

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
