Persistent Volumes & Storage
Part of the DevOps Roadmap
In short
Pods are disposable, but your database's data is not. Persistent Volumes give pods real disks that outlive restarts and rescheduling, without each app needing to know where the disk lives.
Kubernetes' abstraction for durable storage that survives Pod restarts — PersistentVolumes represent actual storage, PersistentVolumeClaims are how a Pod requests it.
Think of it like this
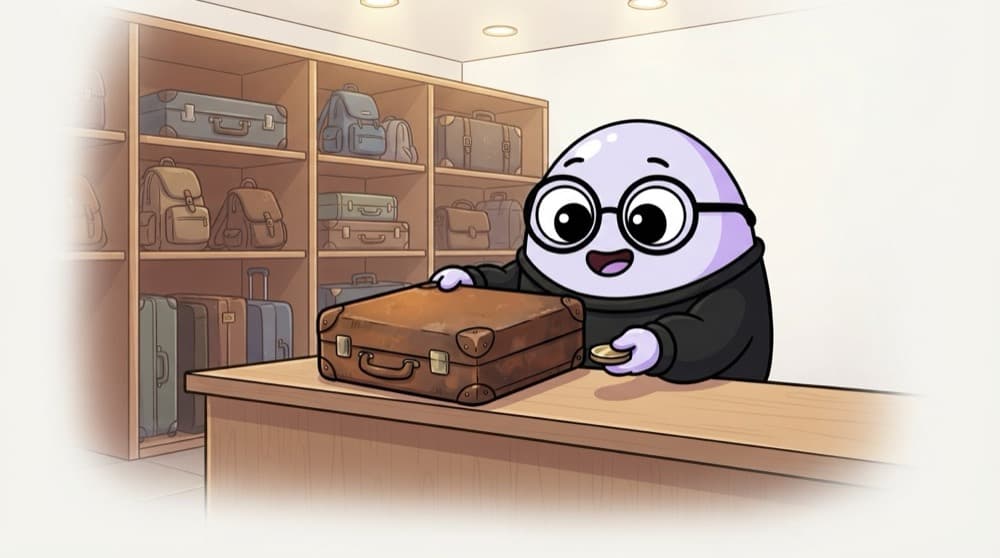
The station cloak room
At the railway cloak room you hand over your bag and get a token. You don't care which shelf it sits on. Come back days later with the token and your bag is there. A PersistentVolumeClaim is the token; the PersistentVolume is the shelf holding your data.
Watch it happen
Claiming a disk with a PVC
use claim data
1/5The pod spec only names a claim. It has no idea which cloud or disk type sits behind it.
The big ideas
What you need to know
PV is the disk
A PersistentVolume represents real storage: a cloud disk, an NFS share or a local SSD.
PVC is the request
A PersistentVolumeClaim asks for a size and access mode. Pods use claims, never disks directly.
StorageClass automates it
With dynamic provisioning, a claim creates its own disk on demand. Most managed clusters have a default class.
StatefulSets for databases
StatefulSets give each replica its own claim and a stable name, which databases usually need.
See it in code
Walk through the code
1apiVersion: v12kind: PersistentVolumeClaim3metadata: { name: app-data }4spec:5 accessModes: [ReadWriteOnce]6 resources: { requests: { storage: 5Gi } }7---8# Inside a Pod (or Deployment template) spec:9volumes:10 - name: data11 persistentVolumeClaim: { claimName: app-data }12containers:13 - name: app14 image: myapp:115 volumeMounts: [{ name: data, mountPath: /data }]1/3A claim for 5 GiB that one node at a time can mount read-write. The default StorageClass fills it.
Check the reclaim policy with kubectl get pv. With Delete, removing the claim also deletes the disk and its data.
Save yourself the pain
Common mistakes
Oops
Scaling a Deployment with one ReadWriteOnce claim to three replicas.
Do this instead
Pods on other nodes can't mount it. Use a StatefulSet with a claim per replica, or storage that supports ReadWriteMany.
Oops
Deleting a namespace to 'clean up' without checking the reclaim policy.
Do this instead
With the common Delete policy, the disks go too. Back up first, or set Retain on volumes holding data you care about.
Your mission
Data that survives a pod
Quick check
What does a pod reference to get durable storage?
Go deeper
- 1Create a PersistentVolumeClaim and mount it in a Pod, then verify data survives a Pod restart.
- 2Learn the difference between a PersistentVolume and a PersistentVolumeClaim.
- 3Understand why stateful applications (like databases) need this, while stateless apps often don't.
More topics at this stop
 Kubernetes Architecture
 Pods, Deployments & Services
 ConfigMaps & Secrets
 Kubernetes Networking
 Ingress Controllers
 Helm Charts
 Namespaces & RBAC
 Horizontal Pod Autoscaling
 Kubernetes Operators (Overview)
 Kubectl Essentials
 Troubleshooting Kubernetes

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
