Model Scaling Laws (Overview)
Part of the AI Engineer Roadmap
In short
Why did labs spend so much on ever-bigger models? Because loss kept dropping in a surprisingly predictable way as they added parameters, data and compute. That pattern is called a scaling law.
Empirical relationships showing how model performance improves predictably with more parameters, data and compute — explains why 'bigger models' became the dominant strategy for years.
Think of it like this
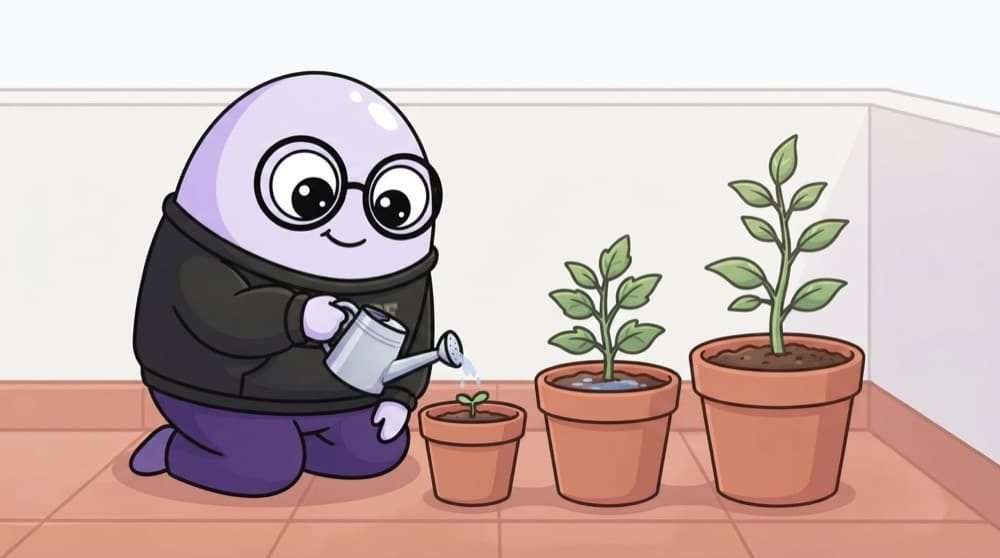
Pot, soil and water together
A bigger pot alone won't grow a bigger plant if you don't add soil and water. Grow all three together and the plant gets taller, steadily. Model size, data and compute behave the same: scale them in balance.
Watch it happen
Loss as compute grows (illustrative)
1/5Each cell is a training run with 10 times more compute than the last.
The big ideas
What you need to know
Power laws
Loss falls as a power law of parameters, data and compute. On log-log charts, the curve looks like a straight line.
Balance size and data
DeepMind's Chinchilla work (2022) showed data should grow along with model size, not lag behind it.
Planning tool
Labs train small models first, fit the curve and predict how a big run will turn out before spending the money.
Loss is not everything
Lower loss doesn't guarantee better results on every task. Data quality, tuning and inference tricks matter too.
See it in code
Walk through the code
1# Rough rules of thumb, not exact laws2params = 8e9 # an 8-billion-parameter model3tokens = 20 * params # Chinchilla-style: ~20 tokens per parameter4flops = 6 * params * tokens # common estimate of training compute5 6print(f"tokens: {tokens:.1e}") # 1.6e+117print(f"FLOPs: {flops:.1e}") # 7.7e+211/3Pick a model size and apply the 20-tokens-per-parameter rule.
Back-of-envelope maths researchers use. Many recent models are trained on far more tokens than this on purpose.
Save yourself the pain
Common mistakes
Oops
Thinking scaling laws mean bigger is always better for your app.
Do this instead
For a product, a smaller model trained on more data is often cheaper to serve and good enough.
Oops
Treating the 20-tokens rule as fixed.
Do this instead
It's about compute-optimal training. Labs often train smaller models on far more tokens so they're cheaper at inference.
Your mission
Plot a fake scaling curve
Quick check
What was the main takeaway of the Chinchilla scaling work?
Go deeper
- 1Read a high-level explainer of the Chinchilla scaling laws.
- 2Understand the practical implication: data and compute must scale together, not just model size.
- 3Learn why scaling laws are now being complemented by other techniques (RAG, agents, reasoning).
More topics at this stop
 LLM Architecture Overview
 Tokenization (BPE, SentencePiece)
 Pretraining vs Fine-tuning
 Context Window & Attention
 Popular LLMs (GPT, Claude, Gemini, Llama)
 Open-Source vs Closed-Source Models
 Emergent Abilities (Overview)
 Multimodal Models (Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
