In short
Behind every chatbot reply is one simple loop: guess the next token, add it, repeat. Once you see that loop clearly, things like streaming, token limits and odd mistakes start making sense.
Most modern LLMs are decoder-only Transformers trained to predict the next token — understanding this end-to-end demystifies what's actually happening behind ChatGPT/Claude-style products.
Think of it like this
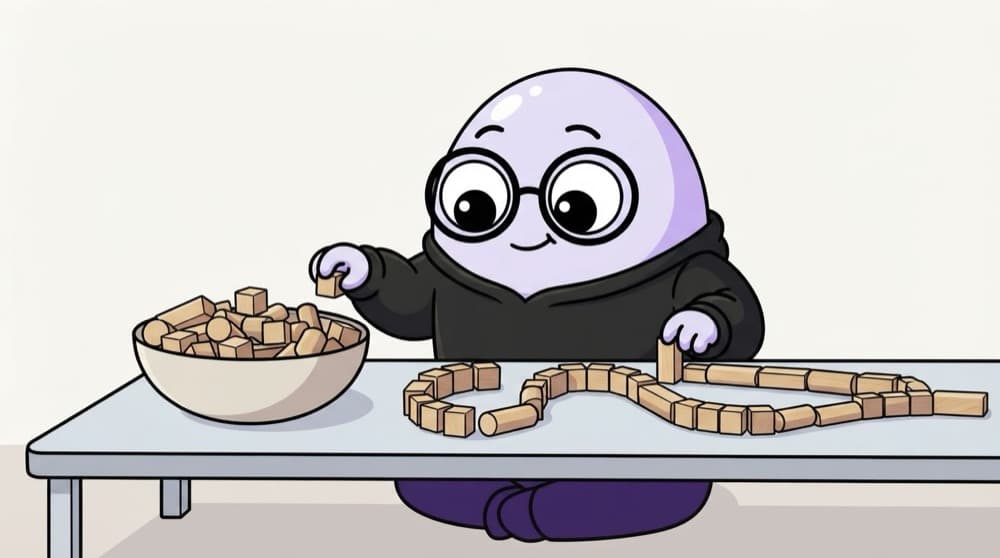
Building a sentence block by block
Imagine laying a row of word blocks, one at a time. Before each block, you look at the whole row so far and pick the block that fits best. You never plan the full sentence first. An LLM writes exactly like this, one token per step.
Watch it happen
One step of next-token prediction
1/5The prompt so far: 'Chai is best with'.
The big ideas
What you need to know
Decoder-only
Most chat LLMs are decoder-only transformers. They read left to right and predict what comes next.
Autoregressive loop
Each new token is appended to the input and the model runs again. That's why replies stream word by word.
Sampling picks the token
Temperature and top-p decide how adventurous the choice is. Temperature near 0 almost always picks the top token.
Weights hold the knowledge
Billions of learned numbers store patterns from training text. There's no lookup table of facts inside.
See it in code
Walk through the code
1# pip install transformers torch2import torch3from transformers import AutoTokenizer, AutoModelForCausalLM4 5tok = AutoTokenizer.from_pretrained("gpt2")6model = AutoModelForCausalLM.from_pretrained("gpt2")7 8ids = tok("Chai is best with", return_tensors="pt").input_ids9with torch.no_grad():10 logits = model(ids).logits[0, -1] # scores for the next token11 12probs = logits.softmax(-1)13top = probs.topk(5)14for p, i in zip(top.values, top.indices):15 print(repr(tok.decode(i)), round(p.item(), 3))1/3Load a small, old but open model. It's tiny enough for a laptop or free Colab.
Peek inside one step: GPT-2 gives a probability to every possible next token. Bigger models work the same way.
Save yourself the pain
Common mistakes
Oops
Thinking the model looks facts up in a database.
Do this instead
It predicts likely text from patterns in its weights. That's why it can sound confident and still be wrong.
Oops
Assuming the model plans the whole answer before writing.
Do this instead
It produces one token at a time. Asking it to outline first, then write, often gives better long answers.
Your mission
Watch the loop happen
Quick check
Why do chatbot replies appear word by word instead of all at once?
Go deeper
- 1Read a high-level explainer of how a decoder-only Transformer generates text token by token.
- 2Trace the path from input prompt to output tokens conceptually.
- 3Connect this back to the Transformer architecture you studied in Phase 8.
More topics at this stop
 Tokenization (BPE, SentencePiece)
 Pretraining vs Fine-tuning
 Context Window & Attention
 Popular LLMs (GPT, Claude, Gemini, Llama)
 Open-Source vs Closed-Source Models
 Model Scaling Laws (Overview)
 Emergent Abilities (Overview)
 Multimodal Models (Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
