
Open-Source vs Closed-Source Models
Part of the AI Engineer Roadmap
In short
Rent a model through an API, or download one and run it yourself? This choice affects your cost, your privacy story, how much you can customise, and who you call when it breaks.
Closed models (GPT, Claude) are accessed via API only; open-weight models (Llama, Mistral) can be downloaded, fine-tuned and self-hosted — a decision with major cost, control and privacy implications.
Think of it like this
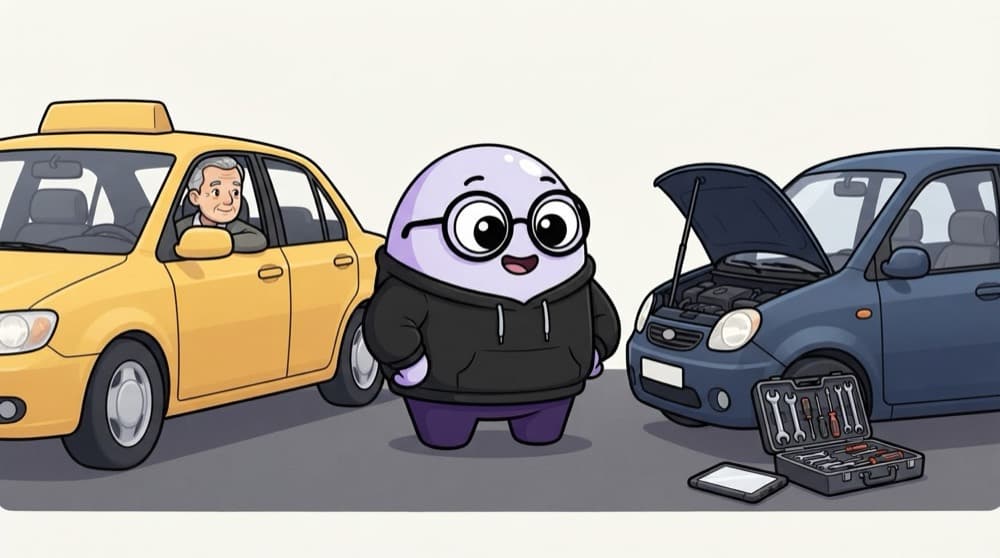
Cab vs your own car
Booking a cab is easy: no servicing, no parking, pay per ride. Owning a car means upfront cost and maintenance, but you go anywhere and can modify it. Closed models are the cab. Open-weight models are the car in your garage.
Watch it happen
Closed API vs open weights
Closed (API)
- No servers to manage
- Often the strongest models
- Data goes to the provider
Open weights
- Run on your own hardware
- Fine-tune and inspect freely
- You handle scaling and updates
Start with an API to prove the idea quickly. Move to open weights when privacy, cost at scale or deep customisation really demands it.
The big ideas
What you need to know
Open weights is not always open source
Many 'open' models share weights but not training data or code, and licences may limit some uses. Read the licence.
Privacy and control
Self-hosting keeps data in your network, which matters for hospitals, banks and government projects.
Hardware is the real cost
Bigger models need serious GPU memory. Quantised small models can run on a laptop, but slower and less capable.
Customisation
With weights you can fine-tune, quantise and change decoding freely. APIs offer only what the provider exposes.
See it in code
Walk through the code
1# Install Ollama from ollama.com, then:2ollama pull llama3.2 # downloads a small open-weight model3ollama run llama3.2 "Explain UPI in two lines."4 5# It also serves a local HTTP API on port 114346curl http://localhost:11434/api/generate \7 -d '{"model": "llama3.2", "prompt": "Hello", "stream": false}'1/2Download a small Llama model once, then chat with it from the terminal.
Ollama runs open-weight models on your own machine. Nothing leaves your laptop.
Save yourself the pain
Common mistakes
Oops
Assuming self-hosting is always cheaper.
Do this instead
GPUs, engineers and uptime cost money. At low traffic, a pay-per-token API is often cheaper overall.
Oops
Calling every downloadable model 'open source' and ignoring the licence.
Do this instead
Check what the licence allows, especially for commercial use, before building a product on it.
Your mission
Run a model offline
Quick check
A hospital wants patient notes summarised but cannot send data outside its network. What's the best fit?
Go deeper
- 1List the trade-offs: cost, control, privacy, latency, quality for each approach.
- 2Try running a small open-weight model locally (e.g. via Ollama).
- 3Learn when self-hosting actually makes financial sense vs. when it doesn't.
More topics at this stop
 LLM Architecture Overview
 Tokenization (BPE, SentencePiece)
 Pretraining vs Fine-tuning
 Context Window & Attention
 Popular LLMs (GPT, Claude, Gemini, Llama)
 Model Scaling Laws (Overview)
 Emergent Abilities (Overview)
 Multimodal Models (Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
