CI/CD for ML Pipelines
Part of the AI Engineer Roadmap
In short
In normal software, CI checks the code. In ML, a bad dataset or a worse model can slip through with perfect code. ML CI/CD adds checks for data and model quality too.
Automating testing, validation and deployment for ML code and models — extends standard CI/CD with ML-specific checks like data validation and model performance gates.
Think of it like this
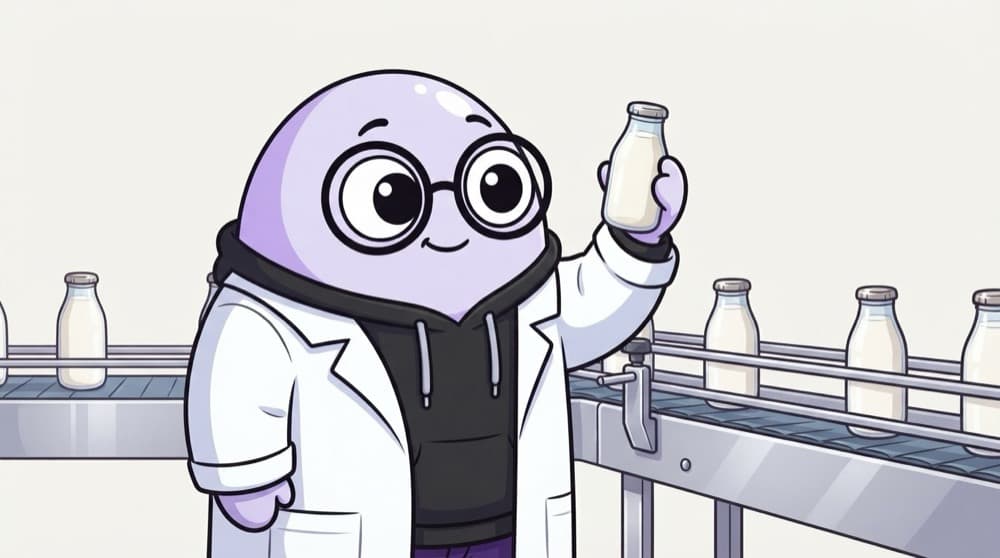
The dairy quality lab
Before milk packets leave a dairy, the lab tests every batch for fat and freshness. A bad batch never reaches the shop, even if the packing machine works perfectly. ML CI/CD is that lab: code tests, data checks and an accuracy gate before any model ships.
Watch it happen
From git push to a deployed model
1/6You push a change to the feature code. GitHub Actions starts the workflow.
The big ideas
What you need to know
Test code as usual
Feature functions and API handlers still need normal unit tests.
Validate the data
Check schema, ranges and null rates on every run. Bad data is the most common silent ML failure.
Gate on model quality
Fail the pipeline if the new model is worse than a threshold or than production.
Retrain on schedule
Many teams also run the pipeline on a timer or when new data lands, not only on code pushes.
See it in code
Walk through the code
1name: ml-ci2on: [push]3jobs:4 test-and-gate:5 runs-on: ubuntu-latest6 steps:7 - uses: actions/checkout@v48 - uses: actions/setup-python@v59 with:10 python-version: "3.12"11 - run: pip install -r requirements.txt12 - run: pytest tests/13 - run: python validate_data.py data/train.csv14 - run: python train.py --out model.joblib15 - run: python evaluate.py model.joblib --min-accuracy 0.851/4Run on every push to any branch.
A GitHub Actions workflow. Each run step must exit 0, so evaluate.py just exits with an error if accuracy is too low.
Save yourself the pain
Common mistakes
Oops
Gating only on 'training finished without errors'.
Do this instead
Training can finish and still produce a worse model. Gate on a real metric against a fixed validation set.
Oops
Committing a 500 MB dataset into the git repo for CI.
Do this instead
Store data in object storage or a data versioning tool like DVC, and pull it in the workflow.
Your mission
Add a quality gate
Quick check
Your code tests pass, but last week's data export had all labels set to 0. Which check catches it?
Go deeper
- 1Set up a CI pipeline that runs tests and a basic model-performance check on every push.
- 2Learn what should gate a deployment: code tests plus a minimum accuracy threshold.
- 3Automate retraining or redeployment triggers where it makes sense for your project.
More topics at this stop
 Model Serving (FastAPI/Flask)
 Docker for ML Models
 Model Versioning
 Experiment Tracking (MLflow, Weights & Biases)
 Model Monitoring & Drift Detection
 A/B Testing Models
 Batch vs Real-time Inference
 Kubernetes for ML (Overview)
 Feature Stores (Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
