Model Serving (FastAPI/Flask)
Part of the AI Engineer Roadmap
In short
A model sitting in a Jupyter notebook helps nobody. Wrap it in a small web API and suddenly your app, your friend's app and a mobile app can all use it.
Wrapping a trained model behind an HTTP API so other services can send it input and get predictions — the standard pattern for putting a model into production.
Think of it like this
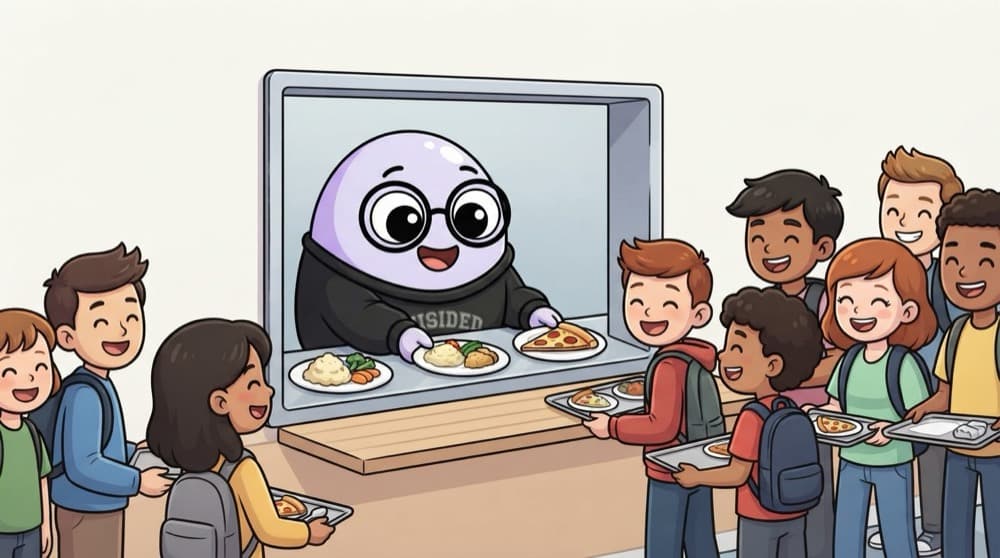
The canteen order window
The canteen cook preps the dough once in the morning, not for every order. Then students hand slips through the window and get parathas back. A model server loads the model once at startup, then answers request after request through one window: an HTTP endpoint.
Watch it happen
A prediction request
joblib.load() at start
1/6When the server starts, it loads the model into memory once. This can take seconds, so never per request.
The big ideas
What you need to know
Load once, predict many
Load the model at startup and keep it in memory. Loading per request makes every call painfully slow.
Validate inputs
Pydantic models reject wrong types and missing fields before they reach your model.
FastAPI vs Flask
Both work. FastAPI adds type-based validation, async support and auto docs at /docs. Flask is simpler and older.
Add a health check
A GET /health endpoint lets load balancers and Docker know your server is alive.
See it in code
Walk through the code
1from fastapi import FastAPI2from pydantic import BaseModel3import joblib4 5app = FastAPI()6model = joblib.load("spam_model.joblib") # loaded once at startup7 8class Msg(BaseModel):9 text: str10 11@app.post("/predict")12def predict(msg: Msg):13 label = model.predict([msg.text])[0]14 prob = model.predict_proba([msg.text])[0].max()15 return {"label": str(label), "confidence": round(float(prob), 3)}1/4The model is loaded at import time, once per server process.
A complete model server. Run it with uvicorn main:app --reload and open /docs to try it in the browser.
Save yourself the pain
Common mistakes
Oops
Calling joblib.load inside the predict function.
Do this instead
Load at startup. Reading a model file on every request adds big, pointless delay.
Oops
Returning numpy floats and getting a serialization error.
Do this instead
Convert with float() or int() before returning JSON.
Your mission
Serve your own model
Quick check
Your API takes 4 seconds per request, but the model predicts in 20 ms. What's the likely bug?
Go deeper
- 1Wrap a trained model in a FastAPI endpoint and test it with real requests.
- 2Learn to handle input validation and batch prediction efficiently.
- 3Add basic error handling for malformed or out-of-distribution inputs.
More topics at this stop
 Docker for ML Models
 Model Versioning
 Experiment Tracking (MLflow, Weights & Biases)
 CI/CD for ML Pipelines
 Model Monitoring & Drift Detection
 A/B Testing Models
 Batch vs Real-time Inference
 Kubernetes for ML (Overview)
 Feature Stores (Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
