Model Monitoring & Drift Detection
Part of the AI Engineer Roadmap
In short
Models don't crash loudly when the world changes. They quietly get worse. Monitoring watches the incoming data and predictions so you notice drift before your users or your boss do.
Tracking a deployed model's live performance and input distribution over time — catches silent failures like data drift that unit tests can never detect.
Think of it like this
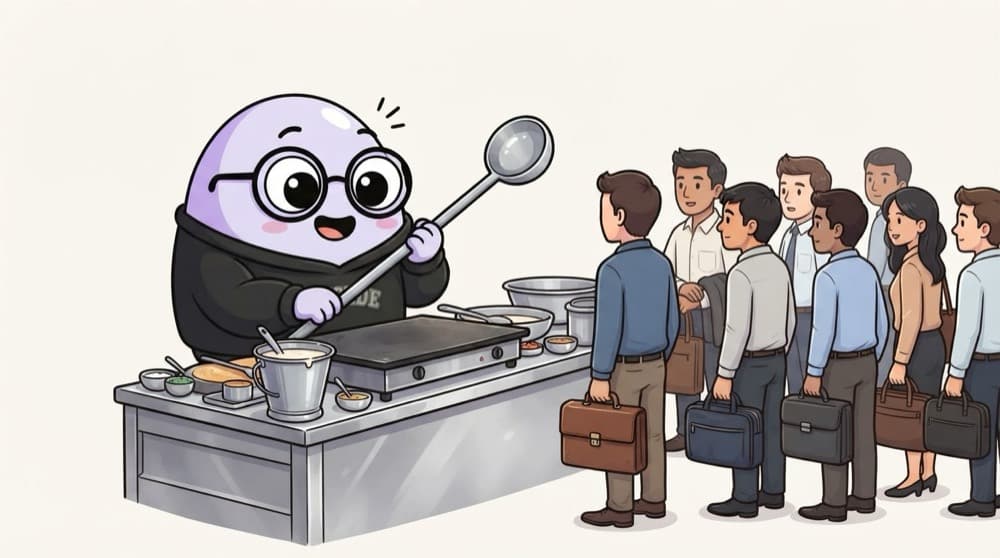
The dosa stall's new crowd
A dosa stall near a college plans its batter for hungry students. Then a big office opens next door and the crowd changes to office workers who want quick, plain dosas at 1 pm sharp. The old plan quietly stops working. That change in who shows up is data drift.
Watch it happen
Catching drift in production
requests
1/5Real users send data every minute. The model answers as usual.
The big ideas
What you need to know
Data drift
Input distributions change: new customer types, new devices, new prices. The model sees unfamiliar data.
Concept drift
The link between inputs and outcome changes. Same customers, but a new competitor changes who churns.
Labels arrive late
True outcomes may take weeks. Watch input and prediction drift as early warning signs.
Watch the basics too
Latency, error rates and missing values break things more often than subtle drift does.
See it in code
Walk through the code
1import numpy as np2from scipy.stats import ks_2samp3 4rng = np.random.default_rng(0)5train_age = rng.normal(22, 2, 5000) # students at launch6live_age = rng.normal(31, 5, 1000) # office crowd now7 8stat, p = ks_2samp(train_age, live_age)9if p < 0.01:10 print(f"Drift in 'age': KS={stat:.2f}, p={p:.1e}")1/3Ages seen in training versus ages arriving in production now.
A Kolmogorov-Smirnov test compares two distributions of one feature. Tools like Evidently run checks like this for every column.
Save yourself the pain
Common mistakes
Oops
Alerting on every tiny p-value from huge daily traffic.
Do this instead
With lots of data, trivial shifts become 'significant'. Also check effect size, and alert on meaningful changes.
Oops
Deploying a model and checking it only when someone complains.
Do this instead
Set up dashboards and alerts on day one: inputs, predictions, latency and, when available, accuracy.
Your mission
Simulate drift
Quick check
Customers look the same as before, but a new competitor changes who cancels. What kind of drift is that?
Go deeper
- 1Log prediction inputs/outputs from a deployed model for later analysis.
- 2Learn to detect data drift by comparing live input distributions to training data.
- 3Set up an alert for when live performance metrics drop below a threshold.
More topics at this stop
 Model Serving (FastAPI/Flask)
 Docker for ML Models
 Model Versioning
 Experiment Tracking (MLflow, Weights & Biases)
 CI/CD for ML Pipelines
 A/B Testing Models
 Batch vs Real-time Inference
 Kubernetes for ML (Overview)
 Feature Stores (Overview)

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
