In short
Without activation functions, a 100-layer network is no smarter than one straight line. These small functions add the bends that let networks learn real-world patterns.
Non-linear functions (ReLU, sigmoid, tanh, softmax) applied after each layer — without them, stacking layers would collapse into a single linear transformation.
Think of it like this
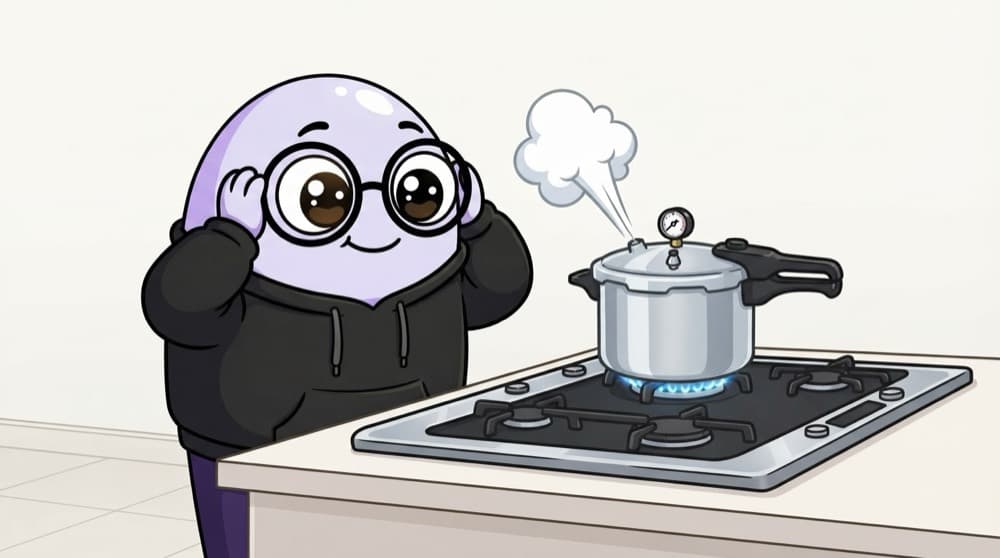
The pressure cooker whistle
A pressure cooker stays quiet while pressure is low. Once it crosses a limit, the whistle blows, and harder pressure means a stronger whistle. ReLU behaves like that: zero below the limit, then it grows with the input.
Watch it happen
Five inputs through different activations
1/5These are raw weighted sums, z, coming into a neuron.
The big ideas
What you need to know
Non-linearity is the point
Stacking linear layers gives another linear layer. Activations let the network bend its decision boundary.
ReLU for hidden layers
Fast and simple, and the usual default. Variants like Leaky ReLU and GELU fix some of its quirks.
Match the output layer
Sigmoid for one yes/no output, softmax for picking one of many classes, nothing for plain regression.
Vanishing gradients
Sigmoid and tanh flatten at the ends, so gradients shrink in deep networks. That's one reason ReLU took over.
See it in code
Walk through the code
1import numpy as np2 3z = np.array([-2.0, -1.0, 0.0, 1.0, 2.0])4 5relu = np.maximum(0, z)6sigmoid = 1 / (1 + np.exp(-z))7tanh = np.tanh(z)8softmax = np.exp(z) / np.exp(z).sum()9 10print(relu)11print(sigmoid.round(2), tanh.round(2))12print(softmax.round(2))1/3ReLU: keep positives, zero the rest.
The four activations from the scene, written in one line each with NumPy.
Save yourself the pain
Common mistakes
Oops
Putting softmax on the output of a regression model that predicts prices.
Do this instead
Use no activation (linear) for regression outputs. Softmax is only for picking among classes.
Oops
Using sigmoid in every hidden layer of a deep network.
Do this instead
Use ReLU or GELU in hidden layers. Keep sigmoid for a yes/no output.
Your mission
Plot the activations
Quick check
Your network must pick one of 5 flower types. Which activation fits the output layer?
Go deeper
- 1Plot ReLU, sigmoid, tanh and softmax to see their shapes and ranges.
- 2Learn why ReLU is the default choice for hidden layers (avoids vanishing gradients).
- 3Understand which activation belongs at the output layer for regression vs. classification.
More topics at this stop
 Neural Network Basics
 Perceptrons
 Forward & Backward Propagation
 Loss Functions
 Gradient Descent Variants (SGD, Adam)
 PyTorch Basics
 TensorFlow/Keras Basics
 Batch Normalization
 Dropout & Regularization in DL
 GPUs & CUDA Basics

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
