In short
Training a model on a CPU can take days. The same job on a GPU can take hours. Knowing how to move work onto a GPU, and why it helps, is everyday AI engineering.
GPUs parallelize the matrix operations behind neural networks, cutting training time from days to hours — understanding CUDA basics helps you debug device and memory issues.
Think of it like this
One professor vs a full exam hall
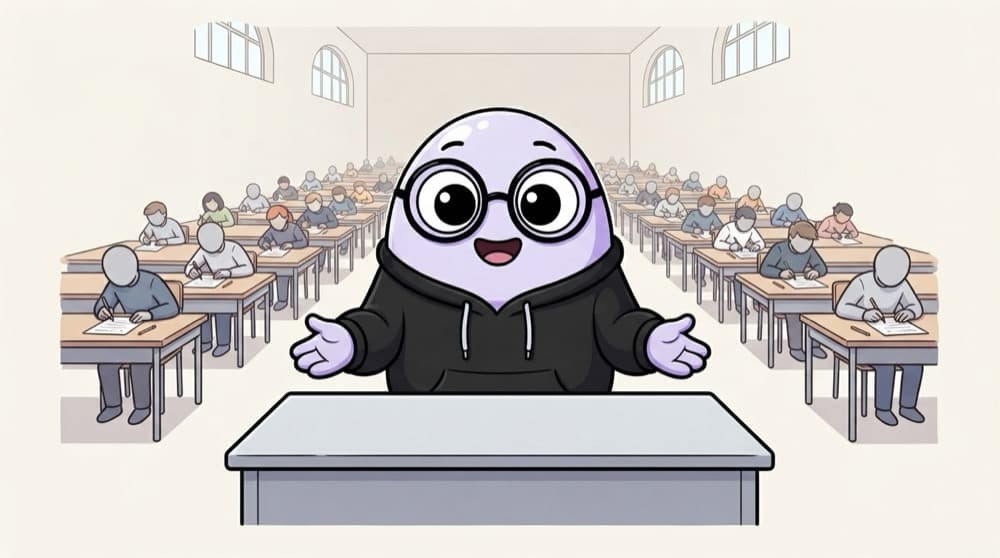
Give a professor a thousand simple sums and she'll do them one by one, very fast. Give the same sums to an exam hall of a thousand students, one each, and they're done in one go. A CPU is the professor. A GPU is the exam hall.
Watch it happen
Running a layer on the GPU
model.to('cuda')
1/5The model's weights are copied from normal RAM into the GPU's own memory.
The big ideas
What you need to know
Deep learning is matrix maths
Layers are mostly big matrix multiplications, which split into many small independent sums. That's perfect for parallel cores.
CUDA is NVIDIA's toolkit
CUDA lets programs run on NVIDIA GPUs. PyTorch and TensorFlow call CUDA libraries for you, so you rarely write kernels yourself.
VRAM is the limit
Model weights, activations and optimiser state all need GPU memory. 'CUDA out of memory' means lower the batch size or model size.
Copying costs time
Moving data between RAM and GPU is slow compared to compute. Keep tensors on the GPU and avoid moving them back and forth.
See it in code
Walk through the code
1import torch2 3device = "cuda" if torch.cuda.is_available() else "cpu"4print("using", device)5 6model = torch.nn.Linear(1024, 1024).to(device) # weights move to GPU memory7x = torch.randn(4096, 1024, device=device) # data created on the GPU8 9y = model(x) # runs as GPU kernels across thousands of cores10print(y.device) # cuda:0 on a GPU machine11result = y.cpu() # copy back to RAM before using NumPy1/3Pick the GPU if one is available, otherwise fall back to the CPU.
The same code runs on CPU or GPU. The only change is where the tensors live.
Save yourself the pain
Common mistakes
Oops
Moving the model to the GPU but forgetting the input batch.
Do this instead
Both model and data must be on the same device. Move each batch with batch.to(device) inside the loop.
Oops
Calling .item() or .cpu() on every step inside the training loop.
Do this instead
Each call waits for the GPU and copies data. Log every 100 steps instead of every step.
Your mission
Time CPU vs GPU
Quick check
You get 'Expected all tensors to be on the same device'. What's the likely cause?
Go deeper
- 1Train a model on GPU vs. CPU and compare training time directly.
- 2Learn to diagnose and fix common CUDA out-of-memory errors.
- 3Understand mixed-precision training as a way to speed up GPU training further.
More topics at this stop
 Neural Network Basics
 Perceptrons
 Activation Functions
 Forward & Backward Propagation
 Loss Functions
 Gradient Descent Variants (SGD, Adam)
 PyTorch Basics
 TensorFlow/Keras Basics
 Batch Normalization
 Dropout & Regularization in DL

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
