In short
Deep networks can train slowly because each layer's inputs keep shifting as earlier layers learn. Batch normalisation steadies those inputs, so you can often train faster and with bigger learning rates.
A technique that normalizes layer inputs during training, stabilizing and speeding up convergence in deep networks.
Think of it like this
Assembly line-up
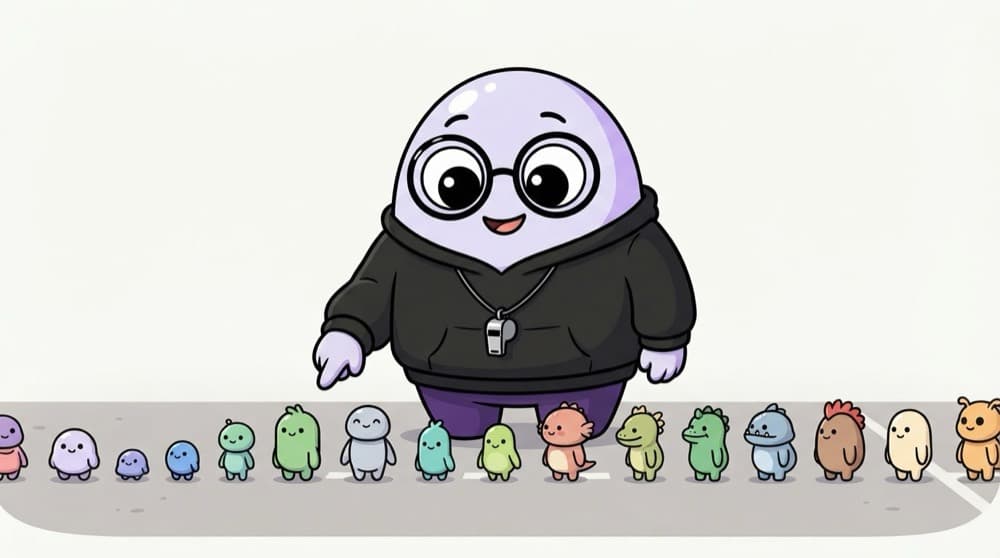
At morning assembly, the PT teacher makes every row stand evenly spaced before marching starts, no matter how messy they arrived. Batch norm does that for each layer: whatever comes in, it's re-centred and evenly spread before moving on.
Watch it happen
Normalising one feature over a batch of 5
1/4One neuron's outputs for five examples in a batch. They're large and spread out.
The big ideas
What you need to know
Normalise per batch
During training, each feature is centred and scaled using the current mini-batch's mean and variance.
Learnable scale and shift
Gamma and beta are trained like weights, so the network can undo normalisation if that helps.
Train vs eval behave differently
At inference, batch norm uses running averages saved during training, not the current batch. Always call model.eval().
Small batches hurt it
With batches of 2 or 4, the batch statistics are noisy. Layer norm, used in transformers, avoids this.
See it in code
Walk through the code
1import torch2import torch.nn as nn3 4model = nn.Sequential(5 nn.Linear(20, 64),6 nn.BatchNorm1d(64), # normalise each of the 64 features over the batch7 nn.ReLU(),8 nn.Linear(64, 2),9)10 11x = torch.randn(32, 20) # a batch of 32 rows12model.train() # uses this batch's mean and variance13out_train = model(x)14model.eval() # uses running averages saved during training15out_eval = model(x[:1]) # works even for a single row1/3BatchNorm1d(64) matches the 64 outputs of the Linear layer before it.
BatchNorm usually sits between a linear or conv layer and its activation. The train/eval switch matters.
Save yourself the pain
Common mistakes
Oops
Forgetting model.eval() before testing, so results change with batch size.
Do this instead
Call model.eval() for validation and inference, and model.train() before training resumes.
Oops
Adding batch norm everywhere in a transformer.
Do this instead
Transformers use layer normalisation, which normalises across features of each example instead of across the batch.
Your mission
With and without batch norm
Quick check
At inference time, which statistics does a BatchNorm layer use?
Go deeper
- 1Train a deep network with and without batch norm and compare training stability.
- 2Learn where batch norm layers are typically placed relative to activations.
- 3Understand the difference in batch norm behavior between training and inference mode.
More topics at this stop
 Neural Network Basics
 Perceptrons
 Activation Functions
 Forward & Backward Propagation
 Loss Functions
 Gradient Descent Variants (SGD, Adam)
 PyTorch Basics
 TensorFlow/Keras Basics
 Dropout & Regularization in DL
 GPUs & CUDA Basics

Stuck on this topic? Ask an Insider
Get 1:1 guidance from people who've walked this exact path — on the InsideEdge app.
